VIALS-AA: frontier models tie on lab-image reasoning, costs differ 29x
- Source
- x.com
- Date

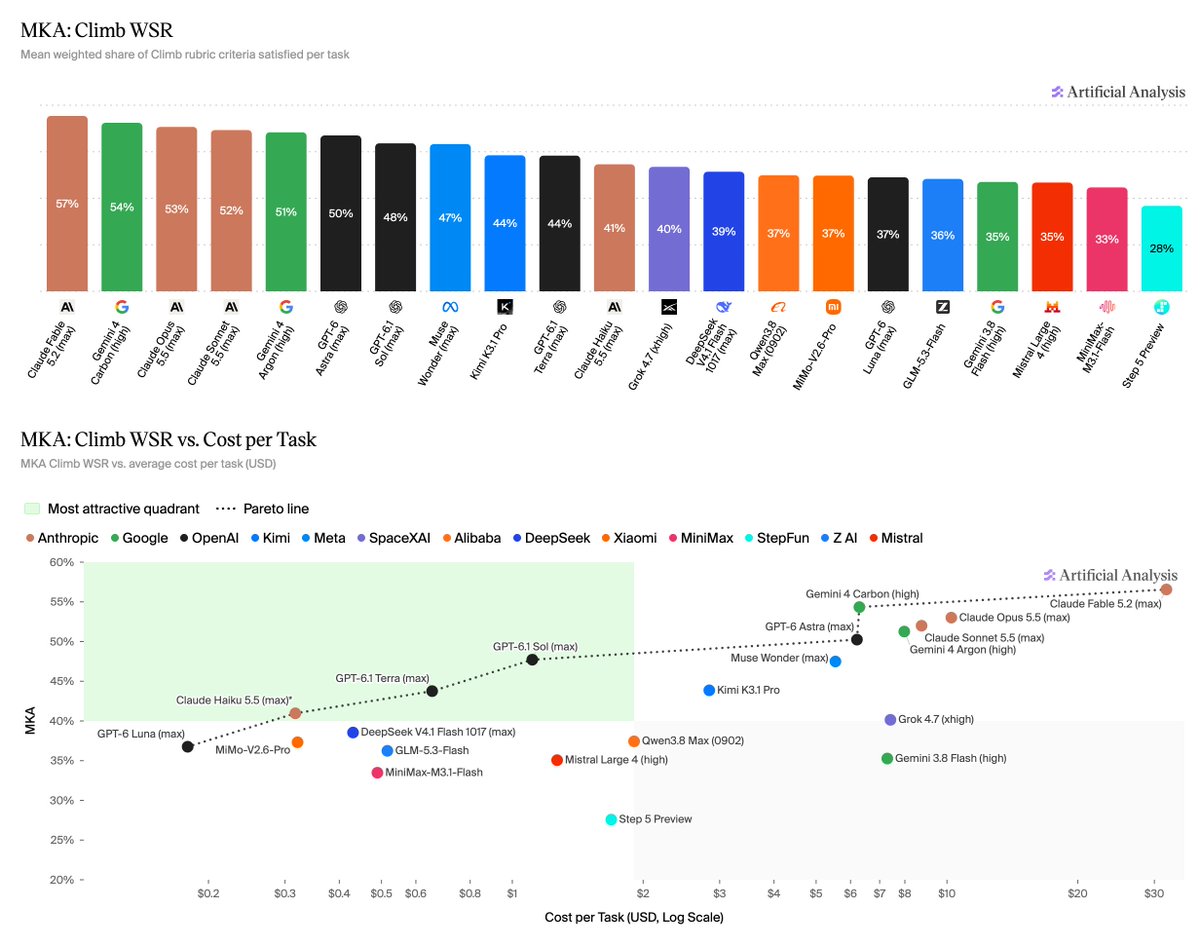
We’re launching VIALS-AA, a leaderboard for Handshake AI’s VIALS benchmark for visual reasoning in life sciences and biotech research Visual artifacts are central to how scientists analyze experiments and make research decisions, but interpreting them correctly remains a challenge for frontier models. VIALS’ 161 tasks span eight domains and need models to reason over artifacts including gel blots, flow cytometry plots, plasmid maps, and phylogenies. Each task requires models to interpret an artifact and draw a specific scientific conclusion. We evaluate models by running each task three times in Stirrup, our open source agent harness, with code execution and image inspection tools. GPT-6 Luna (medium) grades each answer against the reference answer, and we report the share of tasks judged correct in all three repeats (pass^3). Key takeaways: ➤ The top three models are separated by 3 points: Gemini 4 Carbon (high) from @GoogleDeepMind leads narrowly with 64%, followed by GPT-6 Astra (max) from @OpenAI at 63% and Claude Opus 5.5 (max with fallback) from @AnthropicAI at 61% ➤ Astra and Sol achieve similar scores to Opus and Sonnet at a much lower Cost per Task: Claude Opus 5.5…

Top models sit within 3 points on VIALS-AA, but cost per task varies about 29x, driven by turns and tool calls. Requiring three consistent passes sharply reorders open-weights models, a useful check when choosing agents for visual reasoning.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Checking sign-in…
Loading comments…