Mistral ships Voxtral 3 and a voice agents API
- Source
- x.com
- Date

Introducing Voxtral 3: state-of-the-art Transcribe and Speech models powering Mistral’s new voice agents API. 🧵

Context
Mistral AI introduced Voxtral 3, describing its Transcribe and Speech models as state of the art and as the engine behind a new voice agents API. Only the thread's opening post was collected, so this note relies on that post and an automatic transcript of its demo video. The video's visuals were not analyzed, and any , pricing or availability details later in the thread are not covered.
The demo explains what a voice built on this API is: three stages at once, not one model. The agent in the video says Voxtral Transcribe listens and detects when a speaker's turn ends, Mistral Large reasons over the conversation, and the latest Voxtral speech model turns the reply into audio. Because the stages overlap, the agent can be cut off mid-sentence and keep up, and it says it is diarizing, meaning telling the two human speakers apart, in real time. On request it switches between English, French and German, and it says it can call tools such as web search and that an SDK connects it to custom systems. Asked about speed, it says most voice agents take about a second to respond and that it targets under a second. These are things shown or stated in a promotional demo, not measured results.
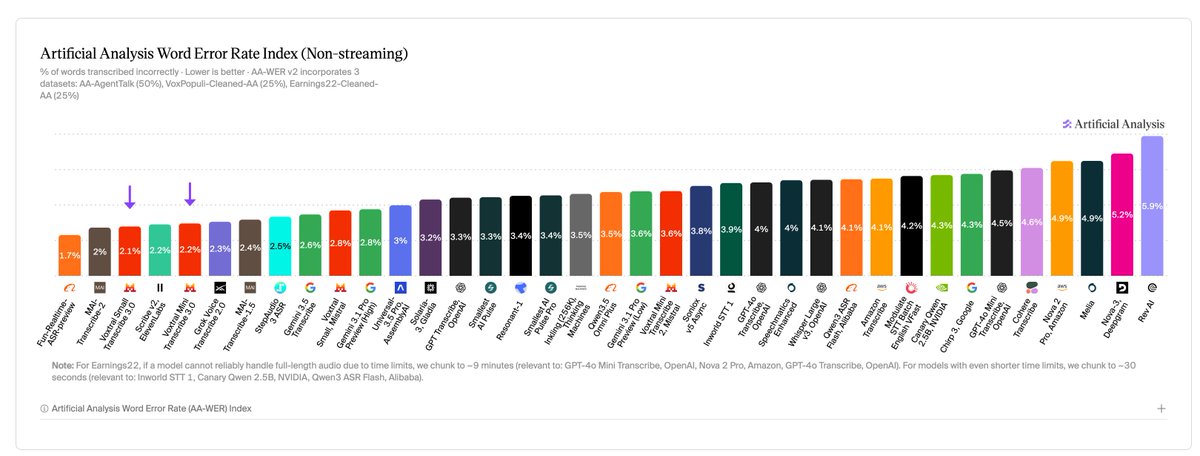
For an outside view of the component models, Artificial Analysis evaluated Voxtral 3 the same day. It placed Voxtral Small Transcribe 3 third on its speech-to-text leaderboard and the Voxtral 3 TTS model in the top 12 of both its text-to-speech arenas. That is a more mixed picture than a blanket state-of-the-art claim, and it covers the individual models rather than the latency of the full agent pipeline.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.

Checking sign-in…
Loading comments…