Tencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
Source
Tencent Hy
Date
From the Daily Brief
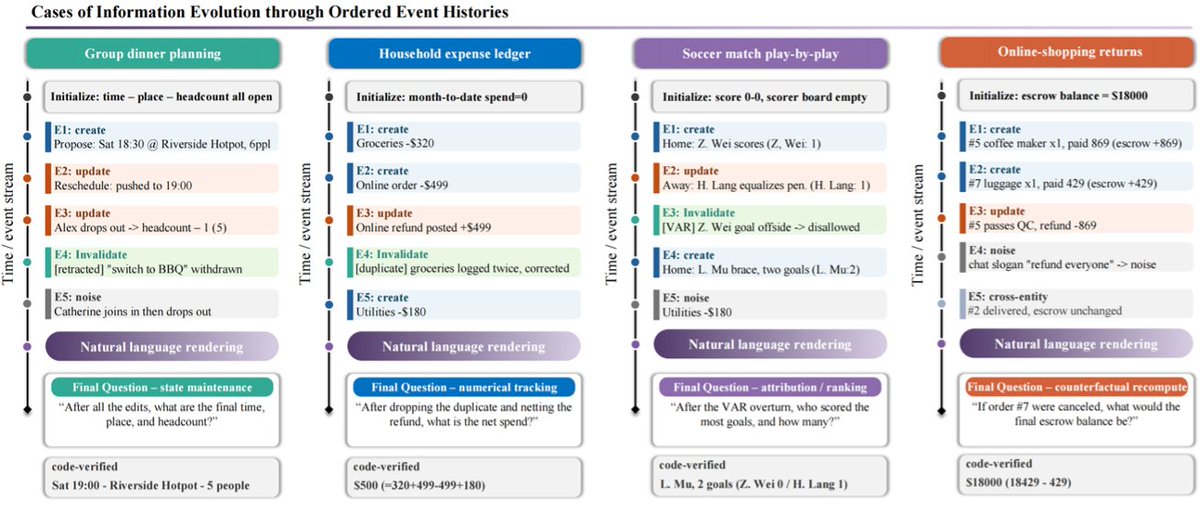
Tencent Hunyuan released EvolveScaler, a benchmark that tests whether a model can reconstruct accurate ground truth from event logs where individual records get retracted and corrected after the fact, the way real operational data behaves. On the hardest tier, frontier models' accuracy falls to 11.3 percent, a collapse from the scores those same models post on static, unchanging benchmarks. The benchmark also shows that training on this kind of evolving data raises out-of-distribution scores by 5.25 points, suggesting the failure is not fundamental but a gap in what models have been trained to handle. The result is a useful corrective for anyone evaluating a model on log analysis, monitoring, or any task where the underlying facts change after ingestion: a model that scores well on a fixed benchmark can still fail badly the moment the data it reasons over gets revised, which is closer to how production logs actually behave than most current evaluation sets.
🚀 EvolveScaler is here.
Read a 40-day RPG log. Now answer one question: if you skip the mini-boss on Day 7, do you still beat the final boss?
The answer isn't in the log. You have to replay the world.
That's Information Evolution — records get retracted, corrected, backfilled. The world keeps changing after you read it.
So we build it backwards: define the world as an executable state machine, then render it into natural language. Code guarantees the logic. Language delivers the mess.
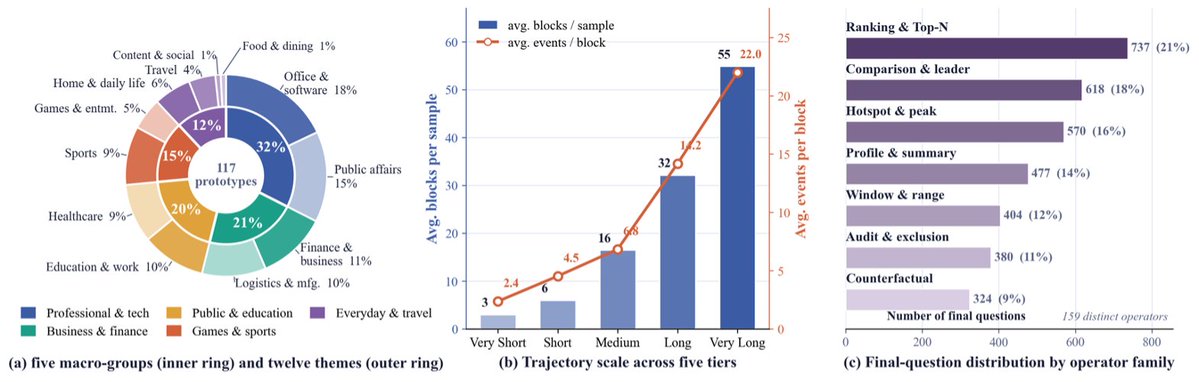
➡️ 117 prototypes. 159 question operators. 5 difficulty tiers. Up to ~1,200 events per sample.
➡️ 14 frontier models, hardest tier: median avg@5 falls to 11.3.
➡️ Train on it instead: +5.25 average across 8 out-of-distribution benchmarks.
Check out our paper and project page.
📚 Paper: https://t.co/wmDPkSiwre
🏠 Project Page: