Playing Well With Others
- Source
- mercor.com
- Author
- Mercor research blog
- Date
Context
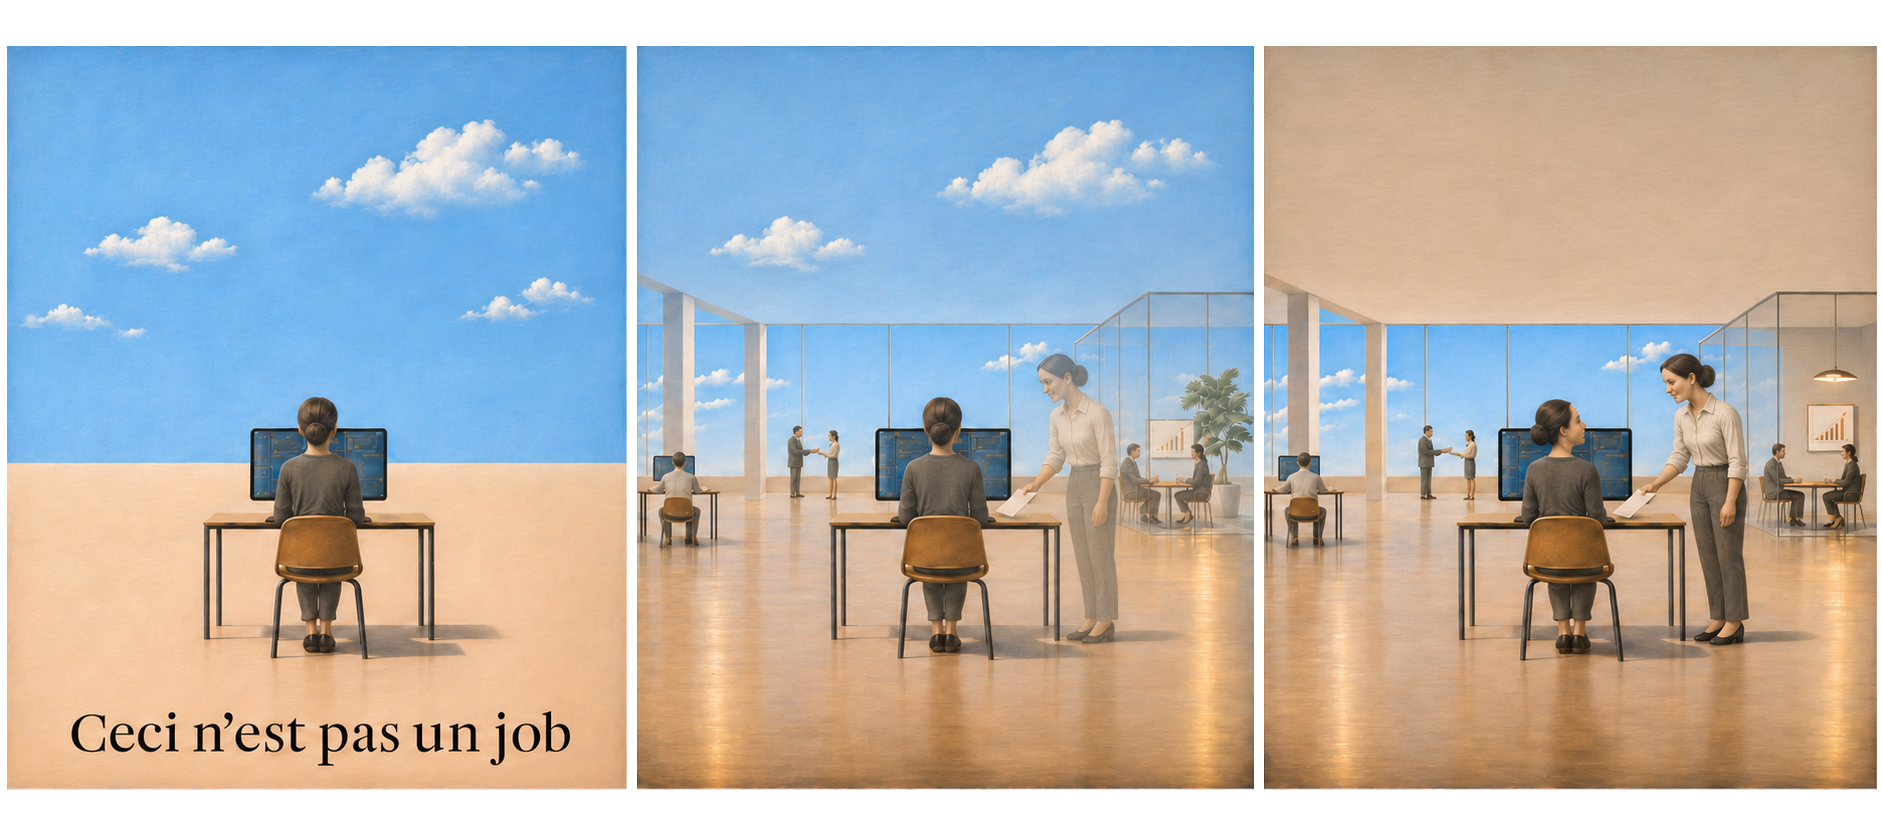
Researchers at Mercor, a company that builds AI evaluations of professional work, argue that gains do not by themselves answer whether AI can do a job, because jobs are done inside organizations and benchmarks rarely test that part (Mercor). With Nicolai J. Foss and Henrik M. Nielsen of Copenhagen Business School, they separate technical difficulty, how hard a task is once its goal, inputs and authority to act are given, from organizational difficulty, which comes from how the task depends on other people. Their example is a bug fix that needs only a few lines of code, but whose logs sit with a hard-to-reach support team, whose code belongs to a billing team that must approve the change, whose product manager doubts it is a bug at all, and whose deadline an account manager has already promised the customer.
To measure the gap, they propose a preliminary taxonomy with four layers: the structure of work, such as who holds information and who has authority; the coordination that structure requires; the governance mechanisms that meet it, such as a ticket queue or release calendar; and how performance is judged. They then labeled around 500 benchmarks drawn from industry indices, top machine-learning conference papers and benchmarks reported in major labs' model cards. Fewer than a quarter claim to build in any of the six structure-of-work dimensions, and only 16% report a separate result for one. When authority does appear, it is almost always a written policy in the prompt, unlike real workplaces where several chains of authority overlap and can shift mid-task.
The authors stress that this does not make these benchmarks easy or worthless, and that is growing: 14% of prominent benchmarks from 2023 claimed an organizational dimension, against 33% of those published in 2026. Their point is that the productivity gains from progress on well-specified tasks may be limited unless models also improve at the coordination and approvals that surround the task. The taxonomy is a proposed vocabulary for building such tests, not a measurement of how well current models handle organizational work.
- Mercor and Copenhagen Business School researchers separate organizational difficulty (who holds information, who must approve, what was promised) from technical difficulty, and treat the two as independent: a bug fix can be technically easy but organizationally hard.
- Their taxonomy has four layers: the structure of work creates coordination requirements, which organizations meet through governance mechanisms such as ticket queues or release calendars, and results are judged by performance outcomes.
- Across about 500 benchmarks from industry indices, top ML conference papers and lab model cards, fewer than a quarter claim any of six structure-of-work dimensions, and task interdependence is very rarely represented.
- When benchmarks do include authority, it is almost always a written policy in the prompt, whereas real work involves overlapping explicit and implicit chains of authority that can shift mid-task.
- The share of prominent benchmarks claiming an organizational dimension rose from 14 percent in 2023 to 33 percent of those published in 2026, though the forms remain narrow.
Checking sign-in…
Loading comments…