← All IntelClip / Other
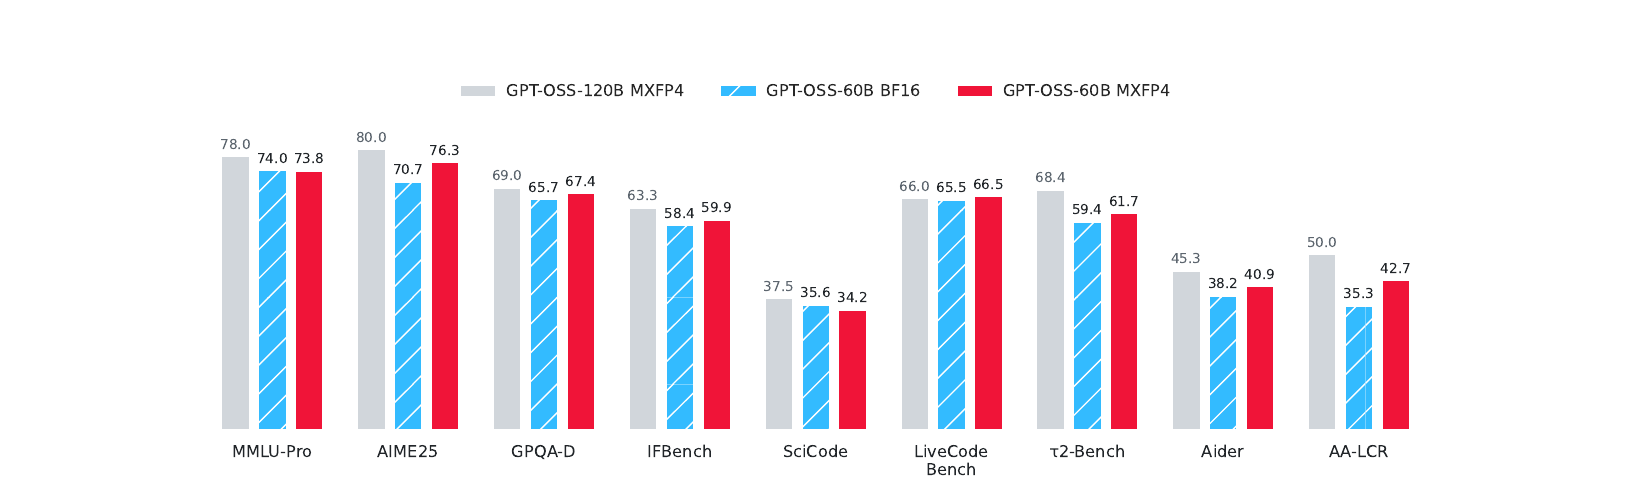
Model labs already ship quantized formats (Q8, MXFP4)
From Compression at the Edge — Chris Alexiuk, NVIDIA · ≈25:33
“So I do think as long as there's a demand for being able to run kind of personal language models even if compression didn't exist there would be analogous techniques or you know maybe model training would look a little bit different.”
What’s in it
- Explains why quantized formats like Q8 and MXFP4 exist
- Compares compressed large models vs smaller full-precision ones
- Argues compression is driven by demand for personal LLMs
Clip transcript
releasing smaller size models um things like Q8 at or you know with GPOSS it was MXFP4 which is a different format. So I do think as long as there's a demand for being able to run kind of personal language models even if compression didn't exist there would be analogous techniques or you know maybe model training would look a little bit different. Um obviously that comes everything comes at a trade-off. Um, as Daniel was mentioning, you know, you can have a really large model being condensed down into something smaller so you can run it versus even just having um a full precision model but smaller in parameter size. And they both come with different trade-offs. it matter of fact like how how do you see the open source
Recommended reads
Comments
Checking sign-in…
Loading comments…