The Big LLM Architecture Comparison
- Source
- magazine.sebastianraschka.com
- Author
- Sebastian Raschka, PhD
- Date
Context
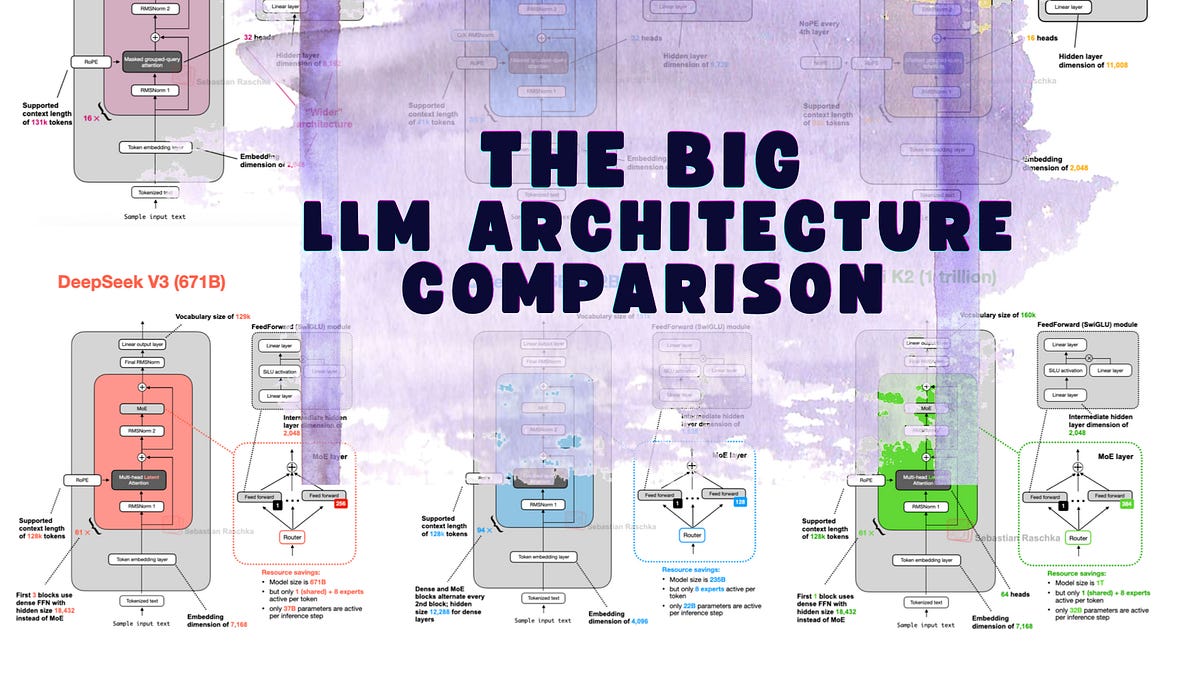
A model's total parameter count can be much larger than the number it uses for each token. DeepSeek documents this distinction for V3: the main model has 671 billion parameters, with 37 billion activated per token.
Sebastian Raschka's architecture comparison explains the mechanism. layers contain multiple neural subnetworks, and a router chooses a subset for each token. This lets the model hold a large collection of learned parameters without applying all of them at every step. Comparing model sizes therefore requires distinguishing total capacity from the amount of computation activated during generation.
- Multi-head latent squeezes key/value tensors into a smaller space before they enter the , then expands them back at inference. One extra matrix multiply buys the memory saving, and DeepSeek-V2's ablations had it beating plain multi-head attention on quality.
- DeepSeek V3 carries 671B parameters but runs only 37B per token: each mixture-of-experts layer holds 256 expert feed-forward blocks, of which a router picks 8, plus one shared expert that fires for every token.
- The always-on shared expert exists so every specialist doesn't relearn the same common patterns. It absorbs the generic work and leaves the routed experts room to specialize, an idea that traces back to the 2022 DeepSpeedMoE paper.
- Seven years of architecture progress is largely substitutions on the same GPT skeleton: absolute position became rotary (RoPE), multi-head attention became grouped-query attention, GELU became SwiGLU. The block diagram barely moved.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
“MLA is a clever trick to reduce KV cache memory use while even slightly outperforming MHA in terms of modeling performance.”
Sebastian Raschka
“At that moment we did not find significant enough improvement on shared expert and we were worrying about the optimization for inference caused by shared expert. No straight answer to this question honestly.”
Junyang Lin
“As of this writing, Kimi K2 is the most impressive open-weight model.”
Sebastian Raschka
“In my opinion, a bit of extra normalization can't hurt.”
Sebastian Raschka
Checking sign-in…
Loading comments…