How OpenAI uses Codex to chip away at its maintenance backlog
- Source
- developers.openai.com
- Author
- OpenAI DevelopersTop Viber
- Date
Context
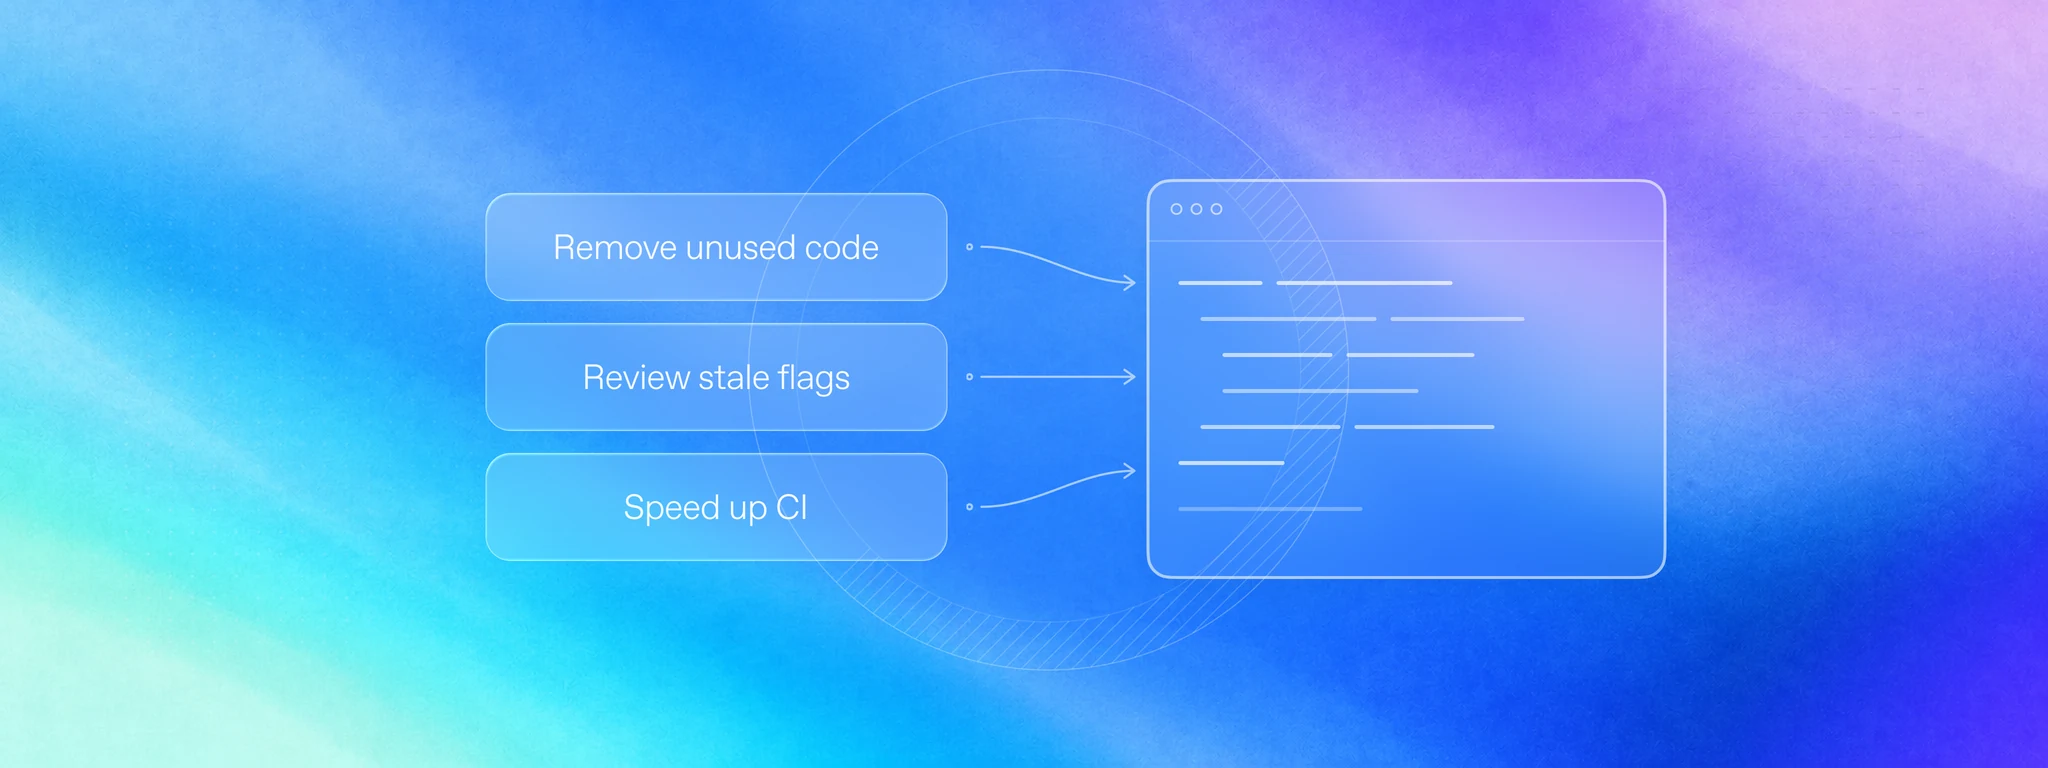
An engineer on OpenAI's Core Experimentation team describes in a developers blog post how the team used Codex to work through its maintenance backlog: dead code, stale experiments and feature flags, flaky tests and slow CI. The main change the author reports is in how much the request had to spell out. With GPT-5.6 Sol, the author named an area to investigate and clear validation criteria, then had the model write static analysis to find unused code. A short, loosely worded request to find and clean up dead code across the repository, checking Slack or the Statsig experimentation platform as needed, was too ambiguous for GPT-5.6 Sol to handle completely. GPT-6 Astra handled it by reading past pull requests, Slack threads, internal project trackers and production profiling tables to confirm the lines it deleted were never reached, and it explained each deletion, which the author says sped up review.
Five engineers then ran variations of that prompt across repositories, mostly part-time over two weeks, and merged more than 1,400 pull requests that deleted over 800,000 lines, with reviews sent to the teams that knew each project. One service's container image shrank from 3.31GB to 1.72GB. Stale experiments were harder because their code may still run in production behind feature flags, switches that turn code paths on or off for some users. The team's earlier scripts missed many truly stale ones. The author had Astra draft a prompt to audit every Statsig gate, config and experiment, trace indirect uses, weigh CPU cost from production telemetry and group candidates into a report, without touching live configuration. The top results were large efficiency wins from experiments nobody had flagged as stale for years. In one case Astra found that a single line mapping an internal override flag to every feature was causing heavy CPU fan-out, but raised it for human review because the flag was marked Permanent. Removing it saved an estimated 0.42% of CPU in the main affected service.
The post also compares cost. The author ran the same stale-experiment prompt over subdirectories covering more than 6,000 files and a million lines of Python, TypeScript, Go and Rust, then validated the findings. GPT-6 Astra at Ultra effort produced 142 findings for $109.06 in API cost. GPT-6.1 Sol, which OpenAI launched as near-Astra capability at a lower price, produced 131 at Ultra effort for $15.12 and 86 at Medium for $5.27. That puts Sol Ultra at 92% of Astra's findings for 14% of the cost. Most of the gap came from constant flags used as dependencies of other flags, which Astra caught and Sol missed. The author treats patterns like that as something to correct in the prompt, while noting that new models can make such corrections unnecessary.
A further prompt asked Codex to rank ideas for cutting CI load by minutes saved, based on the repository's run history. The team landed about 30 resulting changes, and median CI completion time fell from roughly 10 minutes to 4.5. Adding one missing mock cut a 63-test suite from 592.6 to 29.8 seconds. The author also notes that some proposals added more complexity than they were worth, so measurement and prioritization stayed part of the process, and suggests starting with one small task, comparing models and effort levels on it, and widening the scope only once the results hold up in review.
- A short, typo-laden Codex prompt had GPT-6 Astra check past PRs, Slack, trackers and production profiles to justify each deletion; five engineers, doing the bulk part-time over two weeks, merged 1,400+ PRs removing 800k+ lines.
- Astra flagged a "Permanent" override flag that fanned out across all feature flags for human review rather than deleting it; after review the team removed it, for an estimated 0.42% CPU saving in the main affected service.
- Most of GPT-6.1 Sol's misses against GPT-6 Astra on the stale-experiment audit were constant feature flags used as dependencies of other flags, a pattern the author says can be corrected in the prompt so the cheaper model closes the gap.
- A prompt asking Codex to rank CI-relief ideas by minutes saved led to about 30 PRs that cut median CI time from about 10 to 4.5 minutes and p90 from 12.5 to 6; later, adding a missing mock cut a 63-test suite from 592.6s to 29.8s.
- The author warns some proposals added more complexity than they saved, and advises starting with one small task, comparing models and effort levels on it, and feeding review comments into the next prompt before scaling up.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.


Checking sign-in…
Loading comments…