Wafer says it beat Cerebras on latency for YC's AI Office Hours
- Source
- wafer
- Date

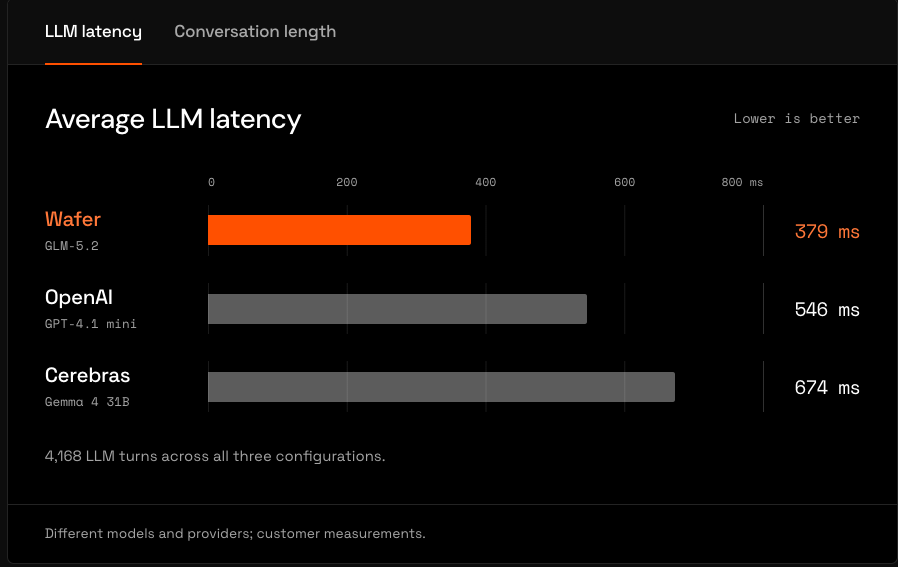
Wafer beat Cerebras on latency for @ycombinator's AI Office Hours. GLM-5.2 on Wafer averaged 379 ms versus 674 ms for Gemma 4 31B on Cerebras. that's 44% lower latency with a much larger model. YC wanted people to get startup advice from AI versions of its partners at conversational speed. after testing lightweight Gemma and OpenAI models, they moved to a dedicated Wafer endpoint. Wafer agents tuned the serving setup for YC’s request rate, cache usage, and prompt and response lengths. users spent 2.5 minutes longer talking to its AI partners on Wafer compared to other providers. read how YC built the experience and landed on Wafer 🧵 link in thread
@ycombinator Read YC's Story: https://t.co/ruwnPCng5w
Wafer says it served a larger GLM-5.2 model at 379ms average latency versus 674ms for a smaller Gemma model on Cerebras in YC's live AI Office Hours product, a 44% latency cut that let users hold longer conversations.
Checking sign-in…
Loading comments…