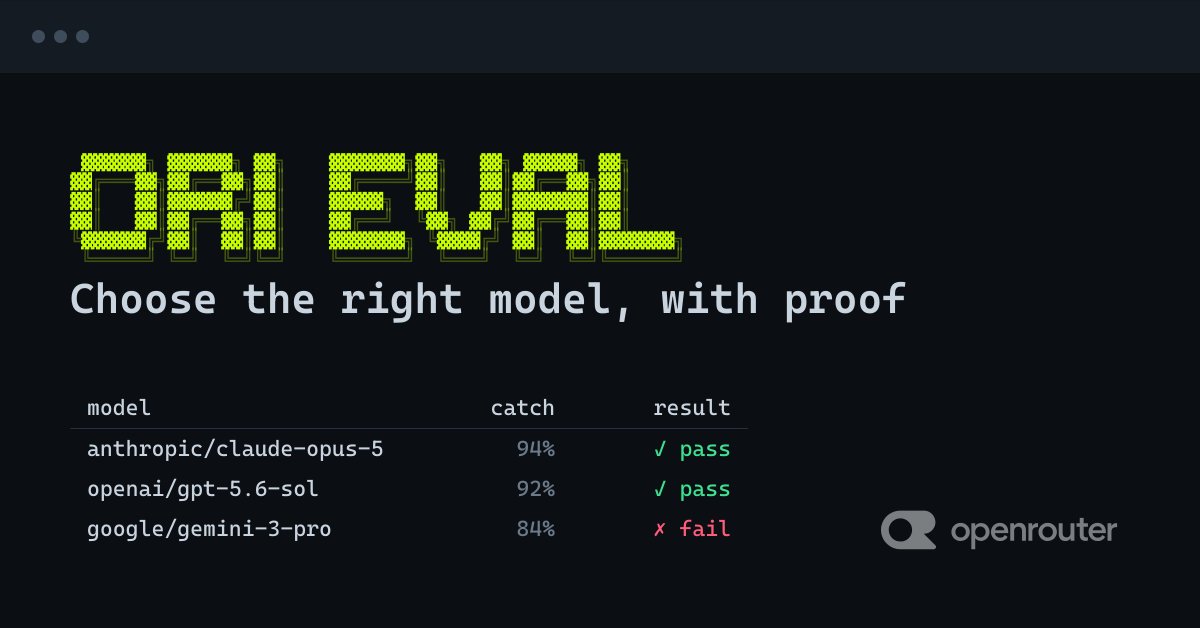
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Why it matters
It shows a working automation pattern for testing new model releases within hours instead of days, letting teams treat model choice as an empirical, continuously-updated decision instead of a one-time integration cost.