Alisa Liu is a member of technical staff at OpenAI, working on pretraining. Her research studies how training data and inference-time methods change language-model behavior, including human-AI data creation and controlled generation.[1][2][3][4]
Start with WANLI: Worker and AI Collaboration for Natural Language Inference Dataset Creation →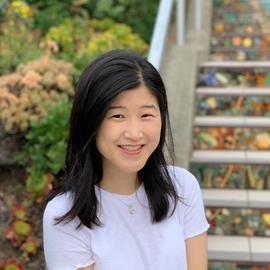
 X
Background
Liu earned a bachelor’s degree at Northwestern with majors in computer science and mathematics, then completed a computer-science PhD at the University of Washington in 2026 with Yejin Choi and Noah Smith. Her research spans data creation, inference-time adaptation and tokenization. She joined OpenAI in June 2026 after an academic collaboration with NVIDIA and earlier research internships at Google and the Allen Institute for AI.[1][2]
Contributions
Human judgment in generated training data
Liu is first author of WANLI, a natural-language-inference dataset built through worker-AI collaboration. The method identifies challenging reasoning patterns in existing data, asks GPT-3 to generate related examples, filters them, and then has people revise and label the results. This shifts human effort toward evaluation and correction. The paper evaluates whether the resulting dataset improves generalization outside the original training distribution, rather than simply maximizing the number of generated examples.[3]
Steering generation with experts and anti-experts
She also led the DExperts paper. At decoding time, it combines a language model’s output with smaller expert and anti-expert models. Tokens gain probability when the expert favors them and lose it when the anti-expert does. The method works at the output distribution, so it can steer a larger model without retraining its parameters. The experiments examine toxicity reduction and sentiment control, using both automatic metrics and human evaluation.[4]
Tools, writing & talks
Writing, research & talks
Start here
Explains a dataset-creation pipeline that combines generated examples with human revision.
Read the pipeline diagram and sample examples before comparing evaluation results. Basic familiarity with training datasets is useful; the human-generation-and-review division is understandable without implementing a model.
First author[3]- Alisa's book of LLMsalisawuffles.notion.site
Alisa Liu's public study notebook works through the modern LLM stack end to end: transformer internals, inference tricks like speculative decoding and KV cache reduction, parallelism, and post-training methods like GRPO and DPO, with worked derivations.
Catalog workOriginal source A method for steering generated text through a combination of model outputs.
First author[4]