Anna Goldie is founder and CEO of Ricursive Intelligence, an AI lab focused on chip design. She co-led AlphaChip at Google and has also worked on language-model research, including RAPTOR and multi-step reinforcement learning.[1][3][4]
Start with A graph placement methodology for fast chip design →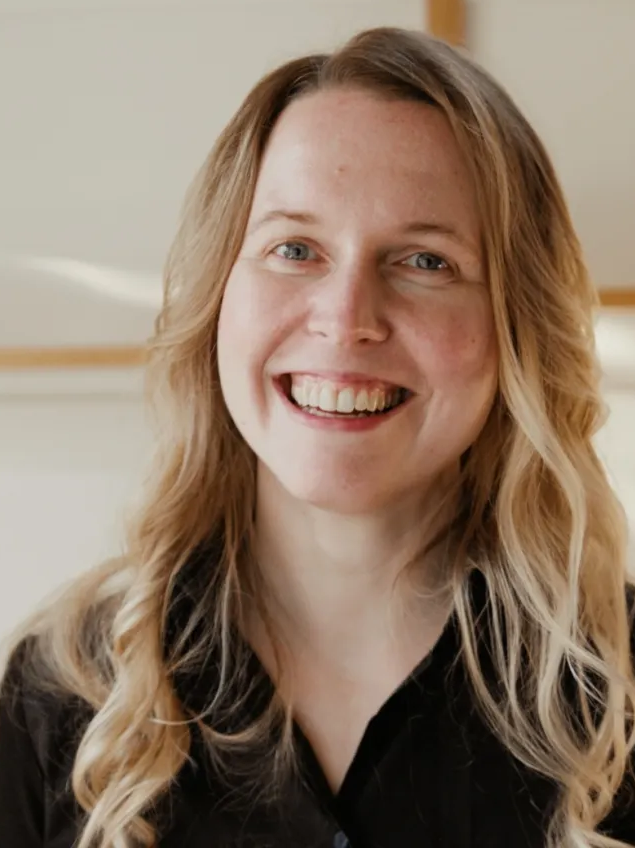
 X
Background
Goldie earned a computer-science PhD in Stanford’s NLP group. She also holds MIT bachelor’s degrees in computer science and linguistics and a master’s degree in electrical engineering and computer science. Her publication list spans spoken-language systems, machine translation, computer systems and reinforcement learning. That range is visible in her later work: some projects improve the physical systems on which computation runs, while others improve how a language model retrieves information or learns to take a sequence of actions.[1][3][4]
Career
Goldie is founder and CEO of Ricursive Intelligence, which her personal site describes as a frontier AI lab targeting chip design. Previously, she was a senior staff research scientist at Google DeepMind and an early employee at Anthropic, working on Gemini and Claude. She also co-founded and led Google Brain’s ML for Systems team. She also co-led AlphaChip, bringing reinforcement learning to a design problem in which many placement choices must be evaluated together.[1]
Contributions
Learning to arrange a chip
Goldie is a co-first author of the Nature paper A graph placement methodology for fast chip design. Chip floorplanning means choosing the physical layout of a chip’s components, where placement affects properties such as power use, performance and area. The paper casts this as a reinforcement-learning problem and uses a graph-based neural network to represent the chip. The method draws on prior placement experience when tackling a new design. The authors report comparable or better floorplans than human-produced baselines on their evaluated metrics, and use in Google’s AI accelerators.[2][1]
Retrieval at more than one scale
Goldie co-authored RAPTOR, which addresses a limitation of retrieving only short passages for a language model. The method repeatedly groups and summarizes text to build a tree: lower levels retain local details, while higher levels summarize larger portions of the material. At question-answering time, the system can retrieve information at different levels of abstraction. The paper’s experiments test whether this structure helps with questions that require connecting information across a document. It offers a useful example of changing the information supplied to a model without treating the model itself as the whole system.[3]
Training sequences of decisions
In SWiRL, Goldie and her co-authors study language-model tasks that require several reasoning or tool-use steps before a final answer. Their method generates multi-step data, decomposes a trajectory into smaller pieces associated with individual actions, and applies filtering and reinforcement-learning optimization to those pieces. They evaluate question answering, mathematical reasoning and tool-use tasks, reporting improvements over the compared baselines. The work extends the focus from judging a completed answer to learning from the sequence that produces it.[4]
Tools, writing & talks
Writing, research & talks
Start here
Begin with the abstract and overview figure to understand how chip layout becomes a sequence of decisions. This is the most direct starting point for her current focus.
The abstract and first figure explain the concrete chip-layout problem behind her current company’s research focus.
Introduces SWiRL, which trains on pieces of multi-step reasoning and tool-use trajectories. Best read after becoming familiar with reinforcement learning for language models.
Co-author; first listed author[4]