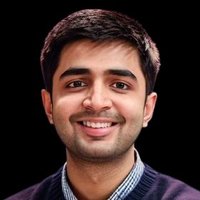
Avi Chawla writes Daily Dose of Data Science, a publication teaching data science, machine learning and AI engineering through short explanations and visual guides. His recent work covers the practical behavior of language-model systems, including caching and evaluation.[1][2]
Start with 11 LLM Evaluation Methods →
Education

Links
Publication Newsletter LinkedIn X · _avichawla
Founder and writer · Daily Dose of Data Science
Career
Daily Dose of Data Science presents its material as continuing education for working practitioners. Its archive covers the path from data analysis and machine learning to retrieval, language-model serving, agent memory and production workflows. Individual explanations are paired with visual material or code so readers can connect a term with an operation. Chawla’s professional profile also records study at IIT (BHU), Varanasi from 2016 to 2020. His public writing is the central professional output documented by the publication.[2][5]
Contributions
Explaining repeated computation
Chawla’s prompt-caching guide distinguishes the stable opening of a request from the conversation that changes on each turn. A provider can reuse computation for a matching prefix rather than processing those same tokens again. The article connects that mechanism to prompt organization: keep stable instructions and tool definitions together, then append changing messages and results. This gives a developer a concrete reason to examine context layout when an agent’s repeated calls become expensive.[3]
Choosing what a good answer means
His evaluation guide starts with a simple failure of text-overlap metrics: an answer can be correct while using different words from a reference. It compares methods that examine wording, semantic similarity, model judgments and an agent’s sequence of actions. The point is to choose a measure that reflects the task rather than treating one score as a universal definition of quality. That distinction matters when an application must both answer correctly and use tools appropriately.[4]
Tools, writing & talks
Writing, research & talks
Start here
11 LLM Evaluation Methodsblog.dailydoseofds.comA guide to matching evaluation methods to the kind of correctness an application needs.
Start with the evaluation guide to see why different tests reward different answers. Familiarity with model outputs helps; you can read the examples without setting up a model.
Bylined author.[4]A primer on eleven LLM evaluation methods, opening with why two metrics can rank the same models in opposite orders: a paraphrase scores near zero on BLEU and near the top on BERTScore.
Catalog workOriginal sourceHow prompt caching works and why it matters: an agent resends its whole conversation every turn, so system instructions, tool definitions and project context are re-read and re-billed each time, with a case study reaching a 92% cache hit rate.
Catalog workOriginal source- Prompt Caching in LLMsblog.dailydoseofds.com
Explains stable prompt prefixes, reused computation and practical context organization.
Bylined author.[3] - Daily Dose of Data Scienceblog.dailydoseofds.com
An archive of short lessons and projects across data science and AI engineering.