Bogdan Gaza is cofounder and CTO of DatologyAI, which builds infrastructure for curating model-training data. He brings infrastructure engineering and management experience from Amazon, Twitter and the startup Moonsense.[1]
Start with Curating Our Way to a State-of-the-Art Text Dataset →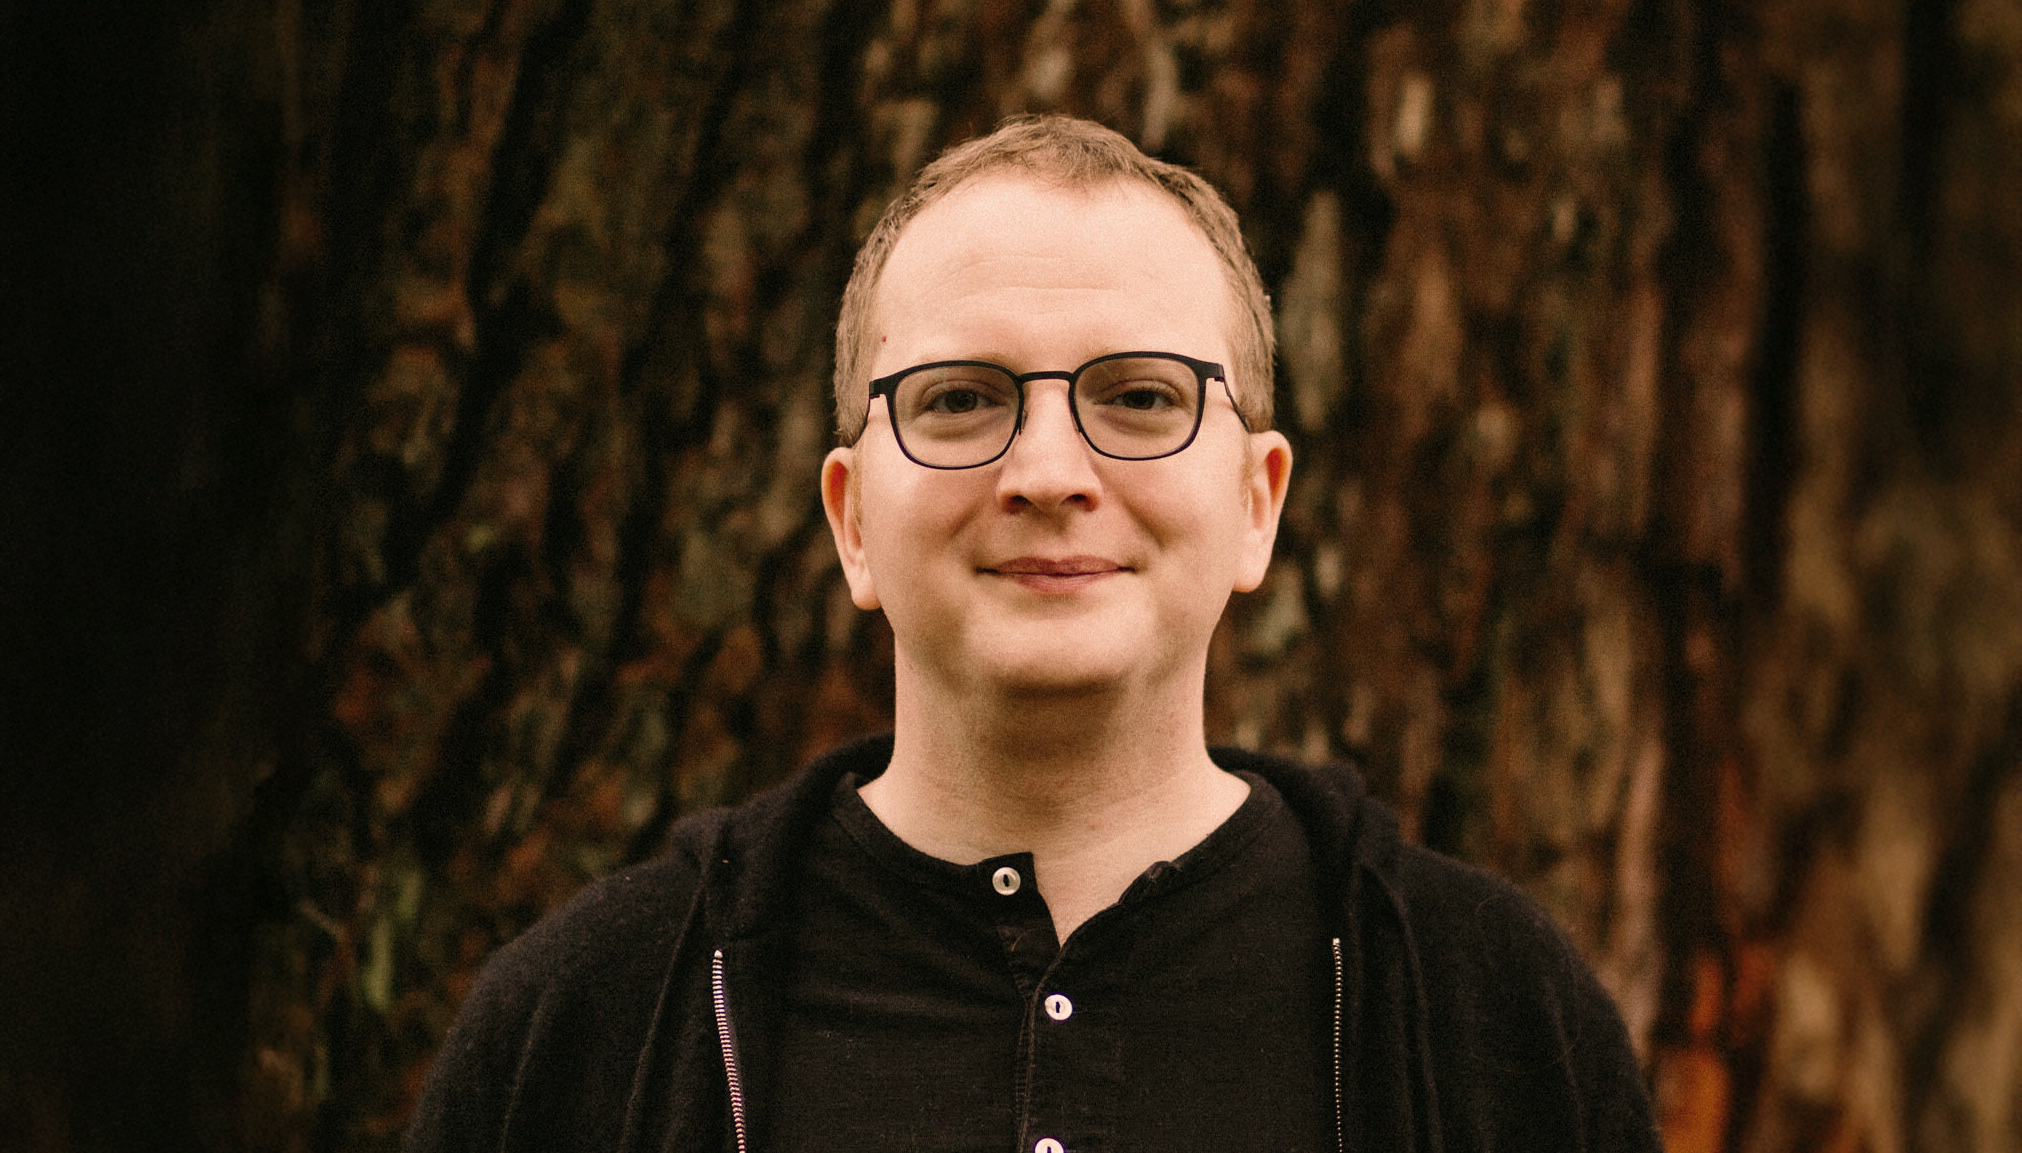
Links
LinkedIn X · hurrycane
Cofounder and CTO · DatologyAI
Career
Before DatologyAI, Gaza was CTO and cofounder of Moonsense. His employer biography also identifies more than a decade of infrastructure engineering and management at Amazon and Twitter. At DatologyAI, he works with a team studying how the choice and processing of training examples affects a model’s quality and the computation needed to train it.[1]
Contributions
DatologyAI’s text-curation technical report credits Gaza for leadership and advising. The team combines model-based filtering, embedding-based filtering and synthetic data in a production pipeline. It starts with RedPajama V1 and compares models trained on the curated output with models trained on several public datasets, keeping model families and training budgets explicit. This separates the effect of the data from simply making the model larger.[2]
Ideas
The report evaluates the resulting models on language-model benchmarks and asks three related questions: whether better data improves accuracy, reduces training needed for a target score, or lets a smaller model reach stronger performance. Its experiments extend to 2.7-billion-parameter models and 180-billion-token budgets. Those bounds define what the reported results establish, rather than proving the same gains for every model or workload.[2]
Tools, writing & talks
Writing, research & talks
Start here
Curating Our Way to a State-of-the-Art Text Datasetdatologyai.comA controlled comparison of text curation, model quality, training compute and inference efficiency.
Start with the text-curation report if you understand the basics of model training. Compare its datasets and fixed training budgets before interpreting the headline improvements.
Credited for leadership and advising[2]DatologyAI's CTO details running synthetic data generation at about 12 trillion tokens: rephrasing-based recipe, migration from Slurm/Kubernetes to Ray on EKS, and fixes for S3 metadata, GPU failures, scheduling and vLLM tuning.
Catalog workOriginal source