Charles Frye works at Modal on AI infrastructure and explains the relationship between GPU hardware, model inference and application performance. He also teaches the foundations of machine learning and neural networks.[1][2]
Start with A high-level guide to GPU utilization →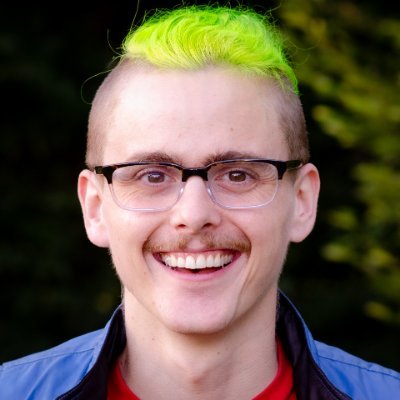
Education
Undergraduate degree, Biology; minor, Computational Neuroscience
Completed 2013
[2]
Links
Website GitHub
 X · charles_irl
Member of Technical Staff · Modal
Background
Frye completed an undergraduate biology degree with a computational-neuroscience minor at the University of Chicago in 2013. He subsequently did his PhD at UC Berkeley’s Redwood Center for Theoretical Neuroscience, focusing on artificial neural networks. His personal biography describes earlier work at Weights & Biases producing documentation, technical demonstrations and videos, followed by Full Stack Deep Learning teaching and community work.[2]
Contributions
Utilization means more than one number
His GPU utilization guide distinguishes time spent running a GPU kernel from how fully the hardware is used during that kernel. A busy GPU can still leave important arithmetic or memory resources underused. The guide connects the measurement to the bottleneck a developer is trying to fix, helping readers avoid treating a single monitoring percentage as a complete performance diagnosis.[3]
Keep the GPU supplied with work
With Nathan Wang and Timothy Feng, Frye explains host overhead: CPU-side work can delay GPU execution and leave the accelerator idle. Their article shows how to recognize the resulting low kernel utilization and discusses changes to production inference engines. Modal’s GPU Glossary credits Frye with writing most of its material, extending the same explanatory approach into a reference for hardware and programming terminology.[1][4]
Tools, writing & talks
Writing, research & talks
Start here
Separates different utilization measurements and relates them to performance bottlenecks.
Read the utilization guide before tuning an inference server. Basic knowledge of CPUs and GPUs helps; the guide teaches which measurements distinguish a busy device from an efficiently used one.
Author[3]Modal's Charles Frye walks through the inference engine pipeline from tokenization to detokenization, using SGLang and vLLM. Covers scheduler bottlenecks, KV cache, CUDA graphs, speculative decoding, and logging token IDs to debug correctness.
Catalog workOriginal sourceExplains how CPU work can stall an accelerator and how inference engines reduce that overhead.
Coauthor[1]- GPU Glossarymodal.com
A reference for GPU hardware, programming and performance concepts.
Primary material author[4]