Fei-Fei Li is World Labs’ co-founder and CEO, Stanford’s Sequoia Professor of Computer Science, and a founding co-director of Stanford HAI. Her work spans ImageNet, computer vision, and models of three-dimensional worlds.[1][2]
Start with With spatial intelligence, AI will understand the real world →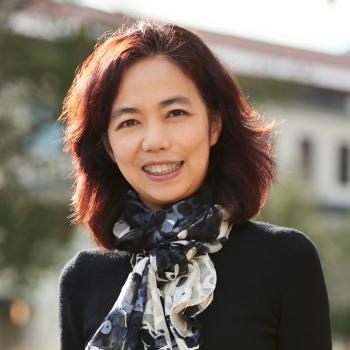
Education
Links
Stanford profile World Labs Essays X
Co-director, Human-Centered AI Institute · Stanford University
Co-founder and CEO · World Labs
Sequoia Professor of Computer Science · Stanford University
Background
Li studied physics at Princeton, receiving her bachelor’s degree in 1999, then completed graduate work in electrical engineering at Caltech. Stanford records a master’s degree in 2001 and a doctorate in 2005. Her research interests now include deep learning, robotic learning, spatial intelligence, and ambient intelligence for healthcare. These connect visual perception with systems that must interpret or act within their surroundings.[1]
Career
Li directed the Stanford Artificial Intelligence Laboratory from 2013 to 2018 and has co-directed Stanford’s Human-Centered AI Institute since 2019. Her Stanford biography records a Google vice-presidency and the Google Cloud chief scientist role for AI and machine learning in 2017–2018. She now leads World Labs, whose other founders are Justin Johnson, Ben Mildenhall, and Christoph Lassner. AMD announced an agreement to acquire World Labs on September 28, 2026. The announcement places Li’s proposed AMD executive vice-president and chief scientist appointment after closing, expected by year-end subject to approvals. It does not establish that she has already started that role.[1][2][3]
Contributions
ImageNet made recognition measurable
ImageNet gave computer-vision researchers a shared collection of labeled images and a common way to compare recognition systems. Li co-authored the ImageNet Large Scale Visual Recognition Challenge paper, which describes tests for classifying object categories and detecting objects within images. The paper also examines annotation challenges and compares computer performance with human accuracy. Its value is the combination of data and evaluation: a researcher can ask whether a method improves on the same task, rather than compare results from unrelated image collections.[4]
A concrete route into spatial intelligence
World Labs describes Marble as its first product, generating persistent three-dimensional worlds from inputs including images, video, text, and layouts. For an introduction to the broader idea, begin with her TED2024 talk. It connects visual perception, prediction, and action without requiring familiarity with model architectures. The ImageNet paper is the next step for understanding her earlier contribution to evaluating machine vision.[2][7][4]
Ideas
In her essay on world models, Li separates three functions: renderers produce observations such as images, simulators represent the state of an environment, and planners choose actions. The distinction helps explain why a plausible-looking video is insufficient evidence that a system understands geometry or physical dynamics. She argues that simulation matters because people and computer programs need environments they can inspect and interact with, not only watch.[5]
Tools, writing & talks
Writing, research & talks
Start here
A nontechnical talk connecting visual perception, prediction, and action. Start here before the research papers.
Speaker[7]- From Words To Worldsworldlabs.ai
Fei-Fei Li argues that language models remain ungrounded in physical space, and that spatial intelligence, perceiving and reasoning about 3D worlds, is the next capability frontier behind robotics, simulation and immersive creation. The founding thesis behind World Labs' world models.
Catalog workOriginal source Explains the dataset, annotation process, and shared recognition tests that made progress comparable across research teams.
Co-author[4]- A Functional Taxonomy of World Modelsdrfeifei.substack.com
Separates image rendering, simulation, and planning by the outputs each produces. Useful when judging what a world-model demonstration actually establishes.
Author, with World Labs team contributions acknowledged[5]