Filip Makraduli is a developer relations engineer at Modal and a machine-learning engineer focused on model inference. He coauthored FlashNorm and contributes software and explanations for making transformer inference more efficient.[1][2]
Start with Weight Folding, CUDA Streams, and the Bug That Made My Model Speak Backwards →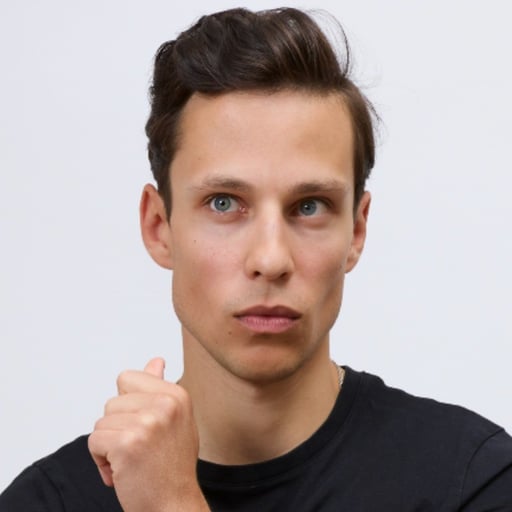

 X
Career
Makraduli describes earlier work at Superlinked as a founding member of technical staff, contributing to its inference engine and developer adoption. His current public profile identifies him as a developer relations engineer at Modal. He completed a master’s degree at Imperial College London. His engineering and teaching both focus on the details that determine whether an efficient model design produces a faster running system.[1]
Contributions
Move normalization work around a matrix multiply
FlashNorm reformulates an RMSNorm layer followed by a linear projection. It folds the learned normalization weights into the linear weights and moves the scalar normalization so that work can execute in parallel with the matrix multiplication. In applicable layer sequences, scale invariance also allows a normalization step to be removed. The paper tests these algebraic changes and reports operation-level latency under specified hardware and model conditions.[2]
Turn an algebraic identity into a working optimization
In his talk, Makraduli discusses the implementation work behind FlashNorm, including GPU execution and a bug that reversed generated text. He credits Nils Graef with originating the idea and describes his own role as a coauthor and implementer. The account illustrates why proving two expressions equivalent is only part of an optimization: the code still has to preserve tensor ordering, numerical behavior and useful parallel execution.[3]
Tools, writing & talks
Writing, research & talks
Start here
A talk on implementing and debugging the optimization.
Watch the normalization-and-matrix-multiply example before reading the paper’s equations. Familiarity with transformer layers helps; the debugging story explains why execution details matter alongside the algebra.
Speaker[3]- Weight Folding, CUDA Streams, and the Bug That Made My Model Speak Backwards — Filip Makraduliyoutube.com
Filip Makraduli explains FlashNorm: folding RMSNorm's gain into projection weights and overlapping the scalar divide on a separate CUDA stream, for a 33-35% speedup, plus the race condition that briefly made outputs echo the previous token.
Catalog workOriginal source An algebraic reformulation that reduces and overlaps normalization work in transformer layers.
Coauthor[2]
Tools
- Transformer Tricks
 github.com
Open implementations and experiments for transformer optimizations.