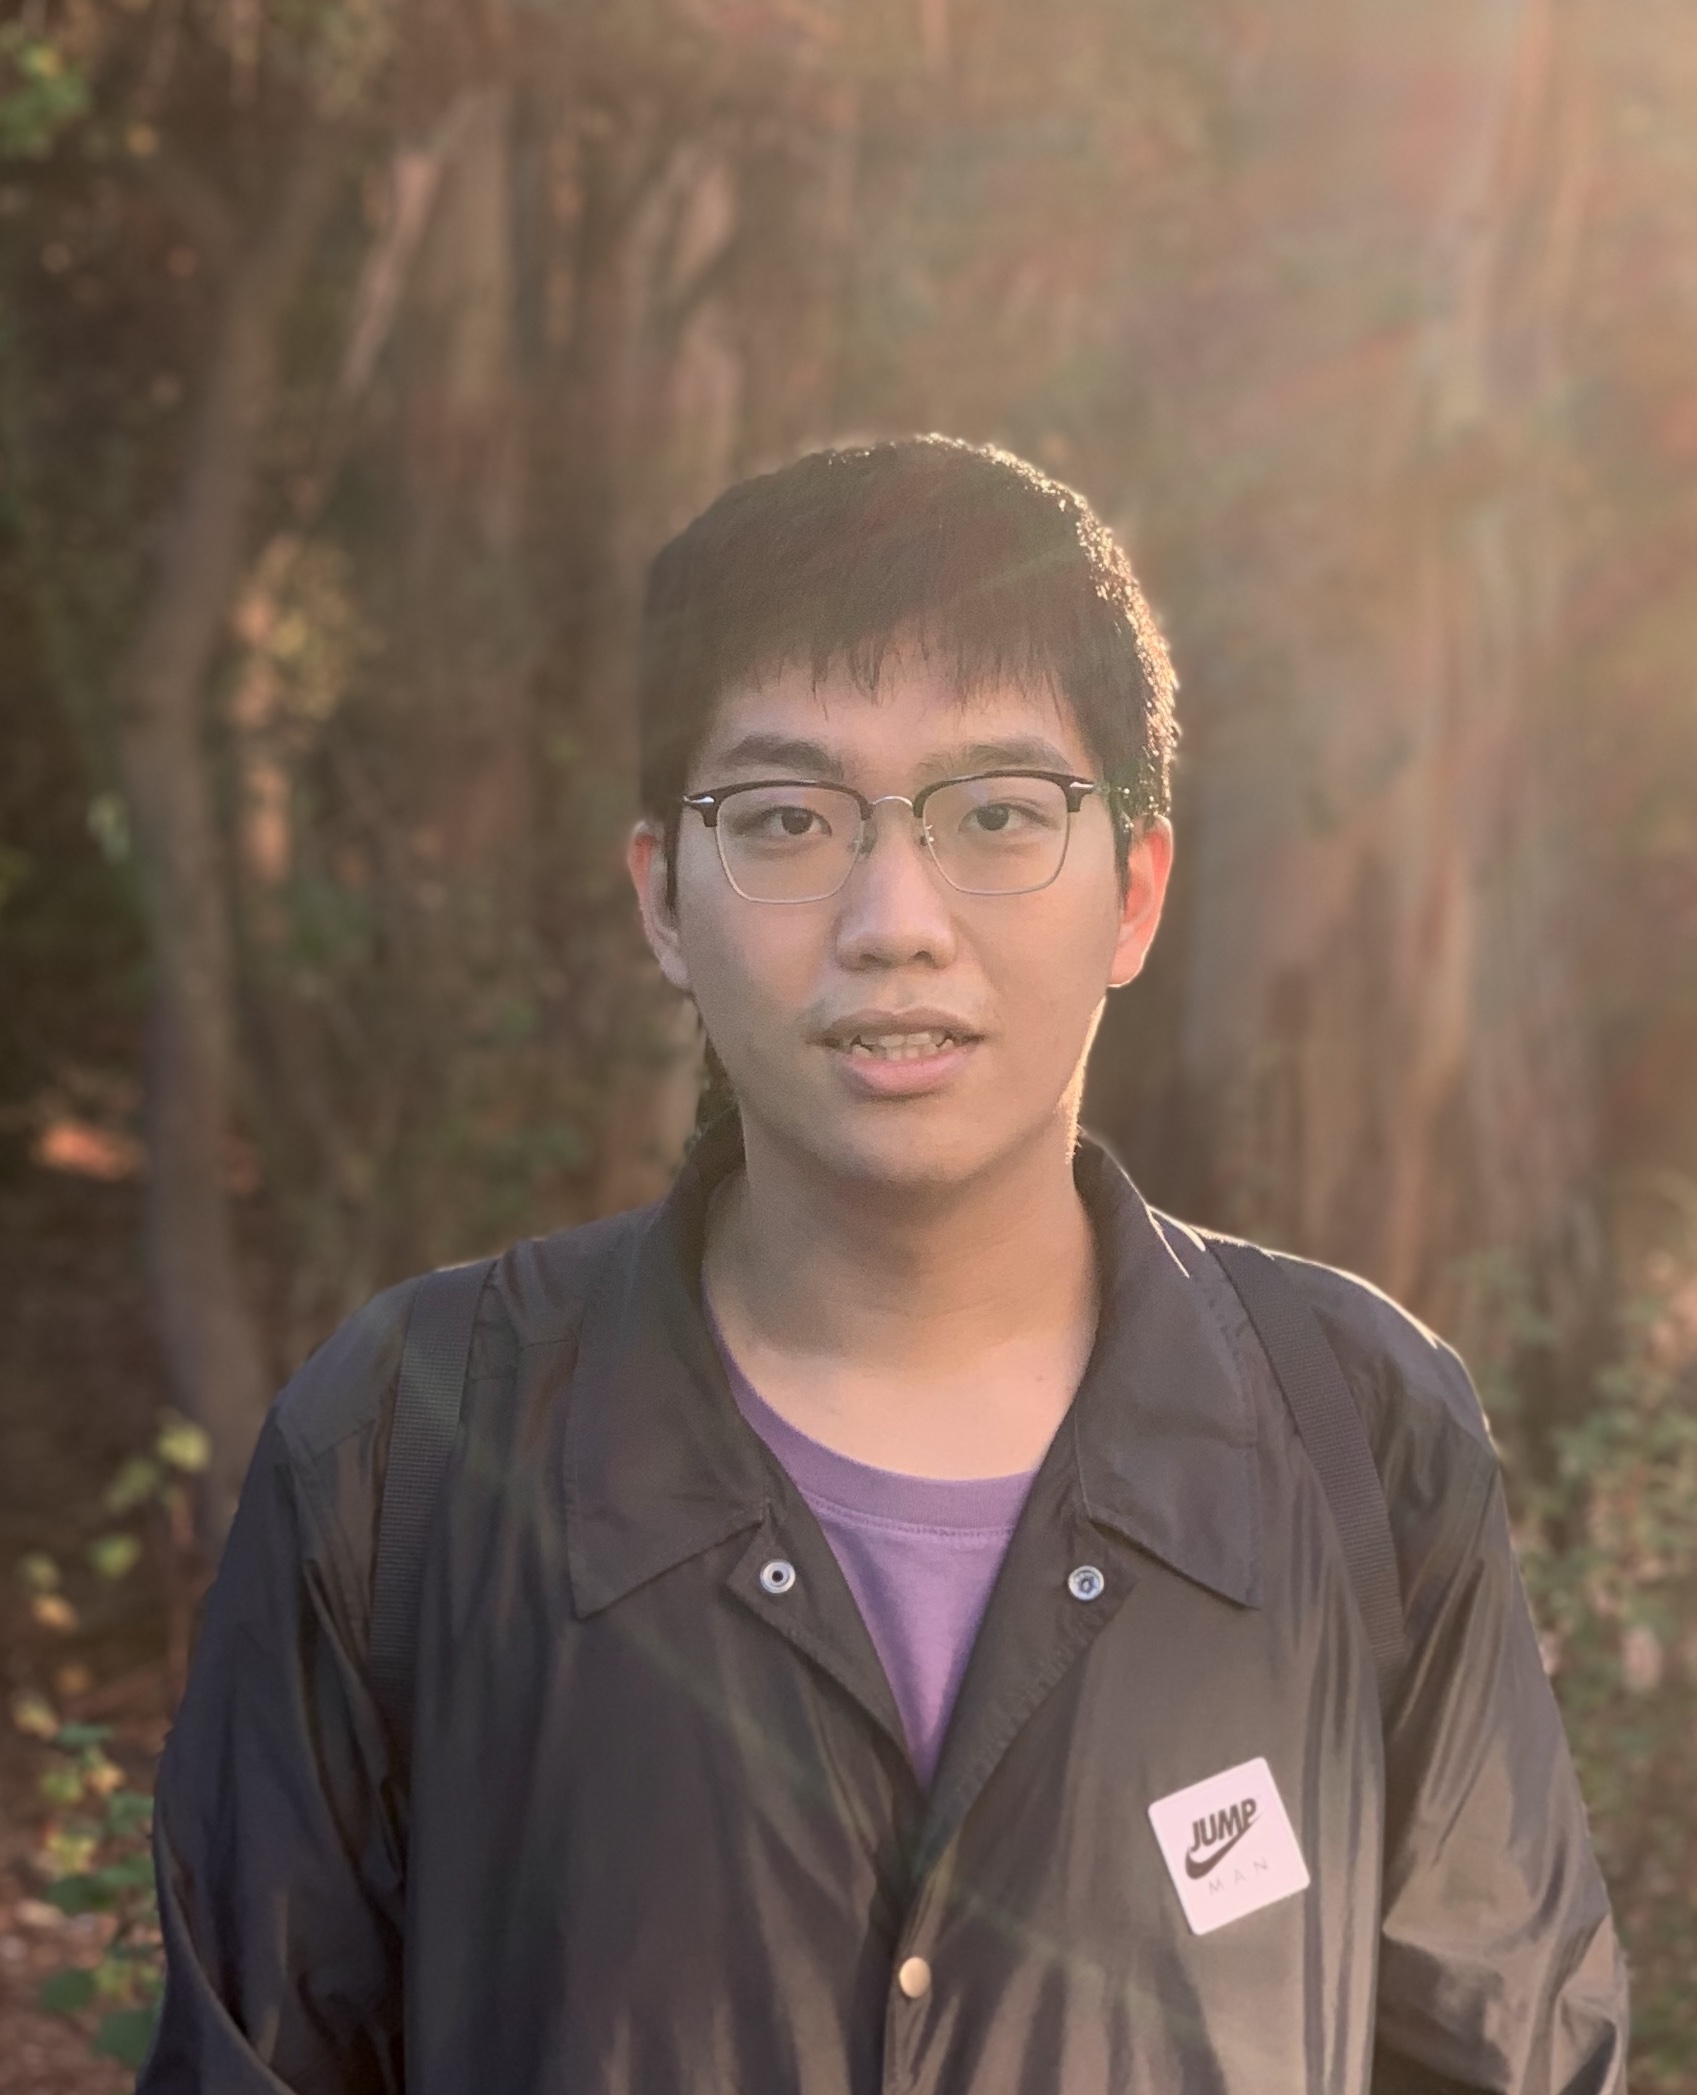
Hong Liu is an AI researcher working on language-model pretraining. He co-founded Voyage AI and previously led its research on embedding models and rerankers for semantic search.[1]
Start with Sophia →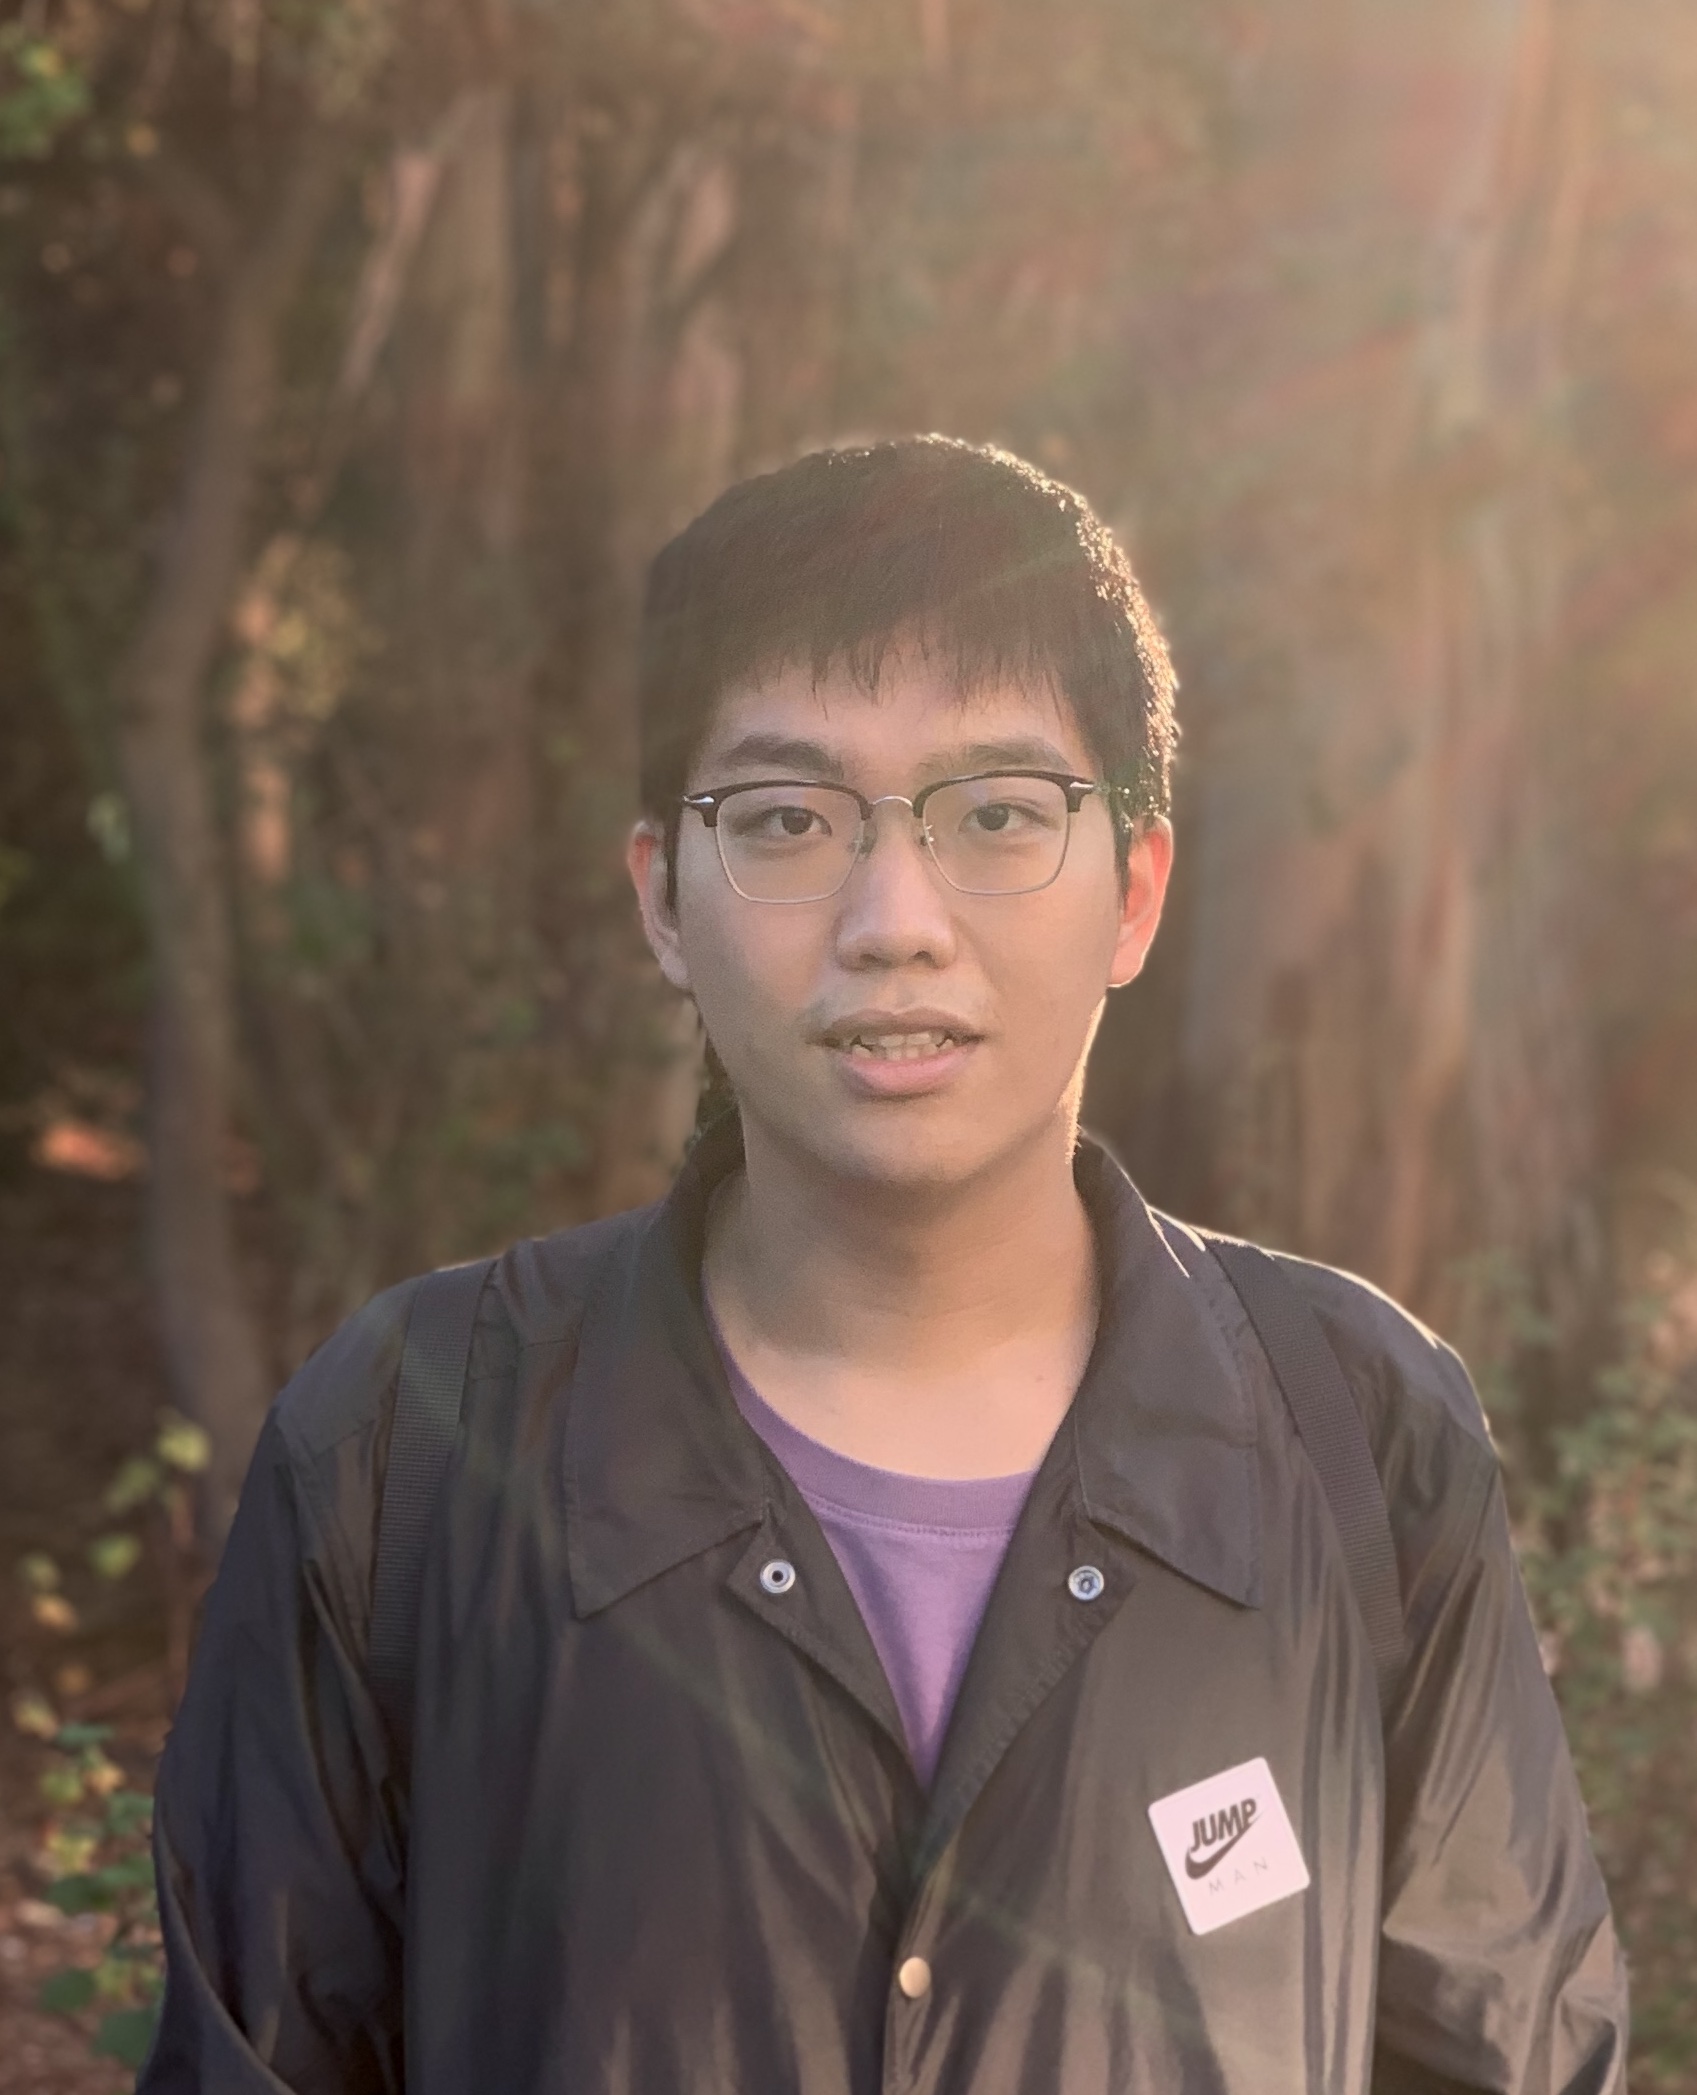
Education
Links
Personal site GitHub · LiuHong99
 X · HongLiu9903
Career
Liu completed a PhD at Stanford, affiliated with its AI Lab and NLP Group. His research spans synthetic data, multimodal learning and reasoning. At Voyage AI, he led research on representations for finding relevant information: embeddings place content into a space where related items can be compared, while rerankers refine a set of retrieved candidates.[1]
Contributions
Adapting an optimizer to curvature
Liu co-authored Sophia, an optimizer for language-model pretraining. It periodically estimates the loss function’s diagonal Hessian, measuring local curvature, to scale updates. Clipping bounds each update, while infrequent curvature estimation limits overhead.[2]
Learning multimodal representations
His co-authored MoCa work adapts a vision-language model for embedding tasks through two stages. Continual pretraining jointly reconstructs noisy image and text inputs with bidirectional context. Contrastive fine-tuning then learns from varied multimodal examples, extending beyond simple image-caption pairs. The aim is to represent content for comparison and retrieval rather than only predict the next token.[3]
Training across documents
Synthetic Bootstrapped Pretraining studies relationships between documents instead of treating each as an isolated sequence. A synthesizer learns shared concepts from related material and generates additional training documents, which are used alongside the original corpus. The paper tests this procedure in compute-matched pretraining experiments, separating its effect from simply spending more training compute.[4]
Tools, writing & talks
Writing, research & talks
Start here
Sophiaarxiv.orgA curvature-aware optimizer that periodically estimates a diagonal Hessian and clips parameter updates.
Begin with the introduction’s training-cost problem and optimizer diagram. Familiarity with gradient descent and Adam helps before reading the Hessian estimate and clipping details.
Co-author[2]- Synthetic Bootstrapped Pretrainingarxiv.org
A pretraining procedure that generates new documents from learned relationships between existing documents.
Co-author[4]