Iryna Gurevych is a professor of natural language processing at TU Darmstadt and director of its UKP Lab. She co-authored Sentence-BERT and BEIR, research that connects language representations with practical search and evaluation.[1][2][3][4][5]
Start with Sentence-BERT →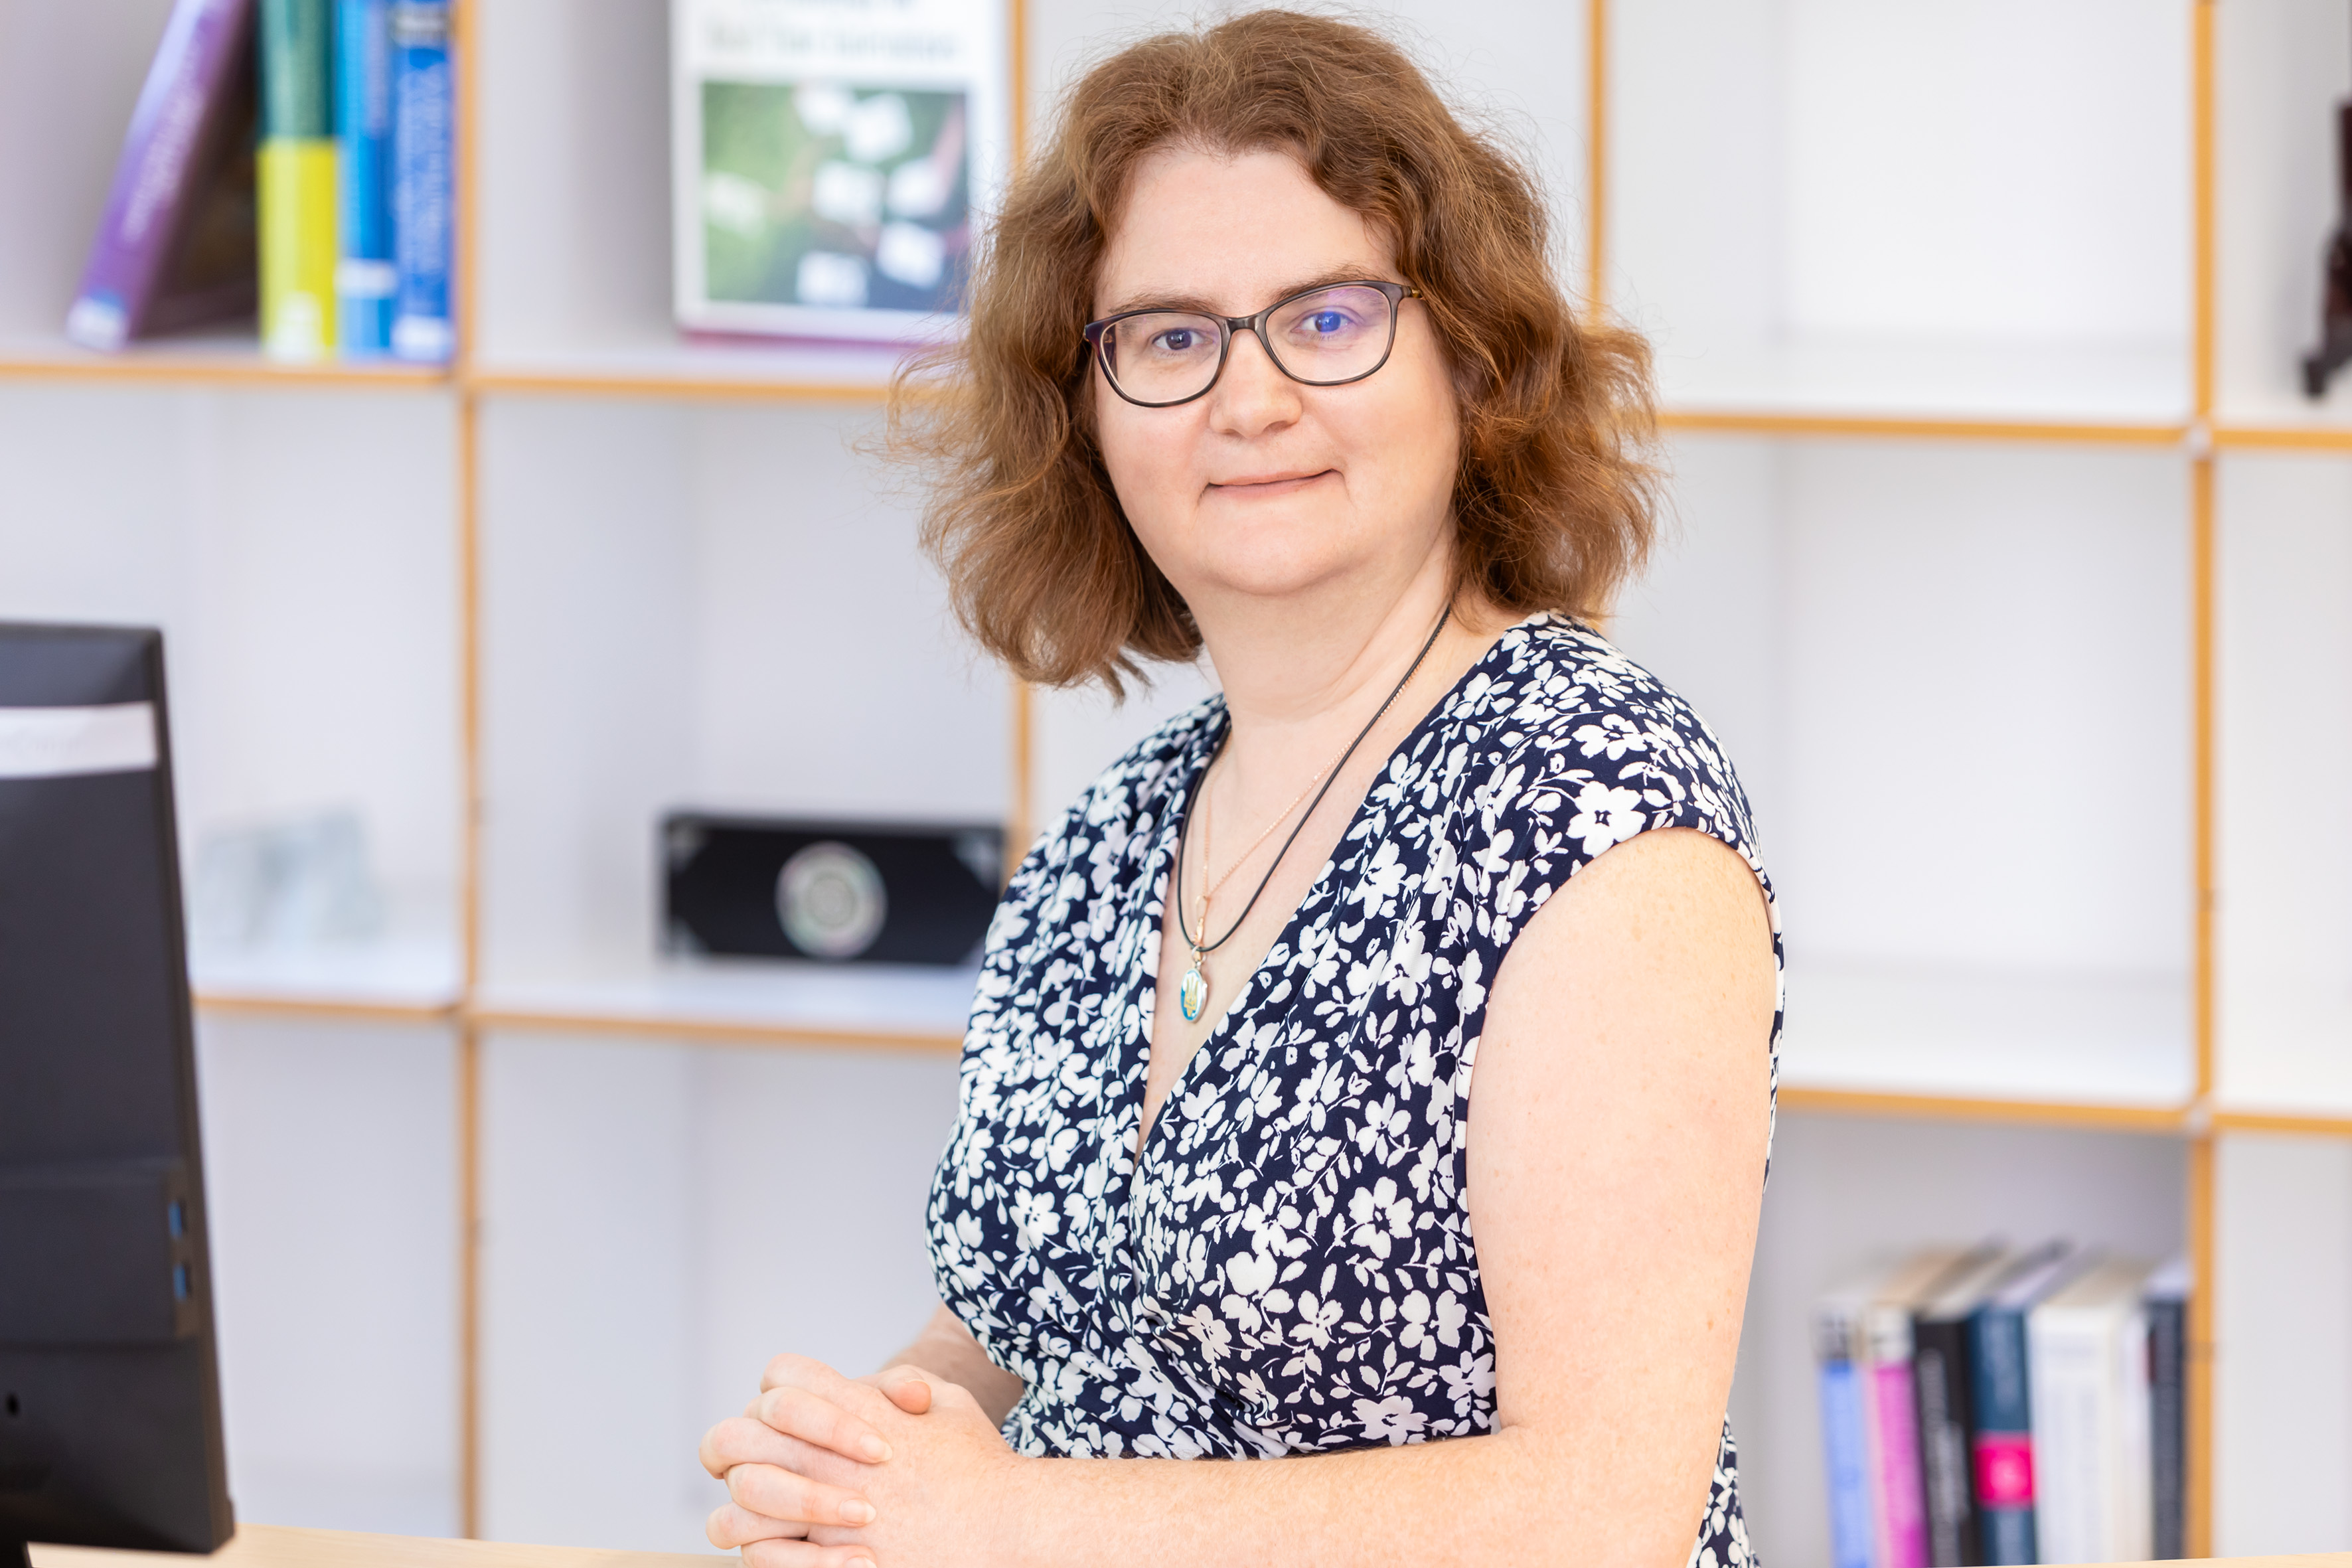
Education
Links
UKP Lab Google Scholar ORCIDFull Professor (W3), Natural Language Processing; Founder and Director, UKP Lab · Technische Universität Darmstadt
Background
Gurevych trained in English and German linguistics at the State Pedagogical University of Vinnytsia and earned a doctorate in computational linguistics at the University of Duisburg-Essen. Her career includes research at the European Media Lab, followed by group leadership and professorships at TU Darmstadt. She has held its full professorship in natural language processing since 2009. Her research extends to scientific documents, AI safety and language technology for mental health.[1][2]
Contributions
Making sentences searchable
Sentence-BERT, written with Nils Reimers, addresses a practical limitation of BERT: comparing sentences together requires repeatedly running a large model for every candidate pair. Their method trains networks to encode sentences separately into vectors, numerical representations that can then be compared cheaply. This makes semantic search and clustering feasible without a full model pass for every pair. The paper evaluates the resulting sentence embeddings on similarity and transfer tasks.[3]
Testing retrieval beyond familiar datasets
Gurevych also co-authored BEIR, a benchmark spanning 18 retrieval datasets. It asks whether a search method still works when moved beyond the narrow setting in which it was developed. Its comparison found the traditional BM25 method remained a strong baseline, while more expensive reranking and late-interaction methods performed well on average. The contribution is a way to test generalization and computational tradeoffs, rather than declare one search architecture universally best.[4]
Finding arguments inside text
With Christian Stab, she developed methods for identifying argument components and their relationships in persuasive essays. Their joint model combines local predictions with constraints on the overall argument structure. The work also supplies annotated essays and guidelines, giving other researchers reusable data for studying claims, reasons and argumentative relationships.[5]
Tools, writing & talks
Writing, research & talks
Start here
Sentence-BERTarxiv.orgA method for encoding sentences separately so their meanings can be compared efficiently in search and clustering.
Begin with the introduction and similarity-search example. Basic familiarity with text embeddings helps; the computational comparison explains why the method became useful.
Co-author[3]A joint model and annotated corpus for identifying argumentative components and relations.
Co-author[5]