Jimmy Ba is a University of Toronto associate professor and co-author of Adam, Layer Normalization and Lookahead. A co-founder of xAI, he announced his departure in February 2026. His research studies how neural networks can learn more efficiently.[3][4][5][6][7][1][8][9]
Start with Adam: A Method for Stochastic Optimization →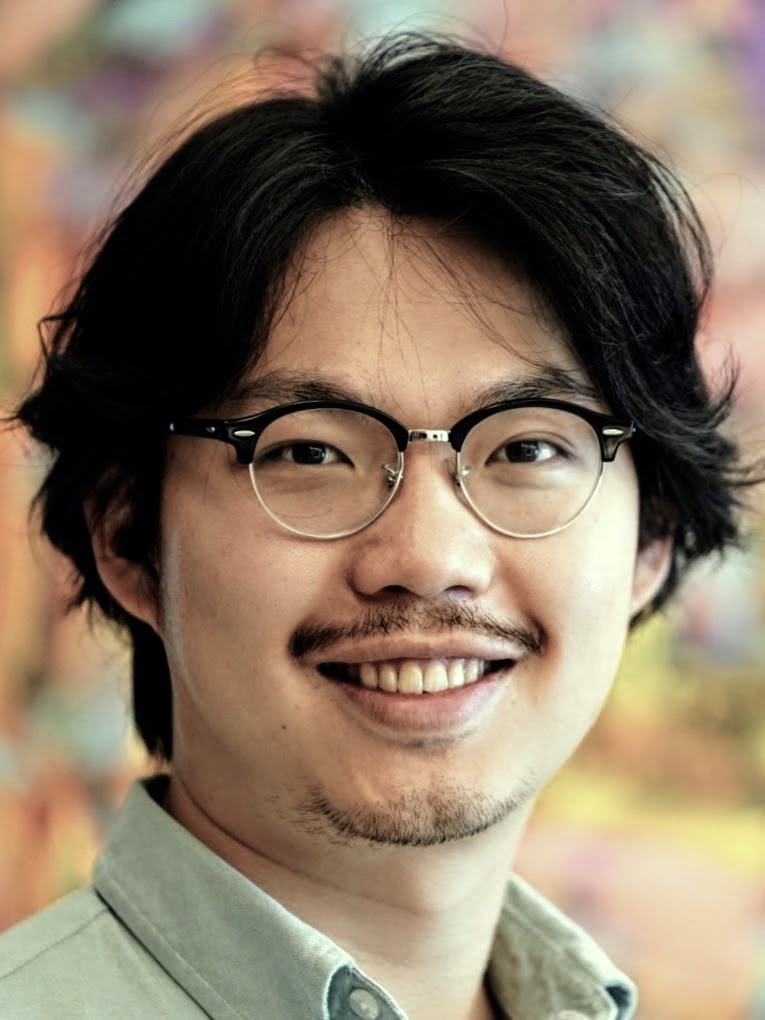
Education
Links
Personal site CV Google ScholarAssociate Professor with tenure · University of Toronto
Background
Ba earned his bachelor’s, master’s and doctoral degrees in electrical and computer engineering at the University of Toronto. His CV records study from 2007 to 2011, 2011 to 2014 and 2014 to 2018 respectively. His doctoral supervisor was Geoffrey Hinton. That training led into research on learning algorithms: the procedures that adjust a neural network’s parameters as it encounters data. His personal research statement frames the longer-term question as building problem-solving machines with greater efficiency and adaptability.[2][1]
Career
Toronto promoted Ba to associate professor with tenure effective July 1, 2024, and its subsequent departmental coverage identifies him as an associate professor and founding member of xAI. In his February 2026 departure statement, Ba thanked the xAI team and said he would remain close as a friend of the team. His academic contributions provide a useful way to follow his work across that organizational change: they concern the basic mechanics of training, rather than one particular chatbot.[3][4][5][6][8][9]
Contributions
Adam adapts the size of training updates
Ba and Diederik Kingma introduced Adam as a computationally efficient optimizer for learning from noisy gradients. A gradient indicates how changing a parameter could reduce a model’s error. Adam maintains running estimates of the gradients and their squared values, then uses those estimates to adapt updates for different parameters. The paper addresses large datasets and models, including cases where gradients are sparse or noisy. Reading its algorithm alongside the experiments makes the contribution concrete: a compact rule for choosing training updates, rather than a new network architecture.[5]
Normalizing within one example
With Jamie Ryan Kiros and Geoffrey Hinton, Ba proposed Layer Normalization. Batch normalization computes statistics across a group of examples; this method computes them across the neurons in a layer for a single example. That changes the dependence on batch size and makes the calculation the same during training and testing. The authors also describe how to apply it separately at each time step in recurrent networks, reporting more stable hidden-state dynamics and shorter training times in their experiments.[6]
Lookahead wraps an existing optimizer
Lookahead, co-authored with Michael Zhang, James Lucas and Hinton, maintains fast and slow sets of weights. An inner optimizer explores with the fast weights, while periodic updates move the slow weights toward the result. This makes it a method that can be combined with SGD or Adam. The paper reports improved stability and reduced update variance, with experiments on image classification and language tasks. Together, these papers show three distinct places to intervene in training: the update rule, the scale of internal activations and the trajectory of the weights.[7][5][6]
Tools, writing & talks
Writing, research & talks
Start here
Start with the algorithm and its running estimates of gradients. Basic calculus and familiarity with gradient descent help explain why each parameter receives an adaptive update.
The compact algorithm is a direct introduction to Ba’s work on efficient learning; some gradient-descent background is useful.
Co-author with Diederik P. Kingma[5]- Layer Normalizationarxiv.org
Explains how computing normalization statistics within each example avoids dependence on other examples in a batch. The recurrent-network experiments show the practical motivation.
Co-author[6] - Lookahead Optimizerarxiv.org
A complementary training method that wraps another optimizer with fast and slow weights. Read after Adam to see the difference between adapting individual steps and smoothing the longer trajectory.
Co-author[7]