Kilian Lieret builds and evaluates AI agents that work on software repositories. A staff AI research scientist at Meta Superintelligence Labs, he previously co-developed SWE-agent at Princeton and helped turn code navigation, editing and testing into actions a language model can perform.[3][4]
Start with mini-swe-agent →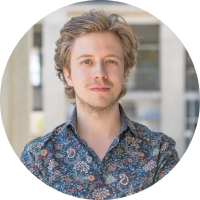
Education
MSc, Theoretical and Mathematical Physics
Oct 2014 – Sep 2018
[3]Links
Website CV GitHub
 X LinkedIn Bluesky Google Scholar ORCID
Staff AI Research Scientist, Meta Superintelligence Labs · Meta
Background
Lieret trained in mathematics and physics in Munich before moving to Princeton. His postdoctoral research studied graph neural networks for particle tracking: reconstructing particle paths from the scattered measurements a detector records. In 2024 he moved into Princeton’s language-model research, developing systems that act on code rather than only predict it.[3][5]
Career
At Princeton, Lieret worked first in research software for high-energy physics and then in the Princeton Language and Intelligence initiative. His current CV lists a move to Meta in February 2026 and a staff research scientist title from September. It identifies software-engineering agents and frontier benchmarks as his focus.[3]
Contributions
Interfaces that let models work on code
SWE-agent gives a language model a structured way to inspect a repository, edit files and run tests. Lieret co-authored the paper, which studies how the interface between an agent and its computer changes the agent’s performance. That distinction matters when evaluating a coding system: a model’s ability is only one part of the result; the commands, feedback and environment also shape what it can finish.[4]
A small agent you can inspect
The mini-swe-agent project strips the agent loop down to a small implementation with shell-based actions. Lieret announced the project’s release on his personal site. Developers can use it to examine how model responses become commands, how command output returns to the model and when execution stops. Its simplicity makes it a useful starting point for understanding the machinery behind a coding agent.[6][2]
Ideas
Lieret’s research also asks how to evaluate work that extends beyond a single issue. ProgramBench tests rebuilding programs from executables and documentation, while CodeClash evaluates agents that improve code through repeated competition. These tasks expose different requirements from patching a known bug: choosing a structure, learning from feedback and continuing toward a broader objective. Their results describe particular evaluation settings, not a general measure of engineering ability.[5]
Tools, writing & talks
Tools
Start here
mini-swe-agentgithub.comA small shell-based coding agent whose implementation makes the action-and-feedback loop easy to inspect. Start with the README before trying it on a disposable repository.
Start with the README and the small agent implementation to see how a model uses shell commands and receives feedback. Python and command-line familiarity help; use a disposable repository for experiments.
- ProgramBenchgithub.com
A benchmark that asks an agent to recreate a program using its executable and documentation, without the original source code.