Lakshya A Agrawal is a computer science PhD student at UC Berkeley and a creator of GEPA. He studies how AI systems improve through experience by changing prompts, agent configurations and model weights.[1][2]
Start with GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning →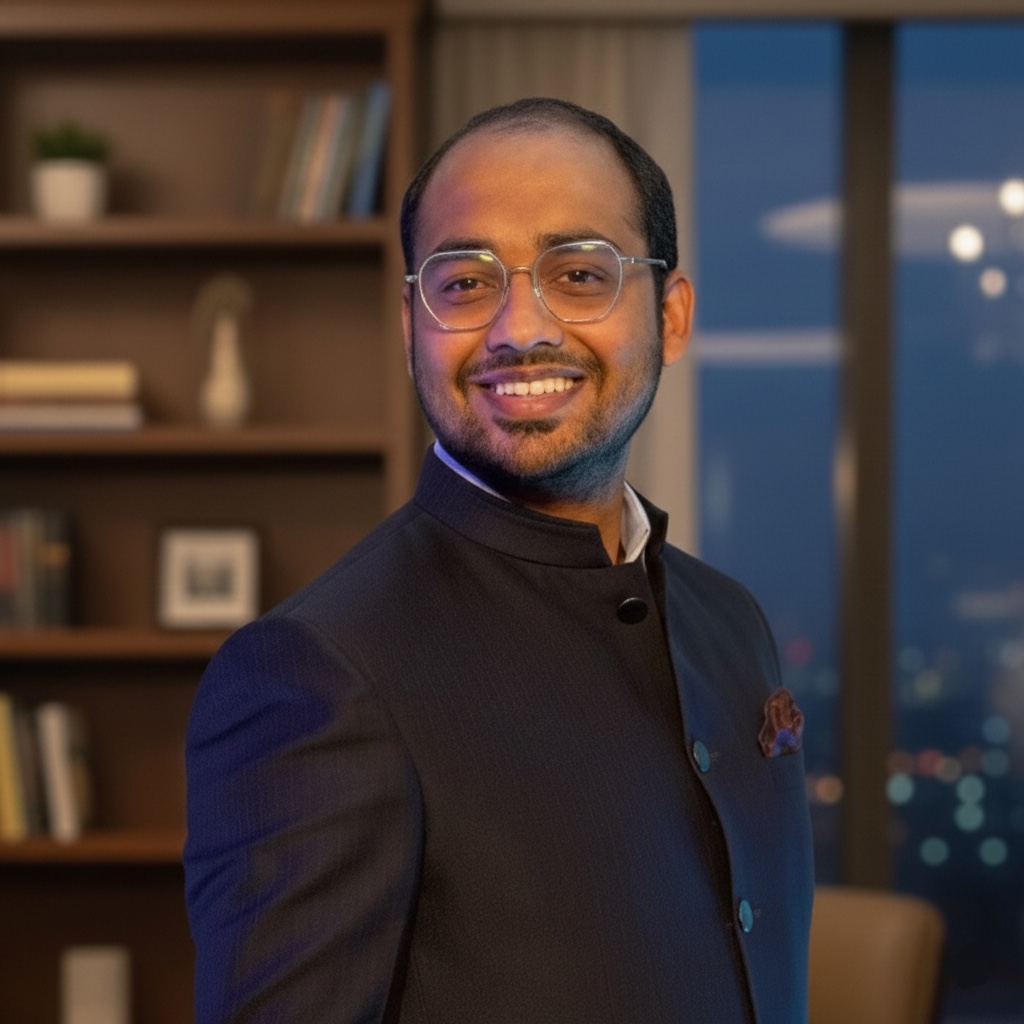
Education
PhD in Computer Science (in progress)
Aug 2024 – end date unverified
[1]
Links
Website GitHub
 X LinkedIn
Open Research Resident · Laude Institute
Background
Agrawal earned a B.Tech in Computer Science and Applied Mathematics at IIIT-Delhi in 2022 and began his Berkeley doctorate in 2024. His CV records work at Microsoft Research from January 2022 to August 2024, first as an intern and later an AI4Code research fellow. Earlier, he was a Summer@EPFL research fellow, developing a runtime and debugging support for a dataflow programming language.[4]
Career
At Berkeley, Agrawal works with Matei Zaharia and Dan Klein and is affiliated with Sky Lab, BAIR and Berkeley NLP. His personal site identifies him as a Laude Open Research Resident and Amazon AI PhD Fellow. It connects his earlier work on programming-language tools with a continuing interest in evaluating and improving complete AI systems.[1]
Contributions
Learn from traces rather than a score alone
GEPA reflects on an AI system’s execution traces, including reasoning, tool calls and their outputs. It uses natural-language feedback to diagnose failures, propose prompt revisions and test them, combining lessons from candidates with different strengths. Agrawal is the first-listed author. Across six reported tasks, the method outperformed GRPO on average while requiring fewer rollouts. These results compare particular training and optimization settings, rather than establishing that prompt search always replaces reinforcement learning.[2]
A common interface for text optimization
Agrawal also coauthored optimize_anything. It treats a prompt, program or other text artifact as a candidate evaluated by a scoring function. The optimizer uses feedback to propose and test revisions, and can transfer lessons across related tasks. The paper’s varied experiments ask whether this interface can support tasks that otherwise need separate optimization systems. Actionable feedback about a failure helps the search more than a bare score in the reported ablations.[3]
Tools, writing & talks
Writing, research & talks
Start here
A prompt optimizer that turns execution traces and textual feedback into tested revisions.
Read the reflection and candidate-selection examples first if you already use language-model prompts. They show what information a useful evaluation should return beyond a score, before you try to optimize your own system.
First-listed author[2]GEPA has a model read a full agent trace and rewrite its own prompt instead of collapsing a rollout into one RL score, doubling GRPO's gains after just 3 examples. Its 'Optimize Anything' successor pushed Gemini Flash's ARC-AGI score from 32.5% to 89.5%.
Catalog workOriginal source- optimize_anythingarxiv.org
A shared optimization interface for text artifacts, scored experiments and feedback.
Coauthor[3]