Llion Jones is co-founder and CTO of Sakana AI and a co-author of Attention Is All You Need, the paper that introduced the Transformer. His later research includes Continuous Thought Machines and hardware-efficient sparse language models.[1][3][4][5]
Start with Continuous Thought Machines →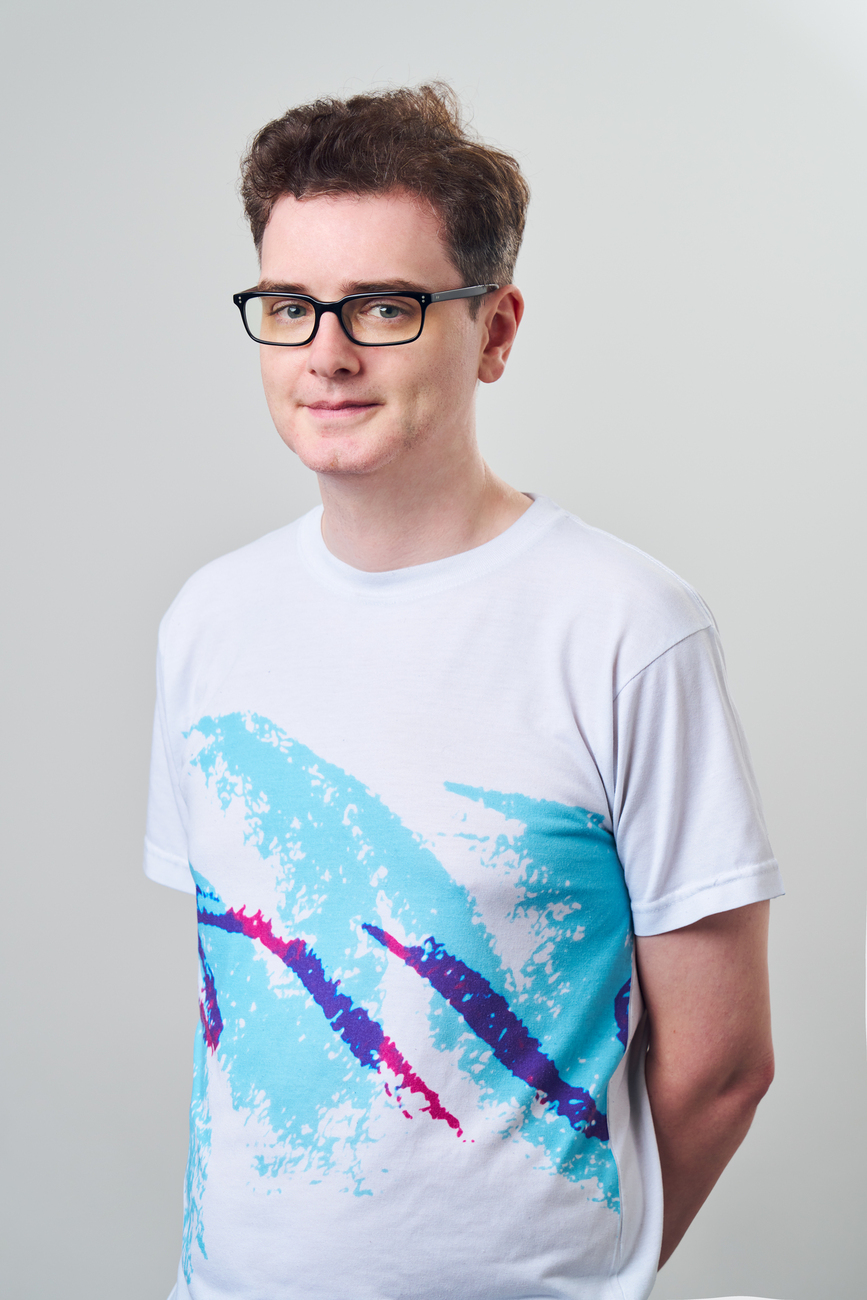
Background
Jones studied computer science and artificial intelligence at the University of Birmingham, graduating in 2006, then completed a master’s in advanced computer science in 2009. His professional profile records software-engineering roles at Delcam, YouTube and Google. At Google, he worked on machine intelligence and natural-language understanding.[2][3][7]
Career
Jones co-founded Sakana AI and serves as its CTO. The company’s biography records his departure from Google in 2023. His own professional profile dates the Sakana co-founder role from August of that year. Sakana provides the organizational setting for his subsequent work on neural architectures and efficient computation, including papers on Continuous Thought Machines and sparse Transformer execution.[1][2][4][5]
Contributions
Attention as the central operation
Jones is one of the eight authors of Attention Is All You Need. The 2017 paper introduced the Transformer, which uses attention to relate elements of a sequence without the recurrent or convolutional structure used by earlier sequence models. That change made more of the training computation parallelizable. The paper evaluated the architecture on English-to-German and English-to-French translation and reported stronger results with less training time than the compared systems. Those translation experiments are the paper’s direct evidence; later applications grew from the architecture.[3]
Giving a network internal time
Continuous Thought Machines use patterns of synchronized neuron activity over time as a representation. Individual neurons process a history of incoming signals, while the network takes internal steps that need not correspond one-for-one to input words or frames. Jones co-authored the report with Luke Darlow, Ciaran Regan, Sebastian Risi and Jeffrey Seely. The interactive maze demo lets a reader watch attention shift as the model produces a route. The report describes a biologically inspired architecture, rather than a literal simulation of a brain.[4]
Turning sparsity into actual speed
Jones co-authored a study of sparse language-model computation. Many activations can be close to zero, but skipping them does not automatically make a GPU faster: irregular work can conflict with hardware designed for dense matrix multiplication. The team introduced the TwELL packing format and custom CUDA kernels to fit sparse computation to tiled GPU execution. Their experiments report speedups on H100 hardware. The result ties a model property to a concrete implementation, where theoretical savings have to survive memory and scheduling costs.[5]
Ideas
In his 2025 TEDAI talk, Jones argues that competition among large AI companies can restrict the exploratory research that produced earlier breakthroughs. The talk is an accessible account of his position on research incentives, complementary to the technical papers. It invites a distinction between improving an established architecture and giving unfamiliar ideas enough time to become useful.[6]
Tools, writing & talks
Writing, research & talks
Start here
Continuous Thought Machinespub.sakana.aiTry the maze demonstration for a visible introduction to a network that takes internal steps and represents information through synchronized activity.
The maze demonstration gives a visible example of his newer architecture research before introducing the mathematics.
Co-author[4]- Attention Is All You Needarxiv.org
The original Transformer paper. Its architecture diagrams and translation experiments are the foundation for understanding Jones’s best-known contribution.
Co-author[3] - Sparser, Faster, Lighter Transformer Language Modelspub.sakana.ai
A systems-oriented study of sparse data formats and GPU kernels, with code for readers interested in how model efficiency becomes hardware efficiency.
Co-author[5] A nontechnical talk about the incentives that shape AI research and the space needed for exploratory work.
Speaker[6]