Luo Fuli leads Xiaomi’s MiMo foundation-model work. Her research includes language understanding and reinforcement learning for large models; she is a coauthor of the MiMo-V2.6 technical report.[1][7]
Start with MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement →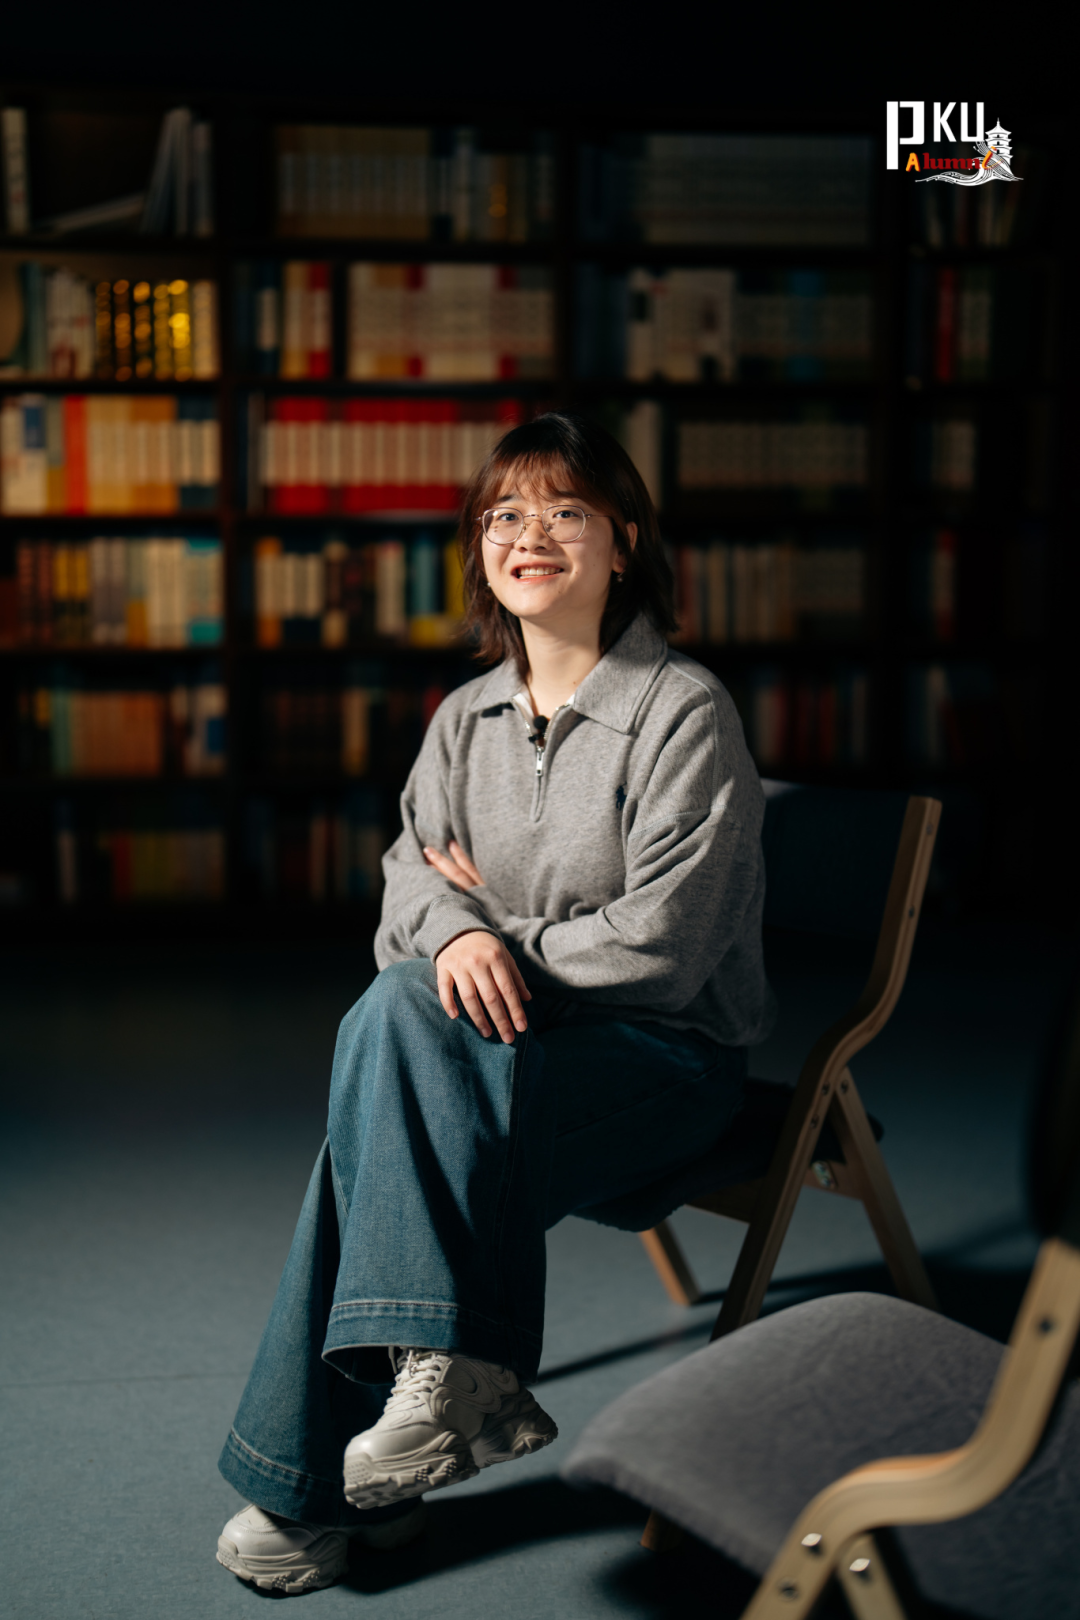
 GitHub
Career
Luo studied computer science at Beijing Normal University and computational linguistics at Peking University. Her owned research website records a WeChat AI research internship from September 2017 to March 2019 and a Google machine-learning internship beginning in April 2019. Xiaomi now identifies her as the head of MiMo’s large-model work.[2][3][1]
Contributions
The MiMo-V2.6 report describes training models across code, visual and other interactive environments. The team scales the number of sampled attempts, the variety of tasks and the computation used to grade long trajectories. It also freezes the model’s expert-routing component during reinforcement learning and adds defenses against exploiting the reward system. Luo is one of the report’s coauthors; the paper presents a team effort rather than an individually authored model.[7]
Ideas
In a Peking University profile, Luo argues that labels such as genius obscure the work behind research. She points to the gap between language-model performance and a young child’s understanding of other people, connecting her interest in intelligence to observation, feedback and interaction with the physical world. These are her stated research interests, not a claim that MiMo has solved those problems.[6]
Tools, writing & talks
Writing, research & talks
Start here
A team report on scaling reinforcement learning across agent tasks and grading systems.
Start with the training setup and the three dimensions of reinforcement-learning scale. Familiarity with language-model training helps; compare reward-design safeguards with the reported evaluations.
Co-author[7]