Noam Shazeer is a computer scientist at OpenAI who co-authored the Transformer and sparsely gated mixture-of-experts papers. He previously worked at Google, co-led Gemini and co-founded Character.AI.[1][2][3]
Start with Jeff Dean & Noam Shazeer — 25 years at Google: from PageRank to AGI →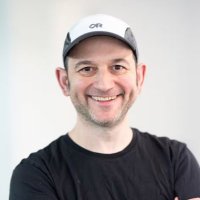
 X · noamshazeer
Background
His professional profile records Duke University attendance from 1994 to 1998. His official biography also identifies contributions to Mesh-TensorFlow, T5 and LaMDA, connecting model architecture with the systems needed to train and serve large networks. The selected papers offer the most direct route to examining his documented research contribution, while the interview provides context on the engineering environment around it.[1][4][5]
Career
Shazeer’s personal biography dates his start at Google to 2000 and describes work on spelling correction and advertising systems before later language-model research. He co-founded Character.AI and subsequently co-led Gemini at Google. His current website and professional profile identify OpenAI as his present organization. The Dwarkesh interview with Jeff Dean records his own account of joining Google and learning from Dean during the company’s early years.[1][4][5]
Contributions
The Transformer architecture
Shazeer co-authored Attention Is All You Need, the 2017 paper introducing the Transformer. The model uses attention mechanisms to combine information across a sequence without the recurrent or convolutional components of the dominant systems compared in the paper. That design made the tested translation models more parallelizable and reduced training time while improving results on the paper’s benchmarks. The architecture became a foundation for subsequent language models, giving this work a role well beyond its original translation experiments.[2]
More capacity without activating every parameter
He is the first-listed author of the sparsely gated mixture-of-experts paper. Its network contains many specialist feed-forward subnetworks, while a learned gate selects only a small combination for each example. This increases total model capacity without requiring every expert to run on every input. The paper applies the approach to language modeling and translation and studies the algorithmic and systems difficulties of making sparse computation efficient.[3]
Tools, writing & talks
Writing, research & talks
Start here
A long-form conversation about computing infrastructure, model architecture and Google’s research history.
Start with the chaptered interview for the engineering context and a spoken explanation of the research trajectory. Read the Transformer paper afterward if you are comfortable with neural networks, matrix operations and attention.
Interview guest[5]Original source- Attention Is All You Needarxiv.org
The paper introducing the attention-based Transformer architecture, evaluated on translation tasks.
Co-author[2] A model architecture routing each example to a small subset of many expert networks.
First-listed co-author[3]