Percy Liang is a Stanford computer-science professor, director of its Center for Research on Foundation Models, and a Together AI founder. He develops tools and methods for open research and for evaluating the capabilities and transparency of language models.[1][2][3]
Start with Improving Transparency in AI Language Models: A Holistic Evaluation →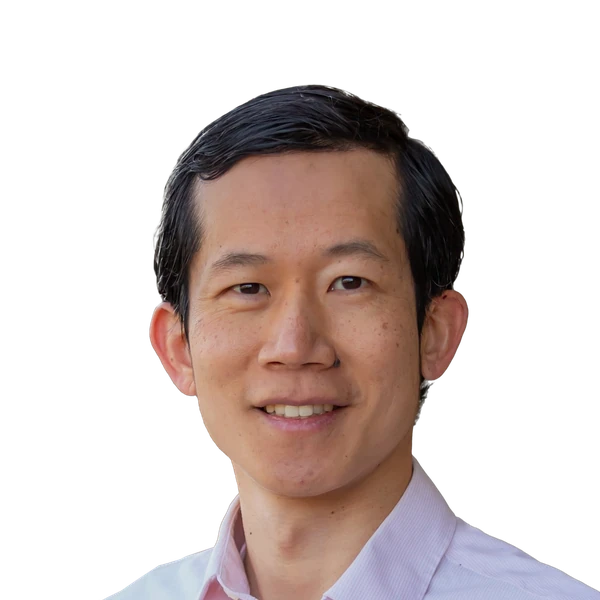
Education
Links
Personal website Stanford profile X LinkedIn
Professor of Computer Science · Stanford University
Director, Center for Research on Foundation Models · Stanford University
Founder · Together AI
Background
Liang earned a bachelor’s degree from MIT in 2004, an M.Eng. there in 2005, and a doctorate from Berkeley in 2011. His personal site records a Google postdoctoral position in 2012. He now directs Stanford’s Center for Research on Foundation Models, and Together AI lists him as a founder. He is a professor of computer science at Stanford.[1][2][3]
Contributions
Evaluate more than the best score
Liang is first author of Holistic Evaluation of Language Models, or HELM. The project standardizes evaluation conditions so that different models can be compared on overlapping tasks. It measures multiple properties, including accuracy, calibration, robustness, fairness, bias, toxicity, and efficiency. Calibration asks whether a model’s confidence matches its likelihood of being right. The approach makes trade-offs visible instead of letting one impressive score stand in for a model’s behavior. The authors also release prompts and outputs so others can inspect the results.[4]
Transparency is a separate question
Liang co-authored the 2025 Foundation Model Transparency Index. This line of work asks what developers disclose about their models and development practices. It is different from asking which model answers the most questions correctly: strong performance does not itself reveal training resources, policies, or downstream deployment practices. The 2025 report found a decline in average transparency relative to the 2024 edition. Treat the index as an assessment under its indicators and collection method, not as a complete safety rating or an independent audit of every developer claim.[6]
Study the interaction, not only the generated text
With Mina Lee and Qian Yang, Liang co-authored CoAuthor, a dataset of people writing with GPT-3. It records interactions from creative and argumentative writing sessions and provides an interface for replaying them. That lets researchers investigate how suggestions enter a writing process, rather than inspect only a finished document. The study asks about language, ideation, and collaboration, while recognizing that a useful collaborator can be defined in different ways. Its findings concern that dataset and model setting, rather than every form of AI-assisted writing.[8]
Ideas
Liang’s personal site describes Marin as a project he created to build models openly. He describes open development as sharing the experimental process, including unsuccessful experiments, so others can understand and contribute to model development. He connects that aim with teaching language models from scratch and with his earlier CodaLab Worksheets system, which preserved the path from raw data to experimental results. To enter his evaluation work without starting with a long technical paper, read Stanford’s HELM policy brief, then consult the research paper for the methodology and its limits.[2][5]
Tools, writing & talks
Writing, research & talks
Start here
An accessible introduction to why models should be compared under shared conditions and across more than accuracy. Follow it with the HELM paper for methods.
A multi-metric evaluation framework with standardized comparisons and public prompts and model outputs.
First author[4]Assesses disclosures by foundation-model developers and compares transparency across annual editions.
Co-author[6]