Co-founder and CEO of Trajectory, building systems for AI agents to learn from their deployed behavior.[4]
Start with Scaling up Continual Learning →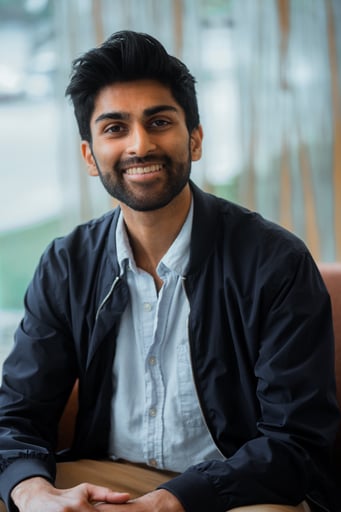
 X · rronak_
Career
Malde helped ship Windsurf and train SWE-1 at Codeium, then worked on Antigravity and Gemini 3 at Google DeepMind before leaving to start Trajectory. His work moves from building coding agents to adapting them after deployment, when real corrections and failed workflows reveal tasks that curated benchmarks can miss.[6]
Ideas
In his continual-learning talk, Malde describes on-policy self-distillation: the student generates a trajectory, while the same model receives a useful hint and supplies token-level target probabilities. Long tool sequences introduce another problem: a teacher can diverge from the student or rely on information unavailable in deployment. He discusses weighting steps by their disagreement and moderating privileged hints, rather than treating one final reward as sufficient instruction for every step.[1]
Tools, writing & talks
Writing, research & talks
Start here
Scaling up Continual Learningai.engineerA talk on adapting agents from production trajectories, including self-distillation, step weighting and the risk of learning shortcuts from privileged hints.
Start with the talk for a conceptual explanation of learning from agent traces. Familiarity with language-model training and tool calls helps; the teacher/student comparison explains why a whole-task score loses detail.
Speaker[1]Push on-policy self-distillation to trajectories with a hundred tool calls and the model collapses into hedging, favouring wait, but and maybe. The cause is the student drifting far enough that the teacher course-corrects at every opportunity.
Catalog workOriginal source
Tools
A joint CS238 project with Arjun Karanam. It compares curriculum learning and negative rewards for the kickoff phase; the authors report useful negative-reward results but no improvement from their curriculum approach.
Co-author[3]
 github.com