Sujee Maniyam is an AI developer advocate at Nebius. He builds open-source examples, teaches workshops and helps developers evaluate and use open models in working applications.[1][2]
Start with LLM Quick Bench →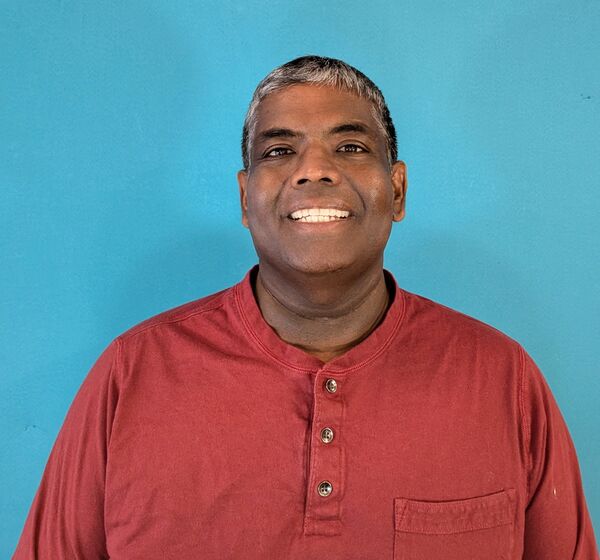
 X · sujee_dev
Career
Maniyam’s background spans machine learning, distributed systems, data engineering and cloud infrastructure. His portfolio records developer advocacy across Nebius, AI Alliance, MongoDB and Intel, alongside books including HBase Design Patterns and Hadoop Illuminated. At Nebius, his work centers on Token Factory, open models, coding agents and inference. He also organizes developer programs where people test ideas and bring questions back to engineering teams.[1][3][4]
Contributions
Measure an endpoint before choosing a model
His LLM Quick Bench runs in a browser and measures response speed, token throughput, latency, accuracy, usage and estimated cost. It exports results as CSV or JSON. The tool is intended as a quick comparison rather than a replacement for comprehensive benchmarking, letting developers examine an endpoint without setting up a Python environment or a separate virtual machine.[5]
Make model behavior visible
LLM Snake Arena turns model evaluation into a live game. Models choose moves through OpenAI-compatible APIs while observers compare latency, reliability and decision-making. Practical LLM Evals collects more conventional performance and experiential evaluations. Together, these projects make different tradeoffs visible instead of treating a single leaderboard score as an application-level verdict.[6][7]
Tools, writing & talks
Tools
Start here
LLM Quick Bench github.com
A browser-based comparison of inference endpoint speed, accuracy, token usage and cost.
Start with Quick Bench to compare endpoints on the dimensions your application needs. You need an inference endpoint and its credentials; interpret the results as a quick measurement of that setup.
Creator[5]- LLM Snake Arenagithub.com
A visual arena for comparing model decisions and latency while playing Snake.
Creator[7] - Practical LLM Evalsgithub.com
Performance tests and experiential evaluations for open models.
Creator[6]
Writing, research & talks
Nebius engineers cover production serving of open LLMs: NVFP4, engine choice, cache-aware routing, speculative decoding with draft models trained on your traffic, KV cache offload, disaggregated prefill/decode, and quantization.
Catalog workOriginal source