Will Brown leads Applied Research at Prime Intellect, building infrastructure for training and evaluating language-model agents, including Verifiers and the Environments Hub.[1]
Start with Verifiers v1 →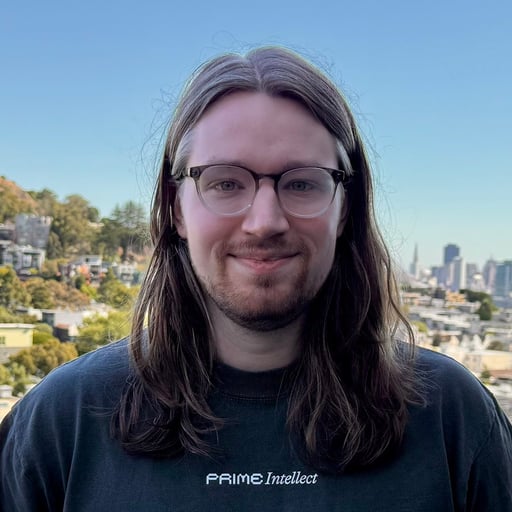
 X
Background
Brown completed a PhD in algorithmic game theory at Columbia, advised by Christos Papadimitriou and Tim Roughgarden. He previously studied computer science, data science, and philosophy at the University of Pennsylvania. His 2024 PhD retrospective describes starting graduate school in 2019 with an interest in systems where learning algorithms interact. The central question was how to design those systems so that adaptive, self-interested behavior leads to desirable outcomes.[1][2]
Career
Before Prime Intellect, Brown worked in Morgan Stanley’s Machine Learning Research group on language-model projects. His public biography also records research and engineering roles at AWS, Two Sigma, MongoDB, and AmFam. At Prime Intellect he works on agentic reinforcement learning: training agents from the outcomes of tasks they attempt, with infrastructure that makes those tasks repeatable and their performance measurable.[1]
Contributions
The Verifiers v1 announcement, co-authored by Brown, separates an environment into a taskset, harness, and runtime. The taskset defines data, tools, and scoring. The harness is the program attempting the task, which could be a simple model loop or a full coding agent. The runtime provides its execution environment. Keeping these pieces separate lets researchers compare different agents on the same task, move execution into a sandbox, and reuse recorded interaction traces for training.[3]
Ideas
Brown’s PhD retrospective explains why a mathematical guarantee that learners reach an equilibrium does not necessarily mean they reach a useful one. Several stable outcomes can exist, with very different consequences for participants. His research asks how a system designer can steer learning toward better outcomes while accounting for how participants adapt. This provides context for his later interest in agent training environments, where choosing tasks and reward signals is part of defining what improvement means.[2]
Tools, writing & talks
Writing, research & talks
Start here
Verifiers v1primeintellect.aiExplains a modular architecture for agent tasks, execution harnesses, runtimes, and training-ready traces.
Read the taskset/harness/runtime diagram first. It explains how a task becomes an evaluation and training environment; implementing it requires Python and familiarity with an agent loop.
Co-author with Mika Senghaas, Florian Brand, and the Prime Intellect team.[3]Vals AI's The Bench interviews Prime Intellect's Will Brown on owning versus renting model capability, why skills cannot capture tacit institutional knowledge, token costs approaching salary costs, compute scarcity, benchmark saturation, and sandboxes for agent RL. Transcript covers the first 30 min
Catalog workOriginal sourcePrime Intellect's Will Brown sketches the roadmap and open questions for agentic RL: what it takes to train an open model that browses, codes and handles long-horizon tasks like OpenAI's o3.
Catalog workOriginal sourceWill Brown of Prime Intellect discusses multi-turn RL for multi-hour agents and reacts to Claude 4's focus on longer-running coding, with hosts from Latent Space.
Catalog workOriginal source- Five years of feedback loopswillcb.com
A first-person overview of PhD research on learning dynamics, equilibrium outcomes, and algorithmic game theory.
Author.[2]