Zhang Peng is cofounder, CEO and general manager of Z.AI, the company previously known as Knowledge Atlas and Zhipu AI. He combines company leadership with research contributions to bilingual language models and cross-language knowledge graphs.[1][2][3]
Start with GLM-130B: An Open Bilingual Pre-Trained Model →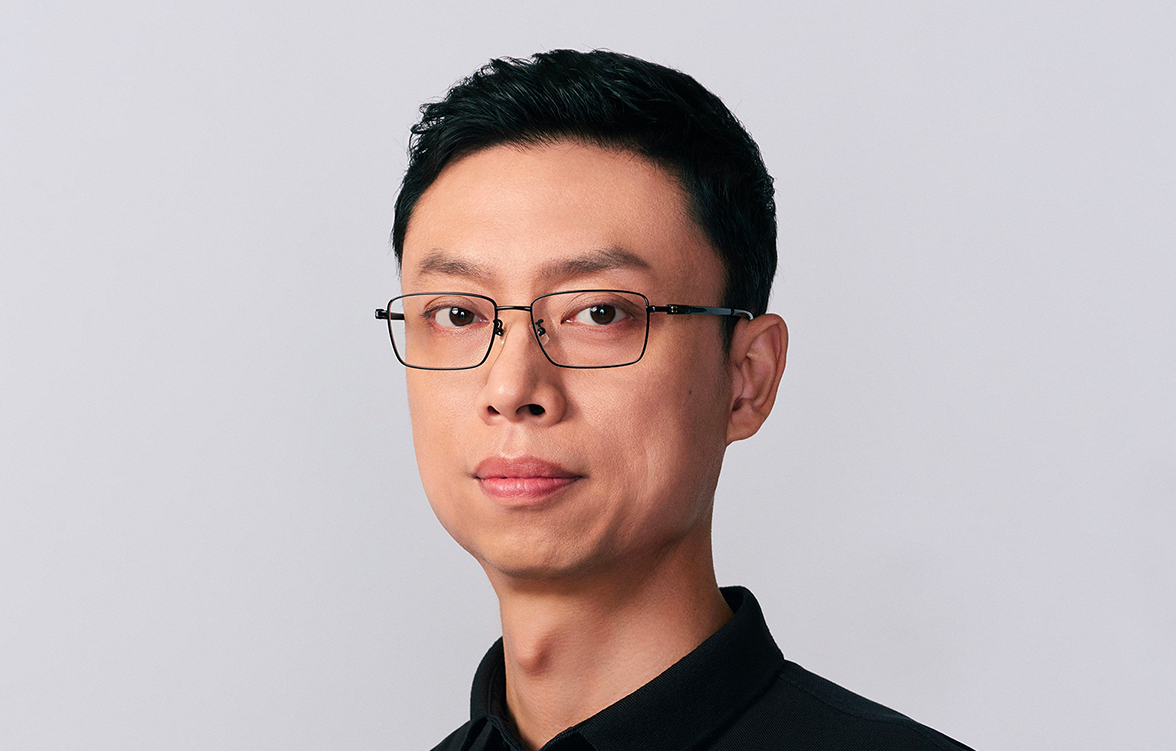
Education
Links
Company annual reportExecutive Director · Z.ai
Cofounder, Chief Executive Officer and General Manager · Z.ai
Career
Zhang worked at Tsinghua from August 2005 to December 2020 and joined the company in June 2019. He became an executive director in March 2025. His Tsinghua degrees span computer science and technology at bachelor’s and master’s level, followed by a June 2025 doctorate in electronics and information. His current responsibilities include R&D, business development and daily operations.[1]
Contributions
Publish how a bilingual model was trained
Zhang is a coauthor of GLM-130B, a collaboration between Tsinghua and Zhipu. The paper describes a large Chinese-English model and the engineering needed to train it, including stability problems, numerical choices and inference quantization. The release shares model weights, code, training logs and lessons from the process, making the training account useful beyond a final benchmark score.[4]
Link knowledge across Chinese and English sources
He coauthored the original XLore demonstration with Juanzi Li, Zhigang Wang and other collaborators. The system combines multiple encyclopedia sources, predicts semantic relations and links equivalent entities across languages. It addresses the imbalance that arises when a multilingual knowledge base depends mainly on English Wikipedia and its existing cross-language links.[5]
Extend a model family toward tool use
The ChatGLM report lists Zhang among Team GLM’s contributors. It describes the progression toward GLM-4 and alignment for following instructions and choosing tools such as a browser, Python interpreter and image generator. The report connects pretraining with later adaptation for practical tasks, and distinguishes publicly released models from API services.[6]
Tools, writing & talks
Writing, research & talks
Start here
A research and engineering account of an open Chinese-English language model.
Begin with the training challenges and design choices in the introduction. The full paper assumes transformer familiarity; its discussion of failed runs and stability decisions explains what a model release’s headline score leaves out.
Coauthor[4]Cross-language entity linking and semantic relations across multiple encyclopedias.
Coauthor[5]The model family’s development, alignment methods and tool-use capabilities.
Team GLM contributor[6]