Restore LLM Inference Capacity in Seconds with Shadow Engine Recovery in NVIDIA Dynamo
- Source
- developer.nvidia.com
- Author
- Michelle Horton
- Date
Context
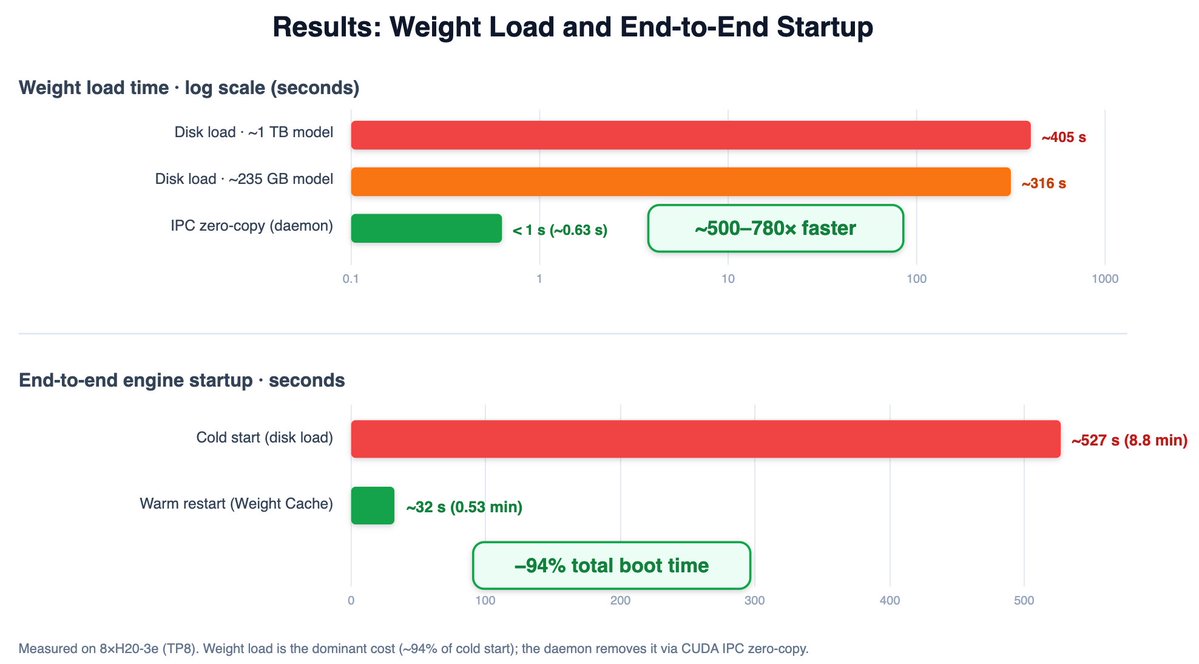
NVIDIA's Dynamo preview prepares a replacement process before the active one crashes. A separate memory service keeps model weights resident on the same GPUs, letting the standby share them while completing its own initialization. This avoids reloading the model during recovery, though the standby still consumes memory for its execution machinery. The engineering article explains the design.
In NVIDIA's synthetic, two-worker GLM-5.2 test on B200 hardware, the second worker resumed serving after 7.3 seconds, versus 283 seconds for a cold restart. That measures restored serving capacity after a process failure. Hardware and node failures remain outside the preview's scope, and the replacement starts without the previous process's cached conversation state.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…