Are AI labs pelicanmaxxing?
- Source
- simonwillison.net
- Author
- Simon Willison
- Date
Context
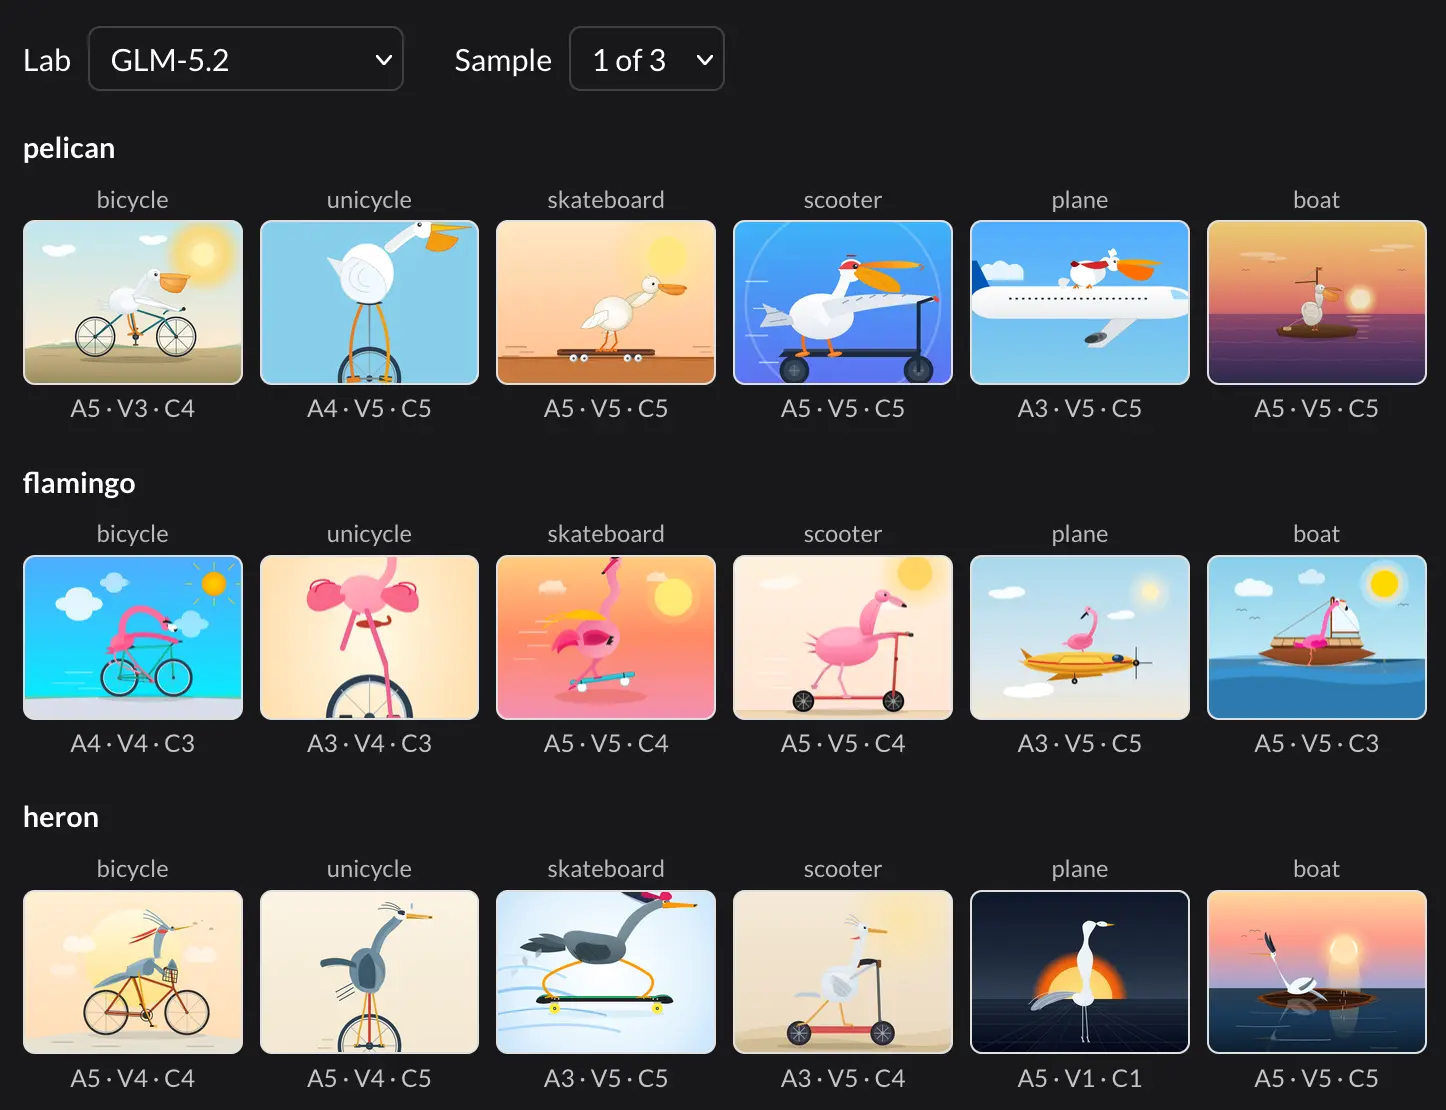
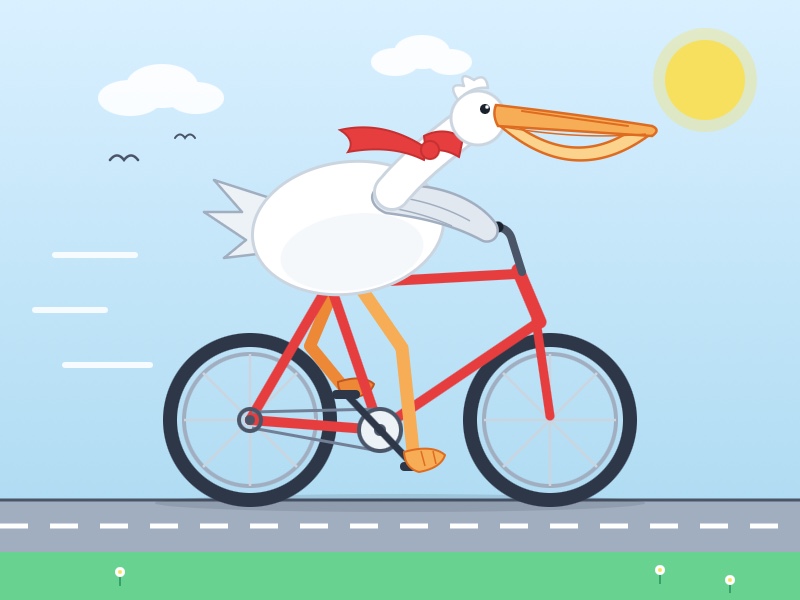
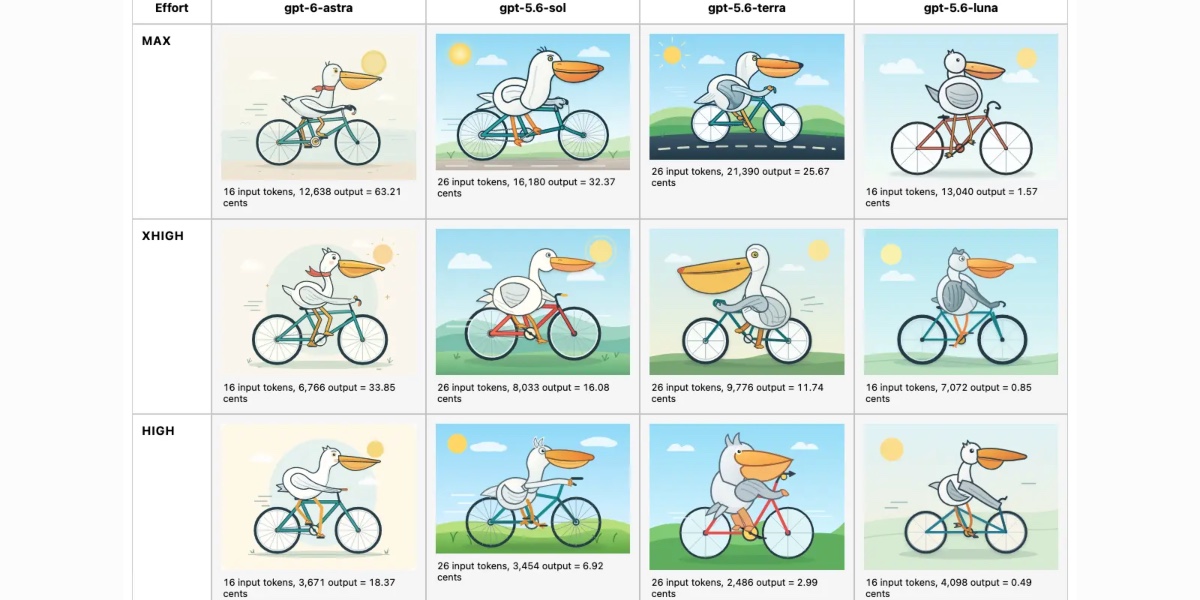
A famous drawing prompt did not receive a detectable special advantage in a small comparative test. Dylan Castillo investigated whether models had been optimized specifically for Simon Willison's pelican-riding-a-bicycle challenge. His experiment varied the animal and vehicle across 48 prompts, generated three drawings per prompt from seven models, and used an to score them.
The analysis found no statistically significant model-specific boost for the exact pelican-and-bicycle combination after accounting for drawing difficulty. That weakens the claim of an obvious special advantage on this prompt. It cannot establish what appeared in training: the experiment used few samples, relied on one scoring model, and could not detect improvements to drawing ability generally.
- The clean way to test for -gaming: score each model's animals and its vehicles separately, then check whether the one suspicious combination beats what those two baseline skills already predict. It did not, for any lab.
- Cross the variable you suspect against controls rather than testing it alone. A lab that trained on one famous prompt shows up as a single outlier cell, not as generally better drawing.
- Memorization leaves a signature: near-identical scenes across repeated runs. The pelican-on-bicycle outputs did not show it, which argues the models are composing rather than reciting a trained example.
- GLM-5.2 had the largest boost on the exact pelican-bicycle cell, but the effect was small and not significant. Naming the closest case and declining to conclude from it is the honest end of this kind of study.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
“Pelicans aren’t drawn any better than other animals. Bicycles aren’t drawn any better than other vehicles. And no lab draws the combination better than its pelicans and bicycles already predict.”
“GLM-5.2 comes closest: it has the largest boost on the exact pelican-bicycle cell, and and its first pelican-on-bicycle sample caught my eye. But the effect is small and not significant, so I wouldn’t put too much weight on it.”
Checking sign-in…
Loading comments…