Moonlight & Mayhem (Raccoon Heist by Codex + GPT-5.6 Sol Ultra)
Source
Simon Willison
Author
Simon Willison
Date
Terms in this piece · Glossary
subagent — A separate agent spawned by another to do one scoped piece of work in its own context, returning only the result.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Why it matters
A rare like-for-like comparison of two frontier coding agents on an identical one-shot build, including a concrete failure mode in AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → self-review that practitioners hit in their own loops.
Key quotes
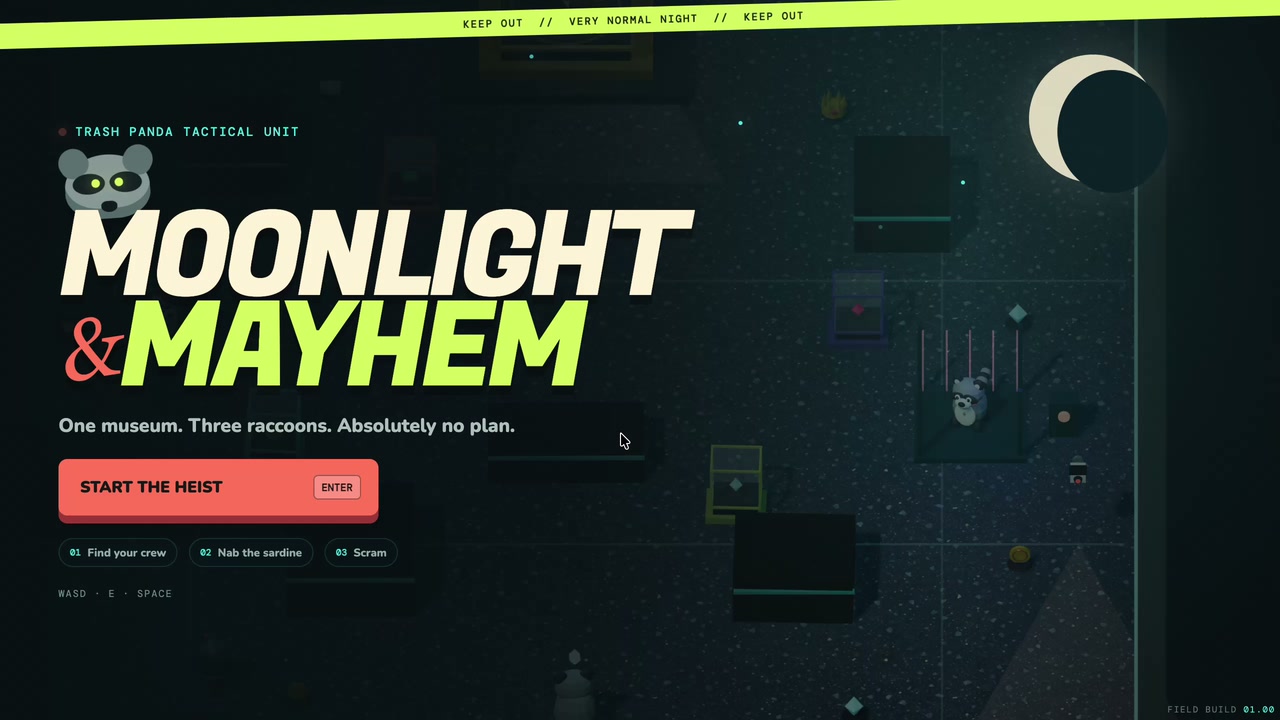
“I decided to pose the exact same prompt to Codex Desktop running GPT-5.6 Sol Ultra - the mode where Sol makes aggressive use of sub-agents - to see how it would do. It produced a much better game!”
“GPT-5.6 Sol has you in a museum, rescuing your two other raccoon crewmates in order to stack on top of each other and bust the golden sardine out of its case. Much more heisty!”
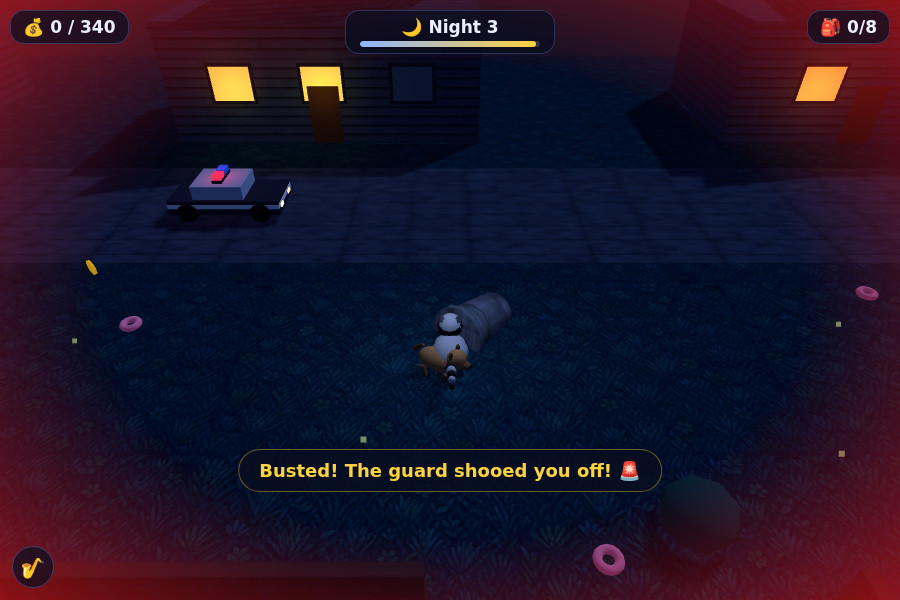
“Despite reviewing screenshots during development Codex failed to spot and correct this bug.”