What rebuilding AlphaGo teaches us about self-play, RL, and future of LLMs - Eric Jang
- Source
- youtube.com
- Author
- Dwarkesh Patel
- Date
Context
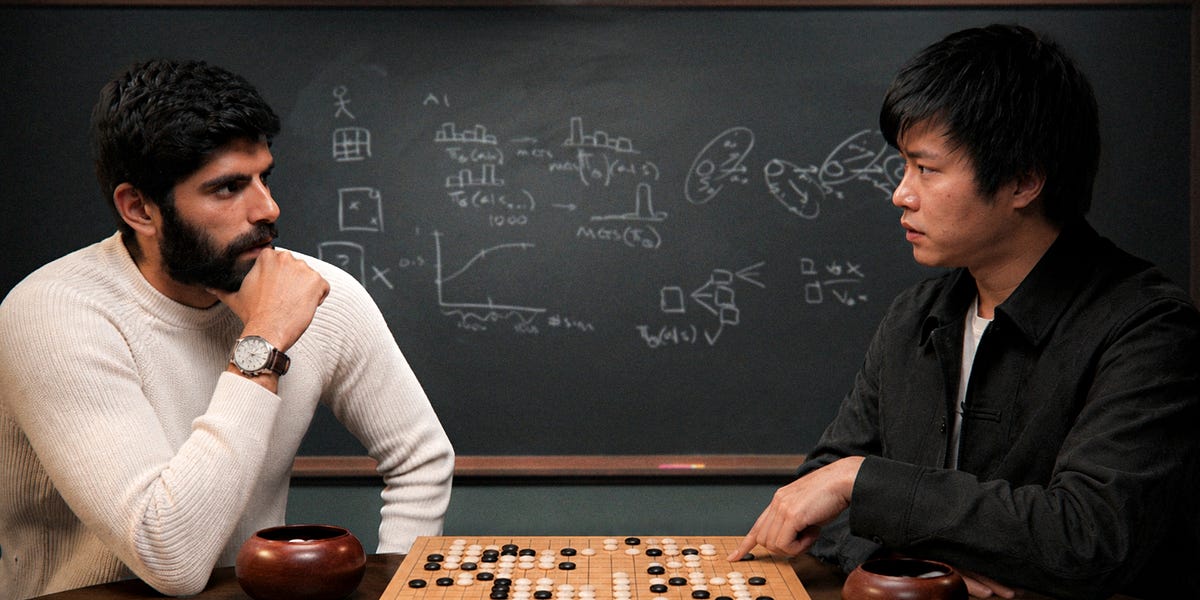
In a Dwarkesh Patel interview, Eric Jang, formerly VP of AI at 1X Technologies, rebuilds AlphaGo, and the opening explains why Go was long thought out of reach for search. A 19 by 19 board offers up to 361 moves per turn and games run 250 to 300 moves, so a naive tree of all possible games dwarfs the number of atoms in the universe. Jang says Google DeepMind's AlphaGo made this tractable with neural networks, and finds it mysterious that a ten-layer network can stand in for so deep a search.
Jang also argues the project is now cheap: the open-source KataGo cut the compute needed to train a strong Go program from scratch about 40-fold, and AI-assisted coding lets work that once took a DeepMind team and millions of dollars be done with a few thousand dollars of rented compute. That is Jang's own estimate, made before presenting the build.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.



Checking sign-in…
Loading comments…