Hy-MT2: open 33-language translation, down to 440MB on-device
- Source
- x.com
- Date

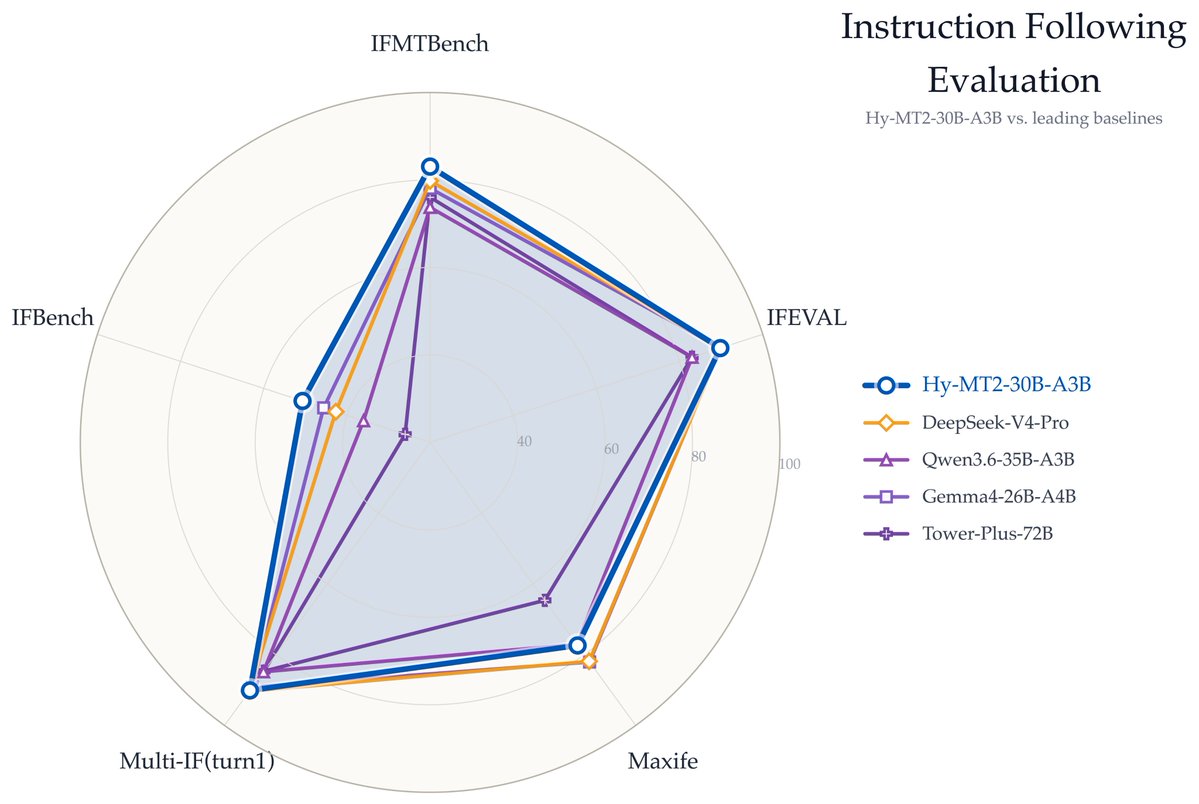
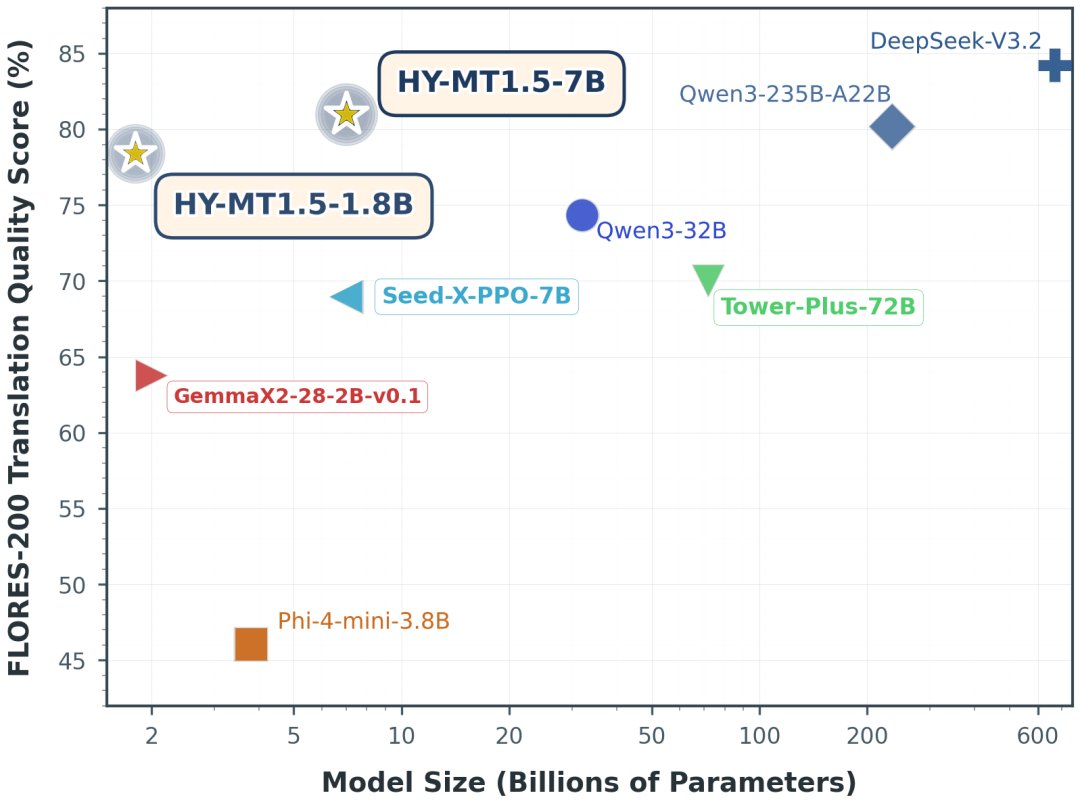
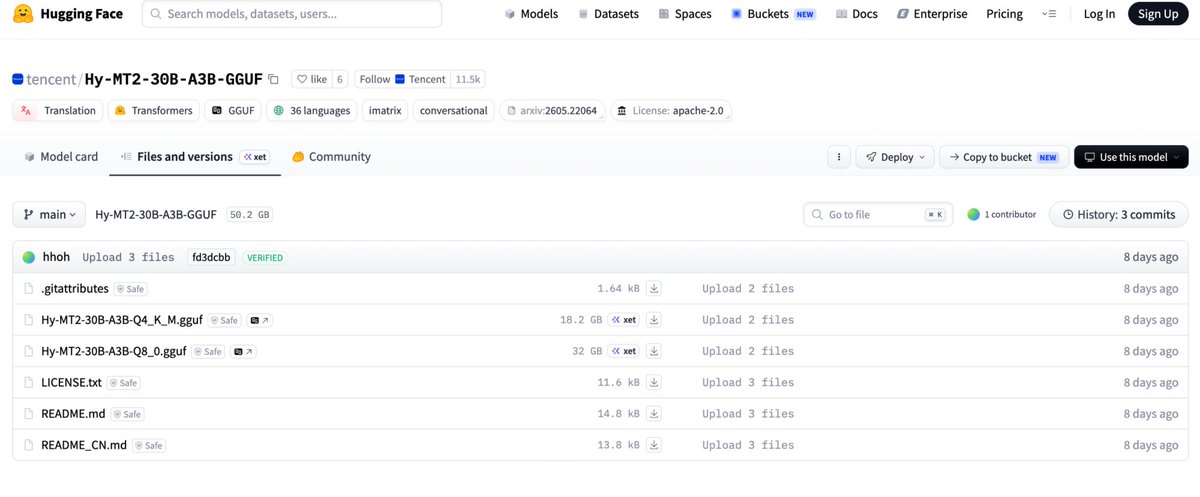
🚀 Introduce Hy-MT2: New Open-Source Multilingual Translation Model We proudly launch our new Hy-MT2 translation model and the Tencent Hy Translation mini-program! Hy-MT2 is a powerful multilingual model supporting seamless translation across 33 languages — and it's fully open-source! It's 7B and 30B-A3B models achieve state-of-the-art performance among all open-source models on various translation tasks, surpassing models with dozens of times more parameters. The lightweight 1.8B model even outperforms mainstream commercial APIs like Microsoft and so on. Powered by Tencent AngelSlim 1.25-bit extreme quantization, it needs just 440MB storage and enables effortless local inference on mainstream mobile chips — with 1.5x faster speed vs. Hy-MT1.5. Open-source AI translation just got way smarter, faster, and more accessible! 🌏 Project Page: https://t.co/eRkw3JLJjB Hugging Face: https://t.co/4J8gzMdcDu Modelscope: https://t.co/xh5vEYkHpo Github:


One More Thing. We are thrilled to announce that Tencent Hy is officially collaborating with the WMT26 organizers on the Preliminary Video Subtitle Translation Competition! 👉Join here: https://t.co/ToBl9njXIV Powered by our advanced Hy-MT series models, you can also take part in the General Machine Translation Competition. 📷 Join here: https://t.co/ZoradGSlpy Top participants have the chance to win special grand prizes! We warmly invite researchers, developers, AI enthusiasts, and everyone passionate about machine translation to join us. Together, let’s push the boundaries of AI and drive the future of machine translation technology forward! Don’t miss this incredible opportunity — register and participate today! #WMT26 #Hy #MachineTranslation #AIInnovationWe look forward to seeing your submissions!
Context
Tencent's Hy-MT2 translation family offers a small model for local deployment alongside larger alternatives, all supporting translation among 33 languages. The 1.8-billion-parameter version can be compressed to 440 MB of storage using reduced-precision weights. That makes the model easier to fit on a phone; the figure describes the stored model, rather than the complete memory requirement of a running application. The release documentation also describes following translation instructions, allowing an application to specify terminology or style alongside the text.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
 articleExplorationBench: Feedback and Self-Designed Probes Drive Agent Discovery
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…