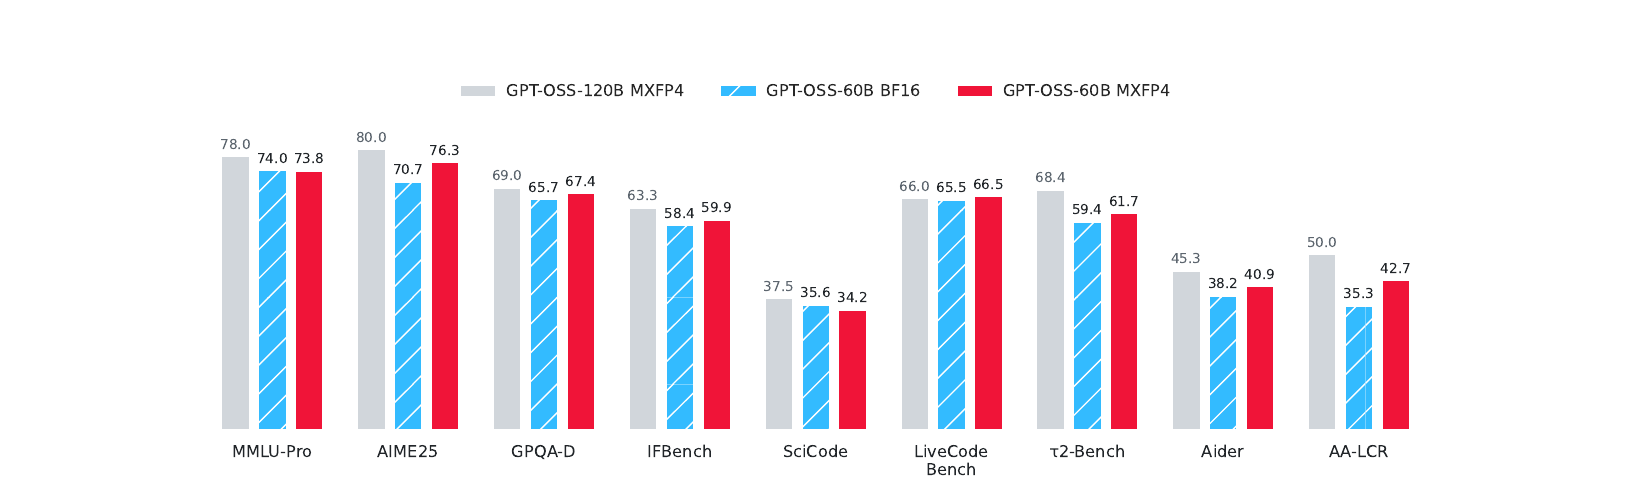
Quantization-Aware Healing: a compressed, 4-bit model that outperforms its full-precision original
Source
huggingface.co
Date
Context
Multiverse Computing reports that its 4-bit, 60-billion-parameter model beat a recovered 16-bit version of the same 60-billion-parameter model on seven of nine benchmarks. Its quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition →-Aware Healing method gives the compressed model additional training against the original, larger model's predicted outputs, teaching it while its weights use the lower-precision representation. This is the company's headline comparison. Company account.
The author subsequently acknowledged that the headline comparison gives the 4-bit model more training. It therefore cannot isolate whether the advantage comes from training under quantization or simply training longer. That qualification changes what the benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → win establishes.
Terms in this piece · Glossary
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.