Async GRPO with LoRA across HF Jobs: a bucket, a proxy, and no NCCL
- Source
- huggingface.co
- Date
Context
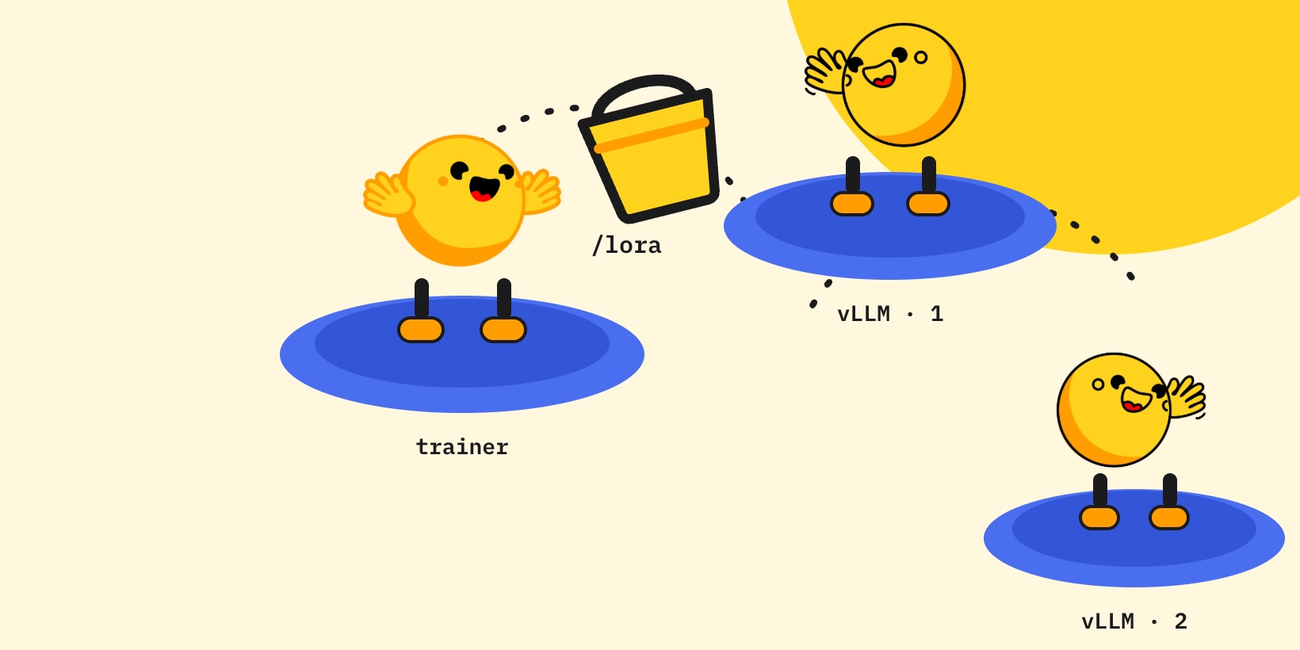
A Hugging Face training recipe runs asynchronous GRPO, a reinforcement-learning method, with training and response generation in separate cloud jobs. The connecting piece is : a small set of learned adjustments attached to the larger model. After an update, the generating workers receive those adjustments instead of another copy of all the model's parameters.
The trainer writes versioned adjustments to shared cloud storage and, through a small proxy, tells every generation worker to load the new version. Requests already under way can finish with the older version while new requests name the latest one. Because only small files move through storage, the separate jobs can exchange updates without NCCL, a GPU communication library that would otherwise carry full model weights between machines.
- LoRA — A cheap way to fine-tune a model by training a small add-on layer instead of changing all of the model's weights.
Checking sign-in…
Loading comments…