Route AI Agent Workloads Across Models with NVIDIA NeMo Switchyard
- Source
- developer.nvidia.com
- Author
- Michelle Horton
- Date
Context
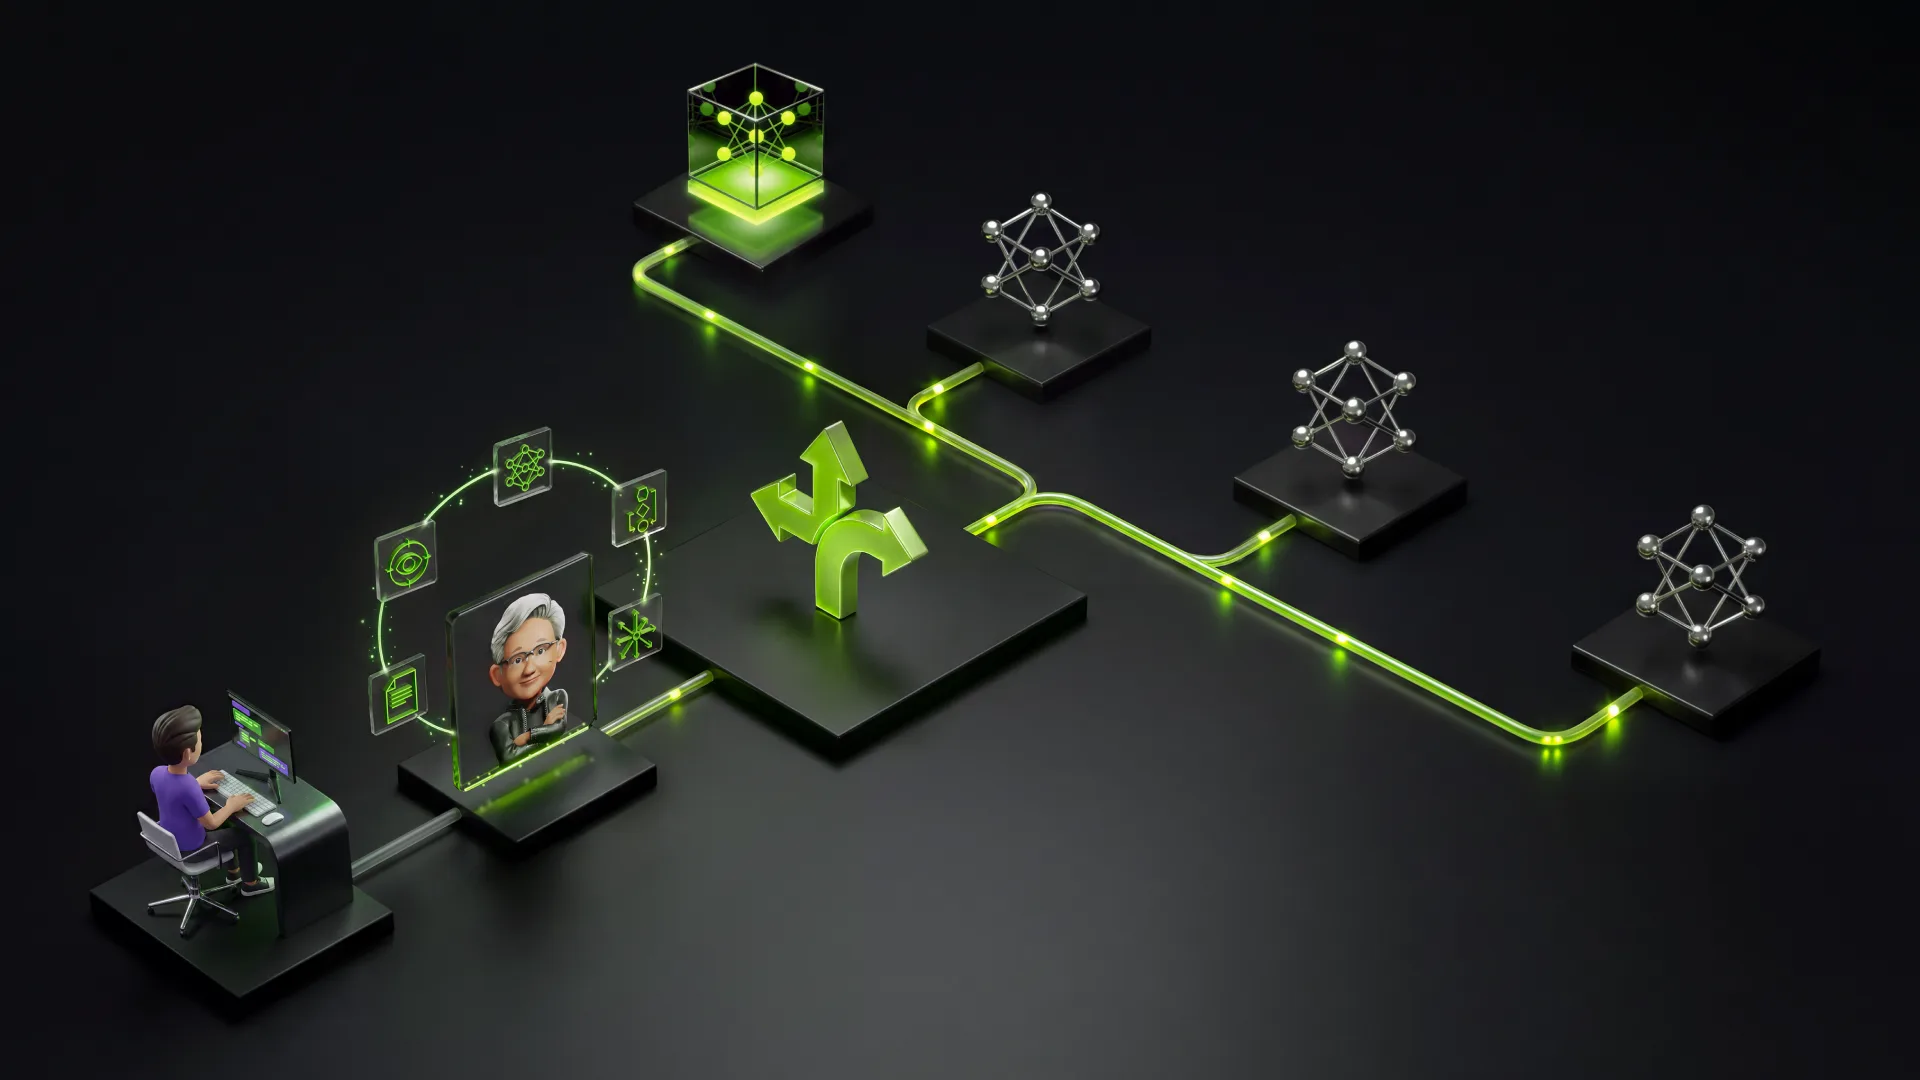
NVIDIA's NeMo Switchyard lets a coding change models as its work changes. Its stage router examines recent tool activity: repeated errors or prolonged exploration favor a more capable model, while steady writes and edits favor a more efficient one. This makes model selection responsive to the agent's progress rather than fixing one model for the entire job. The technical article explains the routing signals.
Switchyard also separates that decision from the provider connection that executes it. Each model target has a name, and a client behind it maps that name to a provider endpoint, so developers can change the endpoint without rewriting the routing integration. NVIDIA says this gives an agent runtime, platform or gateway control over how requests are served.
“For example, an agentic task may need classification for one step, reasoning for the next, and a smaller model for routine follow-up tasks. Sending every request to the largest model can increase cost and latency, while sending every request to a smaller model can reduce quality on complex tasks.”
Michelle Horton
“While DeepSeek V4 has the highest overall accuracy in this example, it isn’t the best model for every task group. For instance, Kimi K2.6 is better suited to the ML and RL task groups, while Qwen3.5 397B A17B is preferable for math and science.”
Michelle Horton
“For each turn, the stage router examines recent tool activity to decide how much model capability the agent needs. Severe errors, repeated unproductive work, or prolonged exploration push the turn toward the capable model. Steady writes and edits, especially once tests are passed, favor the efficient model.”
Michelle Horton
“Across five runs, routing requests between NVIDIA Nemotron 3.5 Lightning and Claude Opus 4.8 with the escalation router delivered a 74% cost reduction compared with a frontier-only baseline across five runs, sending just 7% of calls to the frontier model, at a measured ~6-point accuracy tradeoff.”
Michelle Horton
“On FrontierCode Main, Cognition’s benchmark for production-grade coding tasks, the implementation routed between Opus 5 and Kimi K2.7. It delivered near-frontier performance, achieving 50.6% at a $3.11 mean cost—within 2.8 percentage points of Opus 5 accuracy at approximately 28% lower mean cost.”
Michelle Horton
Checking sign-in…
Loading comments…