AssemblyAI ships Universal-3.6 Pro Realtime for voice agents
- Source
- x.com
- Date

Universal 3.6 Pro Realtime is live today. Two independent benchmarks put every streaming speech model through the same audio, on the same harness. Universal-3.6 Pro Realtime leads both. @trydaily's Pipecat open STT benchmark: Universal-3.6 Pro Realtime sits on the Pareto frontier. @covaldev's live leaderboard: lowest word error rate of any streaming model on real voice-agent audio. Voice agents get tested on the turns other benchmarks skip. That's where 3.6 Pro is built to hold: → Short answers. "No." "Nah." "Nuh-uh." Heard right 98.5% of the time, in loud rooms and on phone lines, not just quiet calls. → Background voices. The TV, the coworker, the next desk stay out of the transcript. → Languages. 32 from one endpoint with automatic detection. Callers switch languages mid-sentence and the transcript follows. Most agents can skip the language menu. → Turns. Entity-aware endpointing ends the turn when the caller is done, and holds it open while they're still reading out a phone number. Trained on tens of thousands of hours of real voice-agent and telephony conversations. Link in the comments. 👇
Context
AssemblyAI has released Universal-3.6 Pro Realtime, a speech-to-text model. It transcribes a caller's audio as the audio arrives, so a voice can respond during the conversation. The company's launch post says the model leads two independent benchmarks that run every streaming model on the same audio. On Daily's open Pipecat speech-to-text , it sits on the Pareto frontier, meaning no other tested model beats it on all of the benchmark's competing measures at once. On Coval's live leaderboard of real voice-agent audio, it has the lowest word error rate of any streaming model.
AssemblyAI's argument is that voice agents fail at moments that other benchmarks skip. A one-word reply such as "No" or "Nah" decides what the agent does next, and the company says the model hears these replies correctly 98.5% of the time, including in loud rooms and on phone lines. It also says the model keeps background voices such as a TV out of the transcript and follows callers who switch among its 32 supported languages mid-sentence. Another feature, entity-aware endpointing, decides when the caller has finished speaking but keeps the turn open while someone is still reading out a phone number. AssemblyAI says the model was trained on tens of thousands of hours of real voice-agent and telephony conversations.
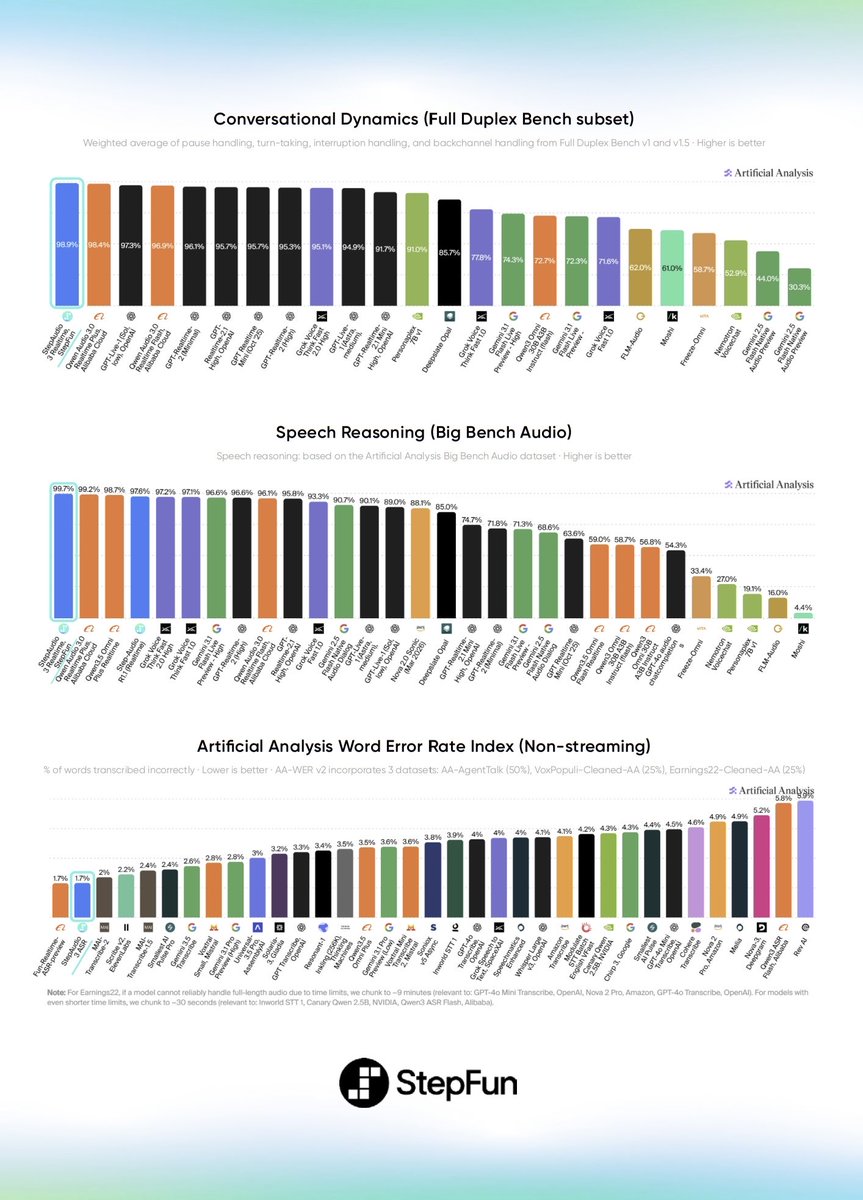
All of these claims come from AssemblyAI. The post's text does not give the benchmark scores, name the competing models, or explain how the 98.5% figure was measured. Its attached image may carry more detail but was not available, so the size of the lead cannot be judged from the text.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…