Introducing StepAudio 3, our new family of 5 audio models for real-time voice, speech recognition, speech generation, audio generation and music.
Realtime ranks #1 on Artificial Analysis for both Conversational Dynamics (98.9%) and Speech Reasoning (99.7%). ASR reaches 1.7% WER, matching the best result on the leaderboard.
Build voice agents that handle interruptions, reason while speaking, and call tools. Transcribe speech, generate expressive voices, and create full audio scenes and music.
Available now:
Voice AI Lab: https://t.co/9lQaKPc5AF
Blog:
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
Offers a real-time voice stack with concrete benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → numbers (98.9% conversational dynamics, 1.7% WER) for building interruption-aware, tool-calling voice agents rather than a bare TTS demo.


 article👏🏻Congratulations!Step3-VL-10B was selected for HuggingFace Daily Papers…
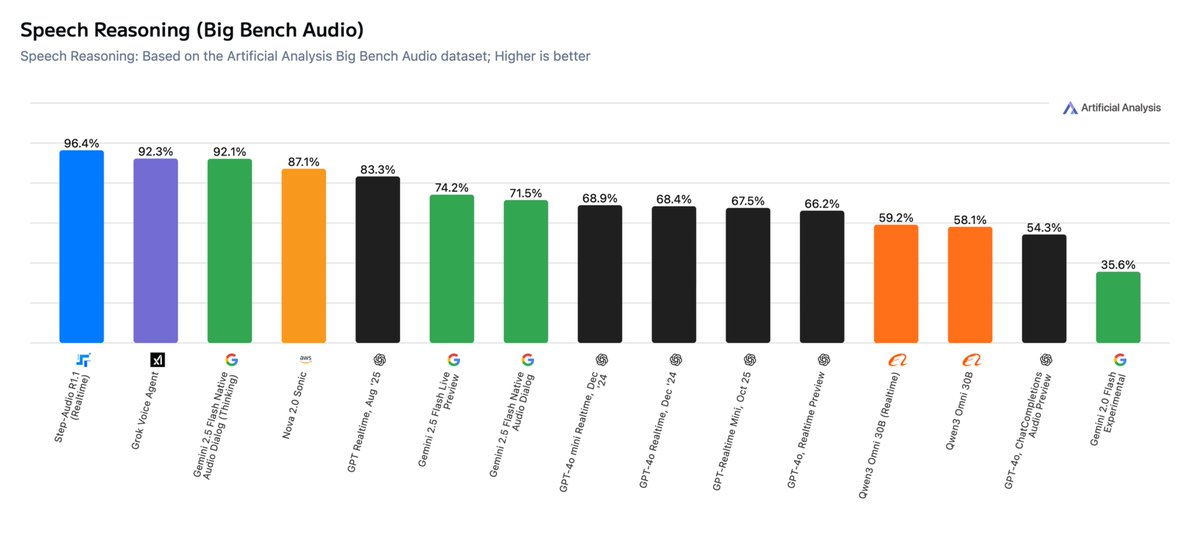 postStep-Audio-R1.1 opens weights for a speech model that reasons in real time