Multi-Vector (Late Interaction) Embedding Models with Sentence Transformers
Source
huggingface.co
Date
Context
Sentence Transformers v6 adds a way to search documents without compressing each entire passage into one numerical representation. Its MultiVectorEncoder retains a separate vector for each text unit, or tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →. At search time, it finds each query token's strongest match in the document and adds those matches into a relevance score. Release explanation
Documents can still be processed ahead of time, but individual details remain available for matching instead of being pooled into one summary. This offers a way to preserve specific requirements in a query, at the cost of storing and comparing more vectors. The tradeoff is finer-grained matching against index size and computation.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
 articleTraining and Finetuning Multi-Vector Embedding Models with Sentence Transformershuggingface.co
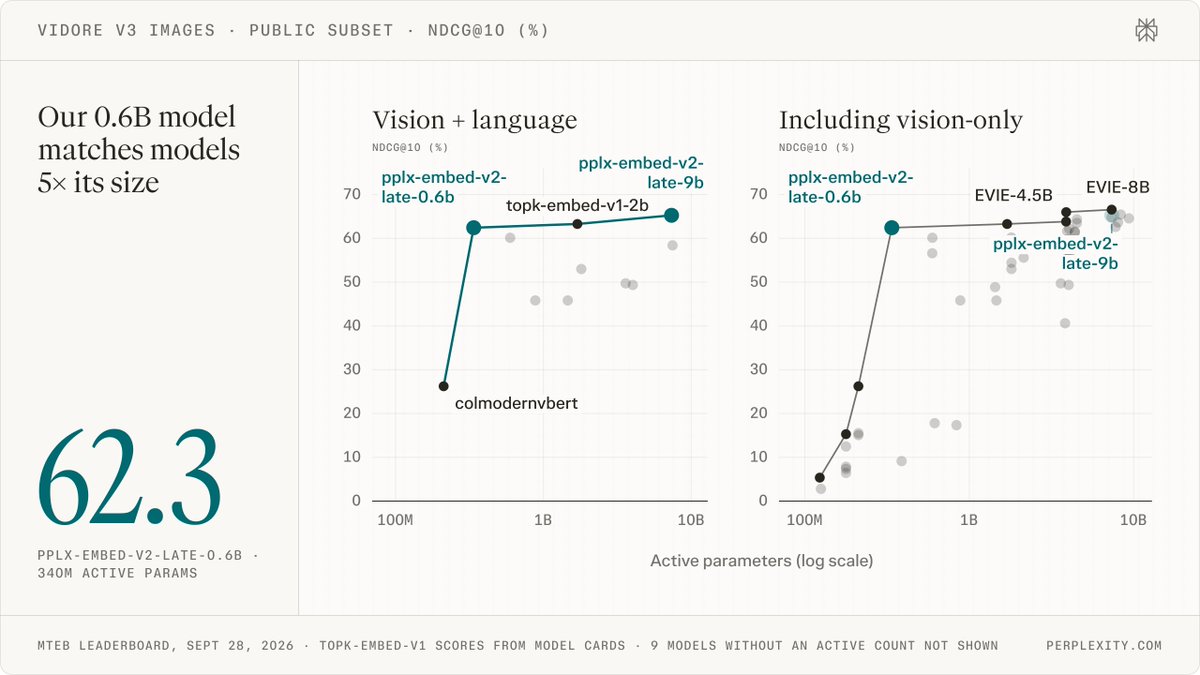 articlePerplexity Open-Sources Multimodal Late-Interaction Embedding ModelsPerplexity
 articleDenseOn with the LateOn: Fully Open Dense and Late-Interaction Models for Multilingual, Long-Context, and Code SearchRapha\"el Sourty, Antoine Chaffin, Paulo Roberto Moura Junior, Am\'elie Chatelain