Nemotron 3.5 Lightning completes tasks 5.36x faster than the most intelligent…
- Source
- x.com
- Date

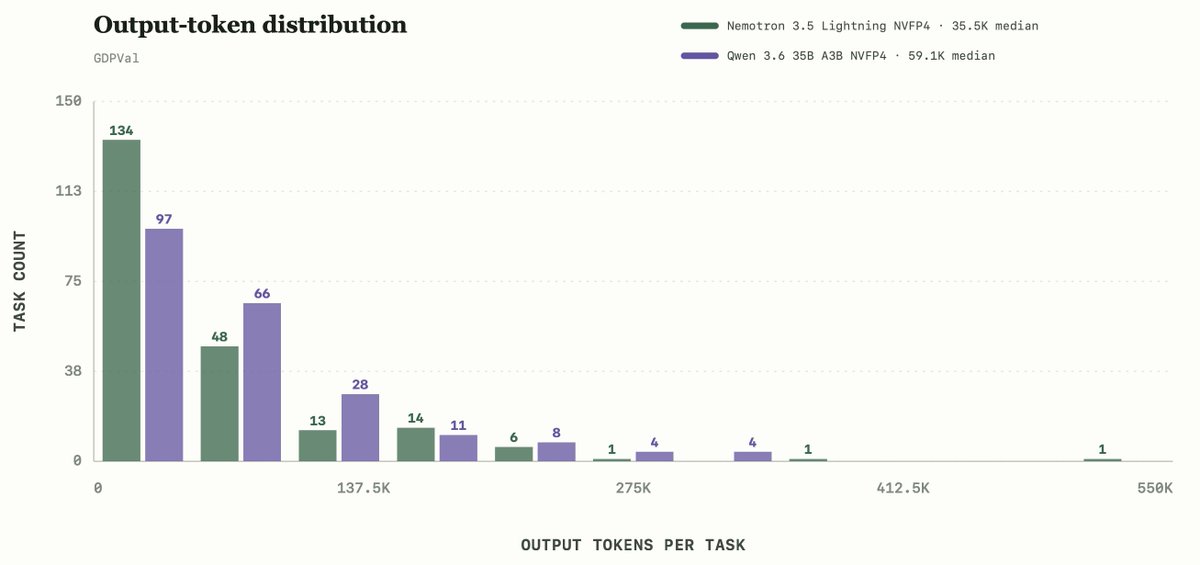
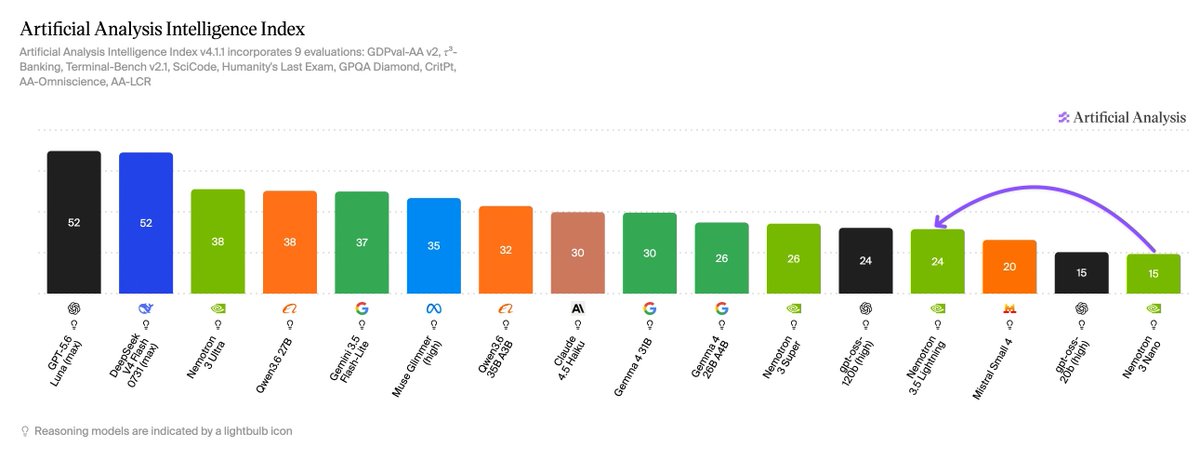
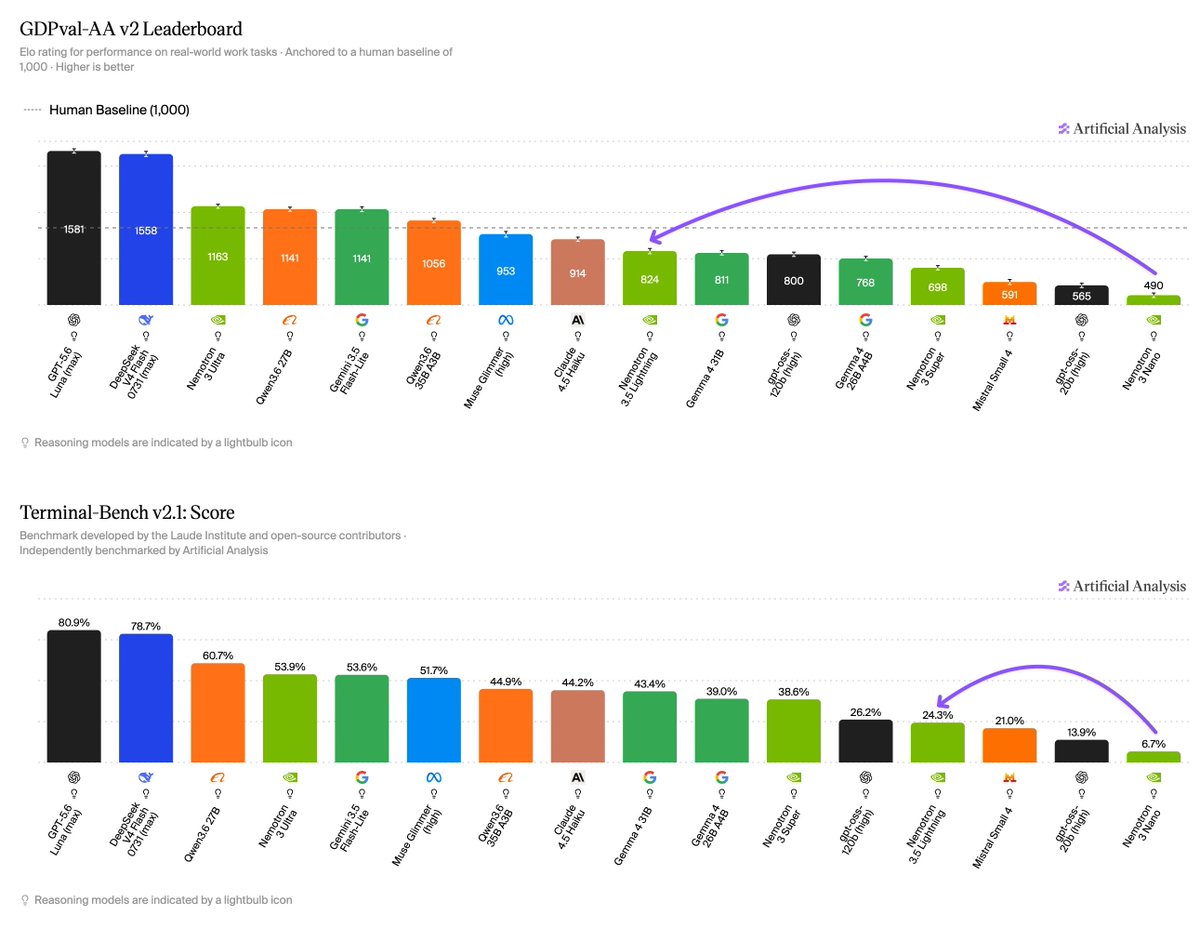
Nemotron 3.5 Lightning completes tasks 5.36x faster than the most intelligent model that runs on the DGX Spark (Step 3.7 Flash) while retaining 78% Intelligence. Why is it 5.36x faster? Despite being a much smaller model, Lightning uses about the same number of output tokens per task as Flash (on average ~2% more). However, it runs much faster per token on decode on DGX Spark, accounting for the 5.36x overall speedup.

Context
In Alex Cheema's DGX Spark comparison, Nemotron 3.5 Lightning completed tasks 5.36 times as fast as Step 3.7 Flash. Cheema attributes the difference to faster text generation: Lightning produced roughly the same amount of output, averaging about 2% more. Comparison and chart.
The chart also shows a capability tradeoff. Lightning's local.ai Intelligence Index score was about 78% of Step's score. That ratio describes this index, not the percentage of tasks Lightning solved or a general measure of retained intelligence.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
Checking sign-in…
Loading comments…