NVIDIA has just released the first Nemotron 3.5 model: Nemotron 3.5 Lightning, a
- Source
- x.com
- Date

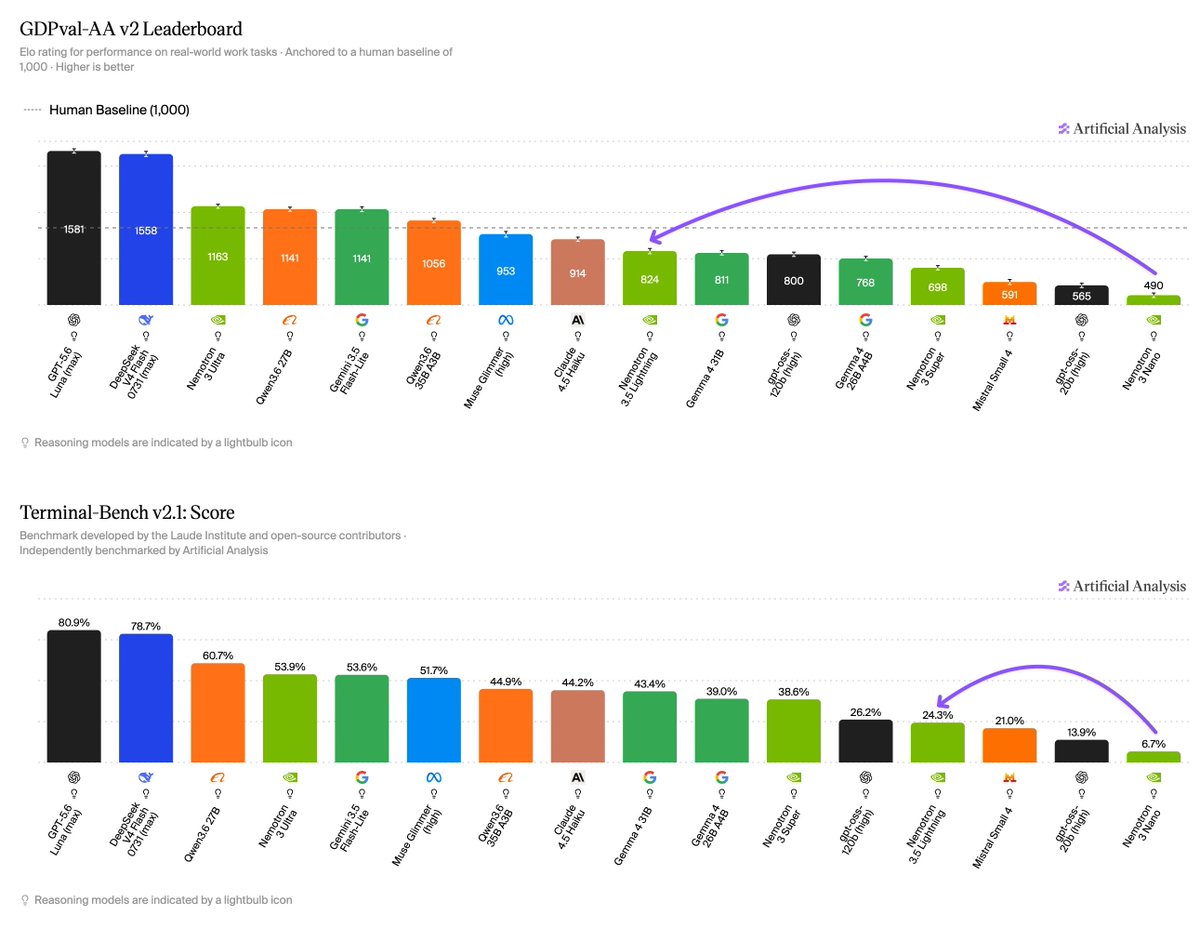
NVIDIA has just released the first Nemotron 3.5 model: Nemotron 3.5 Lightning, a highly efficient small open weights model with performance similar to gpt-oss-120b at around a quarter of the total parameters Nemotron 3.5 Lightning is the successor to @nvidia Nemotron 3 Nano 30B A3B, with 31.6B total and 3.6B active parameters. It retains the same hybrid Mamba-Transformer architecture and small size from Nemotron 3 Nano, but makes substantial gains in intelligence and agentic performance. Key takeaways: ➤ Major intelligence jump: Nemotron 3.5 Lightning scores 24 on the Artificial Analysis Intelligence Index, a +9 point improvement over Nemotron 3 Nano (15). This puts it in line with OpenAI's gpt-oss-120b (24) and only just behind Nemotron 3 Super (26), a model ~4x its size ➤ Optimized for efficiency: Nemotron 3.5 Lightning sits behind the most intelligent small models in its size class such as Qwen3.6 35B A3B (32) and Muse Glimmer (high, 35) - but it is built for a different point on the frontier. In pre-release testing of a DeepInfra endpoint serving the final NVFP4 weights, we measured median output speeds of nearly 670 tokens per second, much faster than those models are…

Context
NVIDIA's Nemotron 3.5 Lightning is a small open-weights model built for speed rather than for the top score in its class. Artificial Analysis, which runs independent model benchmarks, measured it at 24 on its Intelligence Index, up from 15 for its predecessor, Nemotron 3 Nano, and level with OpenAI's gpt-oss-120b, a model with about four times as many total parameters. Lightning has 31.6 billion parameters in total but uses only 3.6 billion of them for each .
Speed is where it stands out. In pre-release testing of a DeepInfra endpoint, Artificial Analysis measured median output of nearly 670 tokens per second, much faster, it says, than the higher-scoring small models in its size class are served today. Those models lead on the index: Qwen3.6 35B A3B at 32 and Meta's Muse Glimmer (high setting) at 35. Muse Glimmer is a 30-billion-parameter model that uses all of its parameters for every token; Artificial Analysis's separate assessment of it covers that score and where the model is weak. Lightning's biggest gains over Nemotron 3 Nano came on tasks, where a model works through multi-step jobs: Terminal-Bench v2.1 rose from 7% to 24%, and on GDPval-AA v2 it moved past gpt-oss-120b and Nemotron 3 Super. Artificial Analysis concludes that this speed, plus a license open for commercial use, suits it to high-volume agent deployments.
The speed figure comes from the NVFP4 weights, a compact four-bit number format that NVIDIA ships alongside higher-precision BF16 weights. Artificial Analysis also scored the NVFP4 version at 24 and saw minimal loss against the higher-precision weights, so the speed was not bought with a lower index score. Only the main post was read; replies to it were not collected, and the attached chart was not inspected.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
Checking sign-in…
Loading comments…