Contrastive Representation Learning
- Source
- lilianweng.github.io
- Author
- Lilian Weng
- Date
Context
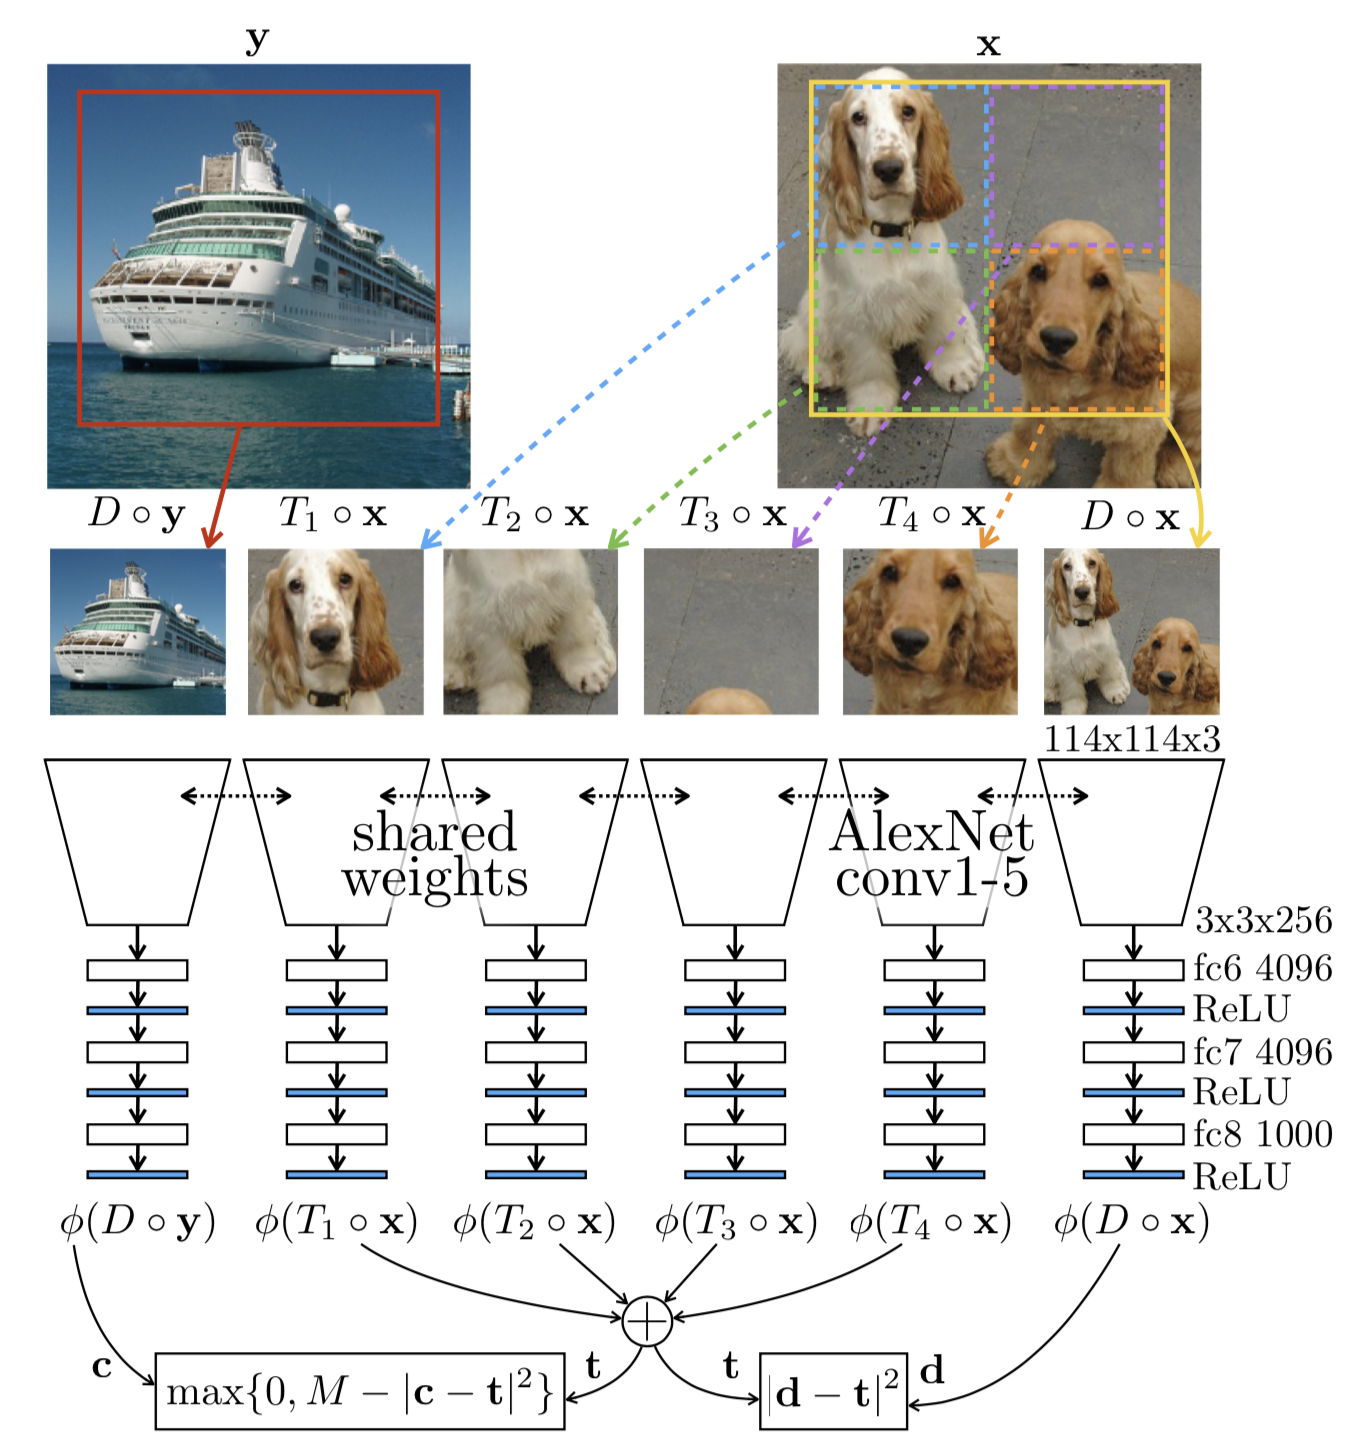
A model can learn useful image representations by recognizing two altered views of the same image. Lilian Weng's contrastive learning survey describes training that places related examples close together in a space of numerical features while separating unrelated examples.
Crops and color changes can create related pairs without requiring a person to label every image. The transformations teach the model which differences it should ignore. Their choice matters: they need to preserve the meaning relevant to the task. Likewise, treating another image as unrelated can be misleading when it actually belongs to the same category. Pair construction determines much of what the model learns to regard as similarity.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
“The goal of contrastive representation learning is to learn such an embedding space in which similar sample pairs stay close to each other while dissimilar ones are far apart. Contrastive learning can be applied to both supervised and unsupervised settings.”
Lilian Weng
“Proper data augmentation setup is critical for learning good and generalizable embedding features. It introduces the non-essential variations into examples without modifying semantic meanings and thus encourages the model to learn the essential part of the representation.”
Lilian Weng
“Only when the batch size is big enough, the loss function can cover a diverse enough collection of negative samples, challenging enough for the model to learn meaningful representation to distinguish different examples.”
Lilian Weng
“Chuang et al. (2020) studied the sampling bias in contrastive learning and proposed debiased loss. In the unsupervised setting, since we do not know the ground truth labels, we may accidentally sample false negative samples. Sampling bias can lead to significant performance drop.”
Lilian Weng
“SimCLR ( Chen et al, 2020 ) proposed a simple framework for contrastive learning of visual representations. It learns representations for visual inputs by maximizing agreement between differently augmented views of the same sample via a contrastive loss in the latent space.”
Lilian Weng




Checking sign-in…
Loading comments…