[AINews] Jev: a “System One Model” that only decides/classifies/routes/scores — >100x faster, >200x cheaper than small frontier LLMs
- Source
- latent.space
- Date
Context
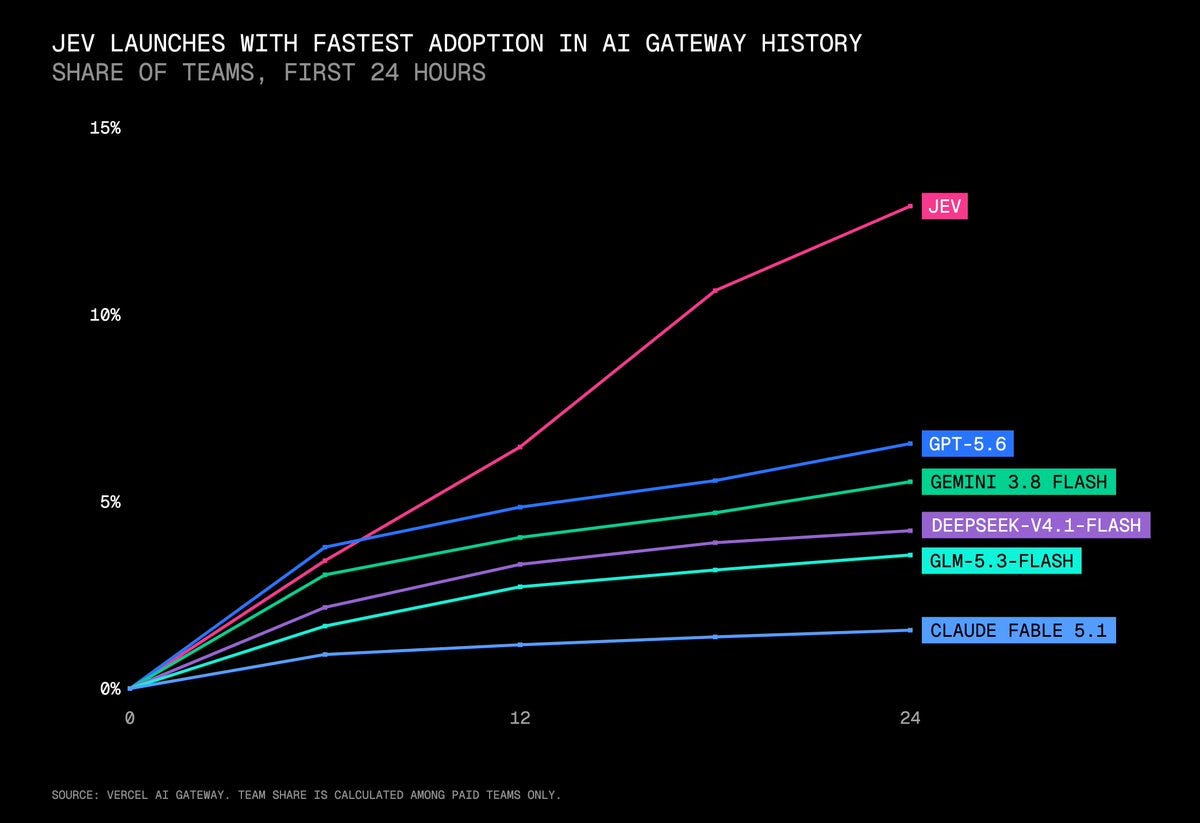
TypeSafe AI's Jev returns predefined decisions and probability estimates that software can use directly. A developer supplies the information to assess and defines possible outputs, such as classifications or scores. The company's launch explanation says Jev produces those outputs in parallel in a single query, avoiding the one-piece-at-a-time text generation used by chat models.
This makes Jev relevant to repeated decision points inside applications, where surrounding code determines what happens next. TypeSafe describes its confidence estimates as , meaning higher confidence is meant to track higher accuracy, which is intended to let that code decide when to act or request review. The large speed and cost multipliers come from TypeSafe's own workflow evaluations, which the company says likely represent the higher end of real-world gains.
- Periodic Labs trained its Neon model on real experimental data from physical labs, not just text, using 1,300 H200 GPUs; on an internal XRD-analysis , success reportedly jumped from 2.7% to 55.3%, beating GPT-6 Astra and Claude Fable 5.1 at lower cost.
- A Microsoft paper found agents given plain bash access outperformed ones restricted to a typed tool catalog by 21.8-24.5 points on TheAgentCompany and 4.8-7.4 points on APEX-Agents, while using fewer tokens, evidence rigid tool schemas can cost more than they protect.
- Perplexity says it built CobbleDB, a DynamoDB replacement for its search serving, using two engineers plus hundreds of persistent AI agents over two months; it reports median batch-read latency dropping from 31.4ms to 5.6ms and at least 20% cost savings versus DynamoDB.
- Gemini 3.8 Live Extended Thinking (High) debuted #1 on Artificial Analysis's speech-to-speech index at 82.6, just ahead of GPT-Live-1 Astra's 81.5, while pricing at $3.50/hour input audio versus $0.84/hour for the cheaper standard Live tier.
- Third-party auditors probing AI systems through the API may get different results than testing the consumer chatbot interface directly, researchers report, a mismatch that matters because regulators and labs often rely on API-only access for external review.
- calibration — How well a model's confidence matches reality — a calibrated model saying "90% sure" is right about 90% of the time.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…