How NVIDIA's LPU splits prefill and decode, and what GPTOSS 2T actually measures
- Source
- x.com
- Date

NVIDIA LPU supports 3 types of disaggregated inferencing: 1. Rubin Prefill + LPU Decode for the fastest interactivity 2. Rubin Prefill + Rubin Decode Attention + LPU Decode FFN for the middle of the curve 3. Rubin Prefill + Rubin Decode Verification + LPU Drafter for the middle-left of the curve For low interactivity, raw Rubin still takes the win. Looking forward to seeing Rubin + LPU performance curves on open-source agentic benchmarks like AgentX.

GPTOSS 2T is a proxy model, a made-up model config (layer counts, hidden dims, expert counts, etc.) created by scaling up the GPTOSS 120B architecture so that hardware teams can use it as a stand-in for frontier closed models they can't actually run, like GPT-5 or Gemini. NVIDIA can't benchmark on the real weights. This is standard practice for hardware architecture & bring-up teams.
Context
NVIDIA's combined Rubin and LPU configurations divide the work of answering a prompt between different processors. In one arrangement, Rubin processes the input and passes its stored calculations to the LPU system, which generates the response. Other arrangements divide internal computations or have one system draft text that the other checks. NVIDIA's technical account explains how each configuration assigns work to the hardware suited to it.
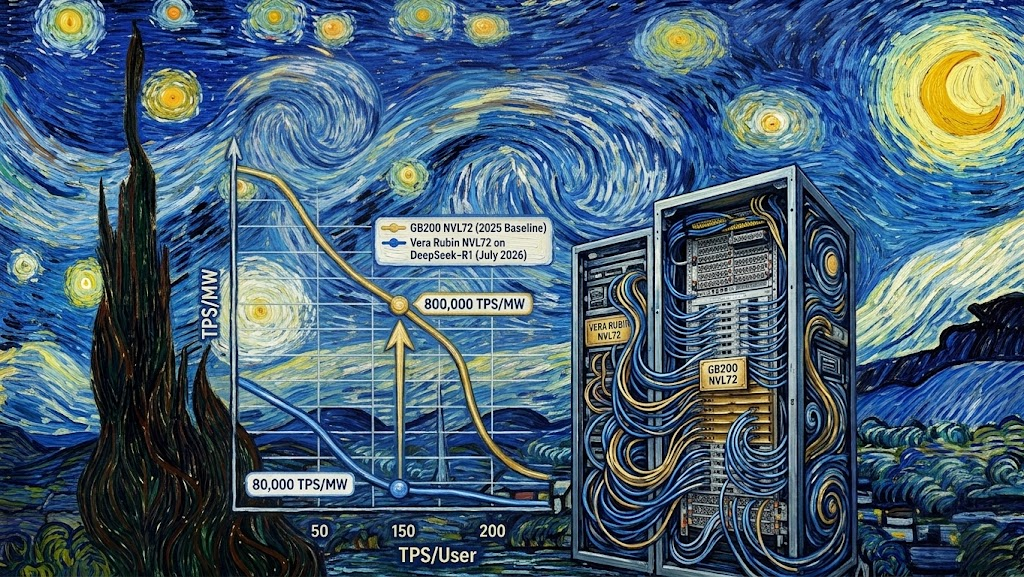
The associated GPT-OSS-2T performance curve is a projection using a scaled-up model configuration. Its axes compare response speed per user with aggregate throughput per unit of power. It illustrates a projected hardware tradeoff, rather than a measured run of an available two-trillion-parameter model.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…