Vera Rubin NVL72 vs GB200 NVL72? Inference TCO & Architecture Analysis
Source
Alec Ibarra
Author
Alec Ibarra
Date
Key takeaways · AI-distilled
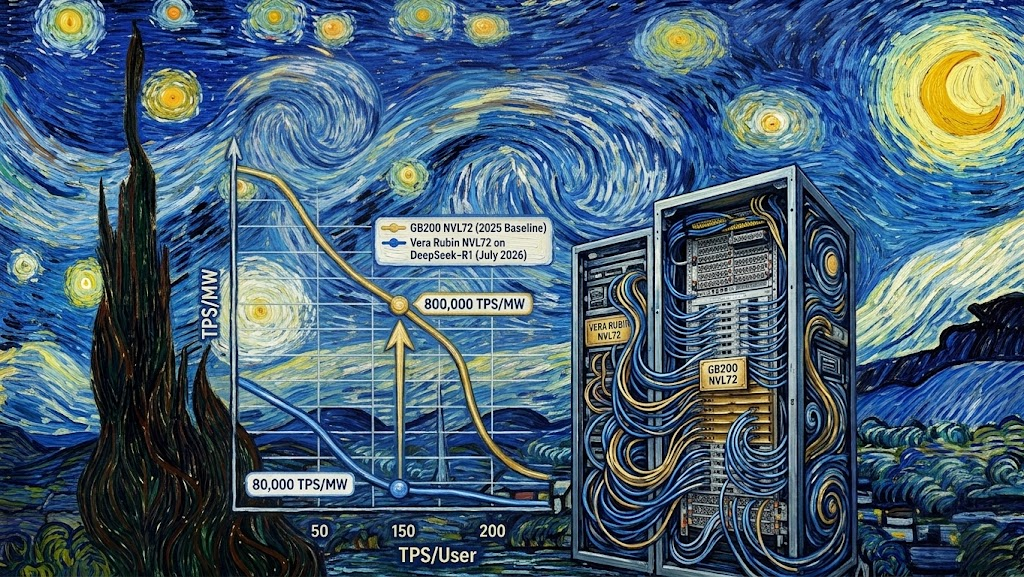
Engineering-sample Vera Rubin NVL72 racks running DeepSeek R1 show 5.4x the performance per megawatt and 5x per dollar versus GB200 NVL72. The numbers come from CoreWeave and are unverified; Nvidia has promised audited InferenceX submissions by Q3 2026.
Rubin runs Blackwell's SM100 kernels unchanged, so DeepGEMM, FlashMLA and CUTLASS work on day one. Hopper-to-Blackwell required rewriting kernels from scratch. Peak performance still needs Rubin-specific tuning, but time-to-market no longer waits on it.
Rubin's TMA, the async memory-copy engine, can override a descriptor field inline, so one descriptor covers every expert in a mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → layer. Blackwell had to rewrite the descriptor in memory and synchronize on each expert switch.
Rubin extends 2:4 sparsity to activations at runtime: keep two of every four values, skip the rest, run the matrix multiply at double rate. No retraining needed, unlike Ampere's weight sparsity that nobody adopted. Nvidia has published no accuracy data.
A new lookup-table mode stores each weight as a 3-bit index into a table held in Tensor Memory. The Tensor Core reconstructs the value inside the multiply and runs at FP8, so there is no separate dequantization pass.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
Why it matters
Per-dollar and per-watt inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → deltas of this size reset the build-versus-rent calculation.
Key quotes
“Vera Rubin NVL72 running DeepSeek R1 delivers 5.4x performance per MW and 5x performance per dollar over GB200 NVL72 today, and the gap is even wider against GB200 NVL72 during its early bringup in 2025.”
“Blackwell was not able to reuse Hopper WGMMA kernels, Rubin is able to reuse Blackwell's kernels, which makes the software bring up process much smoother.”
“Nvidia shipped 2:4 on weights back in Ampere and nobody used it, because it meant pruning the model and retraining. Rubin applies it to activations at runtime, so no retraining is needed.”
“Rubin is a little over 2x cheaper at low speeds, peaks near 8x at 150 tok/s/user, and then moves back to 5x by 200 tok/s/user.”