8-bit Qwen3.8-27B decodes 1.7x faster than BF16, slower at 16K context
Source
github.com
Author
gltanaka
Date
Context
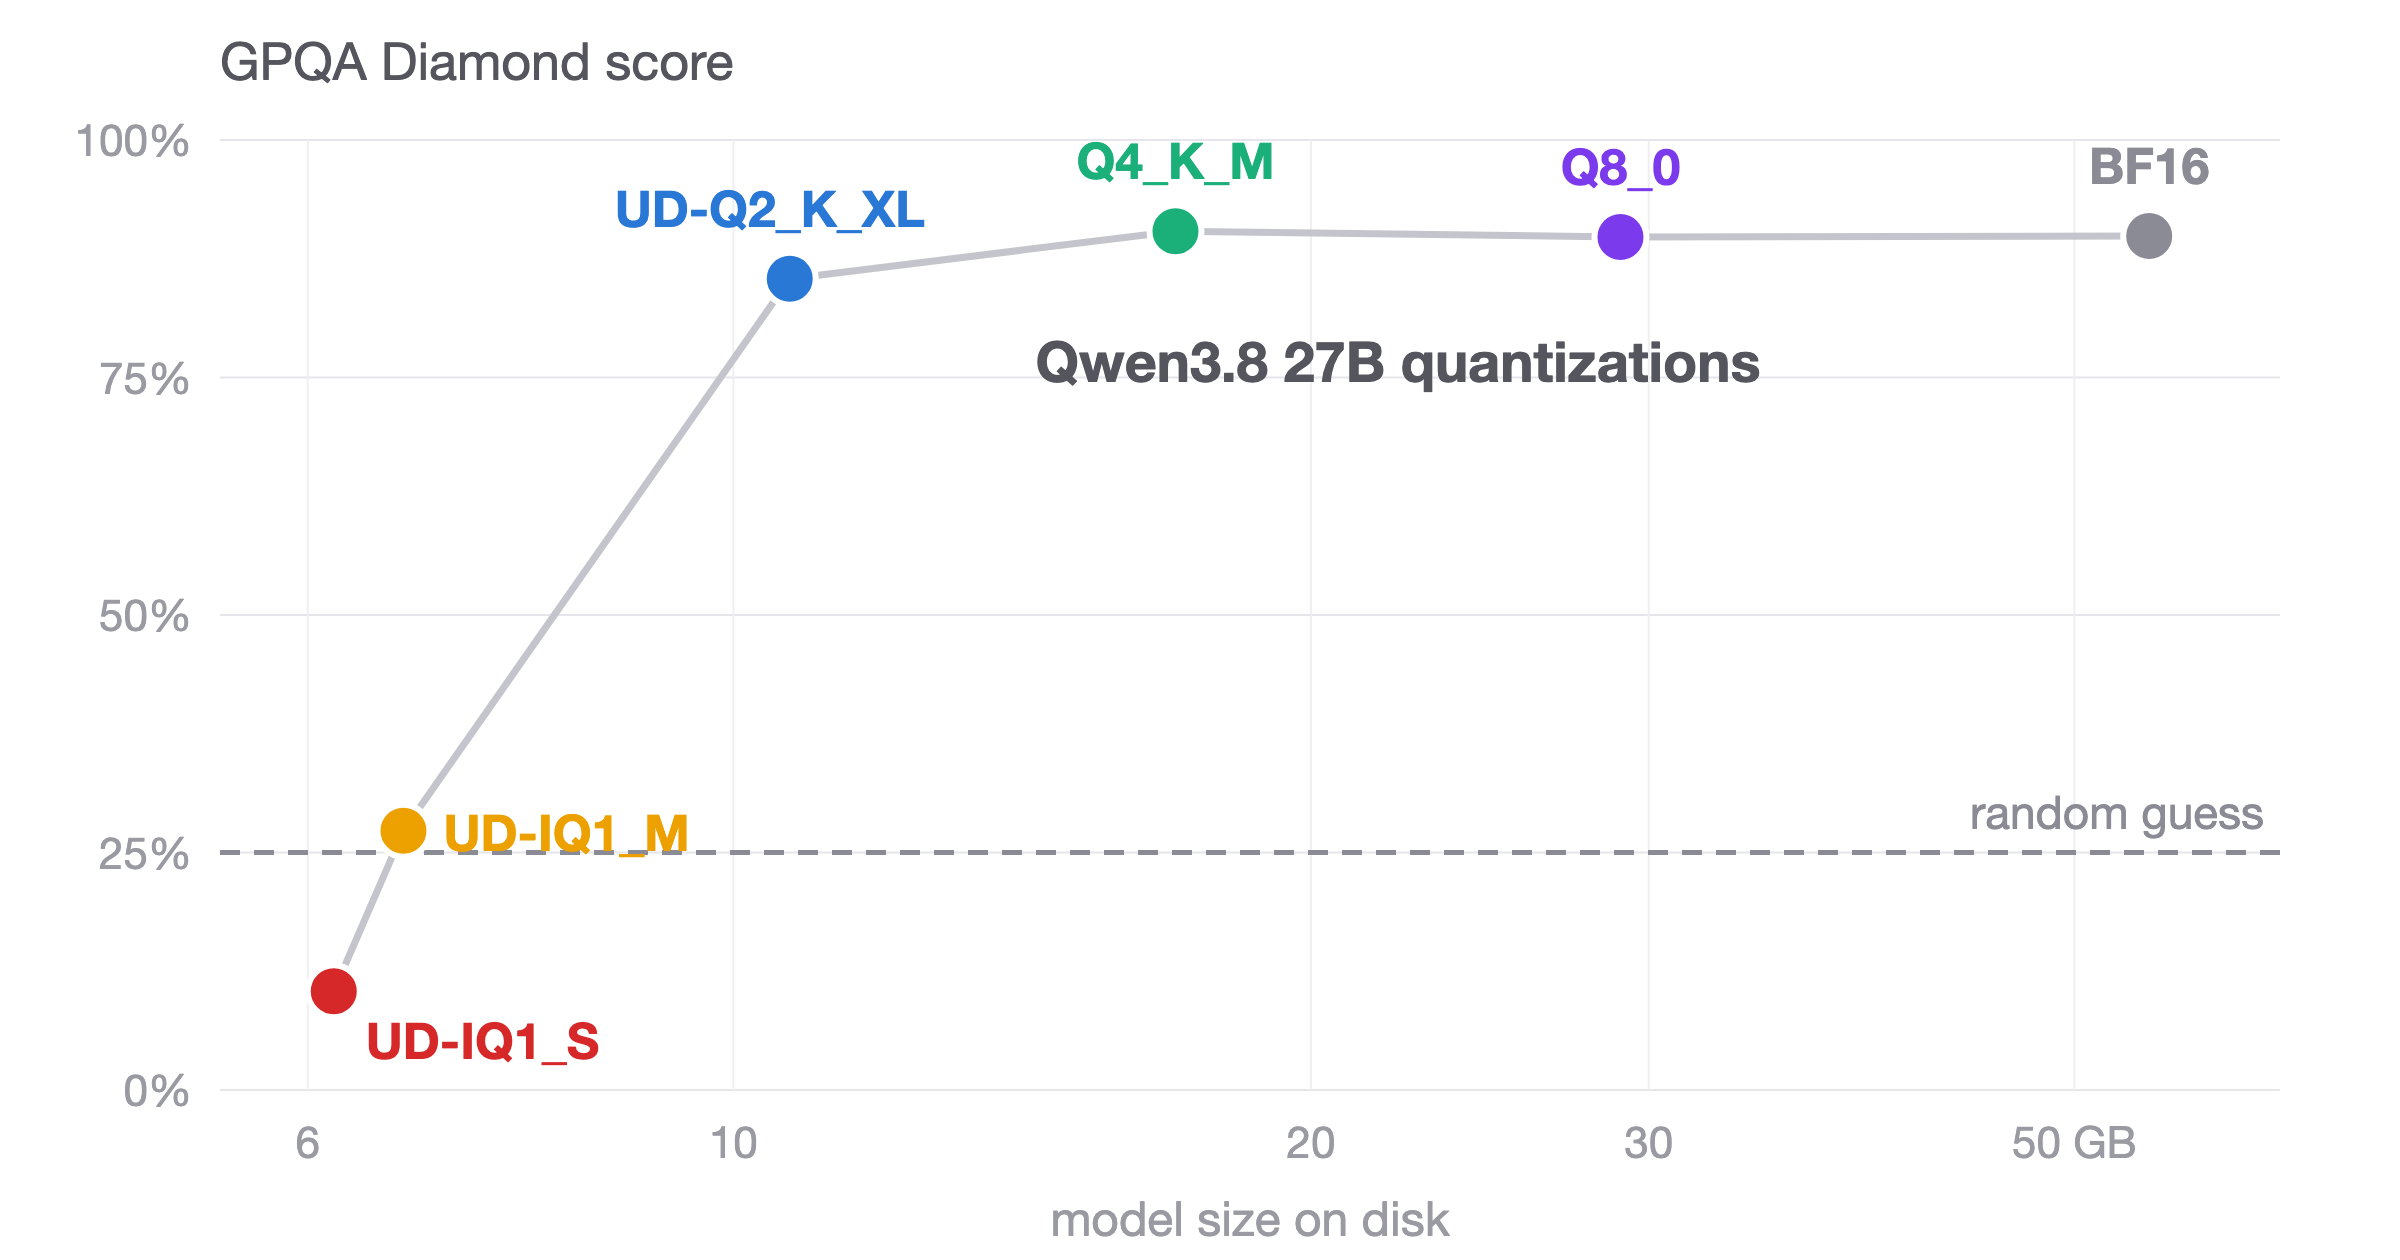
Faster text generation did not mean a faster complete response in this local Qwen comparison. On an M4 Max with 128 GB memory, an eight-bit version of Qwen3.8-27B generated output about 1.5–1.7 times as fast as the BF16 version in one test session.
For the 16,384-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → prompt, however, its total response time was about 12.5% longer. Processing the long input and reaching the first output dominated the request. The result shows why a local-model comparison needs complete request latency alongside generation speed; this fixed-order, single-session test does not establish a universal advantage.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.