NVIDIA's research lands in other labs' models, not its own Nemotron3 Ultra
- Source
- x.com
- Date

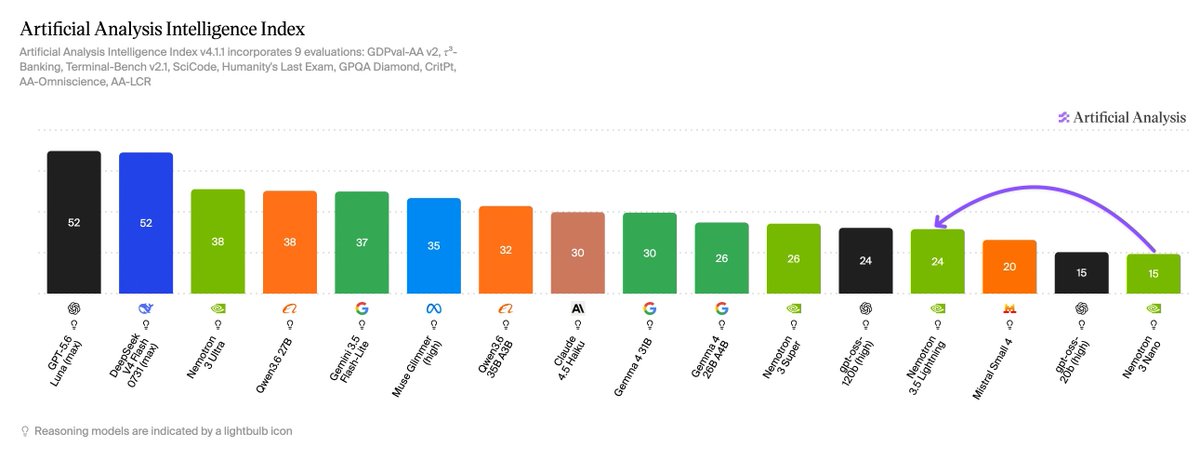
NVIDIA Research 🚀 has produced some great research, like LatentMoE (used in Kimi K3) and GatedDeltaNets (used in Qwen). But for e2e frontier training, NVIDIA's bureaucratic culture has produced embarrassing models like Nemotron3 Ultra. Despite NVIDIA Research having amazing talent, Nemotron3 Ultra, with 550B total params (55B active), is getting mogged by all the Chinese models, including even Qwen3.8 27B parameters, which has ~20x fewer parameters.

Context
SemiAnalysis, an industry analysis outlet, argues that NVIDIA's research division has produced techniques used inside other labs' models, citing LatentMoE inside Moonshot AI's Kimi K3 and GatedDeltaNets inside Alibaba's Qwen models, but that NVIDIA's own frontier training effort, which it attributes to the company's internal culture, has not matched that research output. It says NVIDIA's Nemotron3 Ultra, at 550 billion total parameters with 55 billion active, trails several Chinese models including Qwen3.8 27B, which has roughly 20 times fewer parameters.
SemiAnalysis does not name which produced that specific comparison in the post text, and the supporting chart is an image this review could not independently verify, so the ranking claim is presented here as the outlet's own assessment rather than a cited, reproducible score.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…