DeepSeek V4.1 Flash 1017 released
- Source
- huggingface.co
- Author
- DeepSeek model releases
- Date
Context
DeepSeek-V4.1-Flash-1017 is a minor update to DeepSeek's V4.1-Flash model, whose launch is covered in an earlier Intel item. The new version is published as downloadable weights on Hugging Face under the permissive MIT license and accepts images as well as text (huggingface.co). DeepSeek says it improves reasoning, coding, agentic and visual results while cutting execution time and output length, so tasks finish faster and cost less.
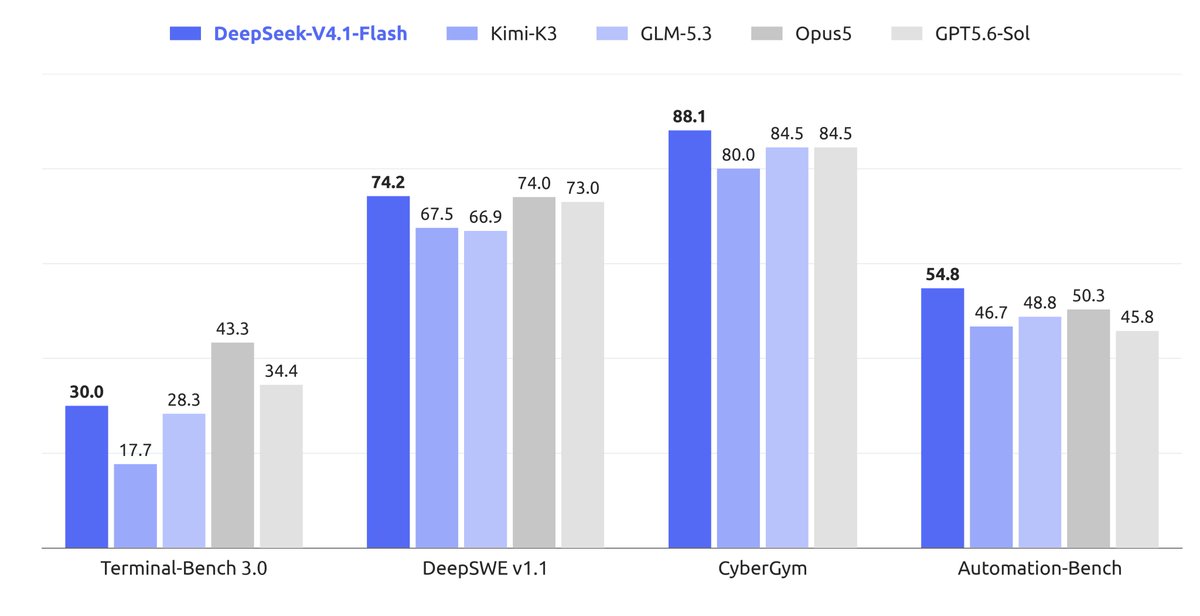
The model card's table puts numbers on part of that. The largest gains over the previous V4.1-Flash are on agentic coding: Terminal-Bench 4.0 rises from 31.2 to 42.3 and ProgramBench from 20.3 to 29.1, with Apex Bench v1.1 up from 64.6 to 72.1 and the HLE reasoning exam without tools from 36.8 to 42.6. Against the other models in the table, the update has the top score on DeepSWE, Automation-Bench, Agents' Last Exam and Apex Bench, while Opus 5 scores higher on the remaining seven, including Terminal-Bench 4.0 at 51.8. These are DeepSeek's own measurements, and the card gives no figure for the claimed reduction in output length.
For anyone running it locally, the release ships without a Jinja chat template, the file that normally tells software how to lay out a conversation for the model. DeepSeek instead provides a Python reference encoder with test cases and a separate Rust toolkit, deepseek-recipe, that converts common API request formats into the model's prompt format and parses its output back. The card recommends a 1M- , a temperature of 1.0 and a maximum output of at least 256K tokens.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.

Checking sign-in…
Loading comments…