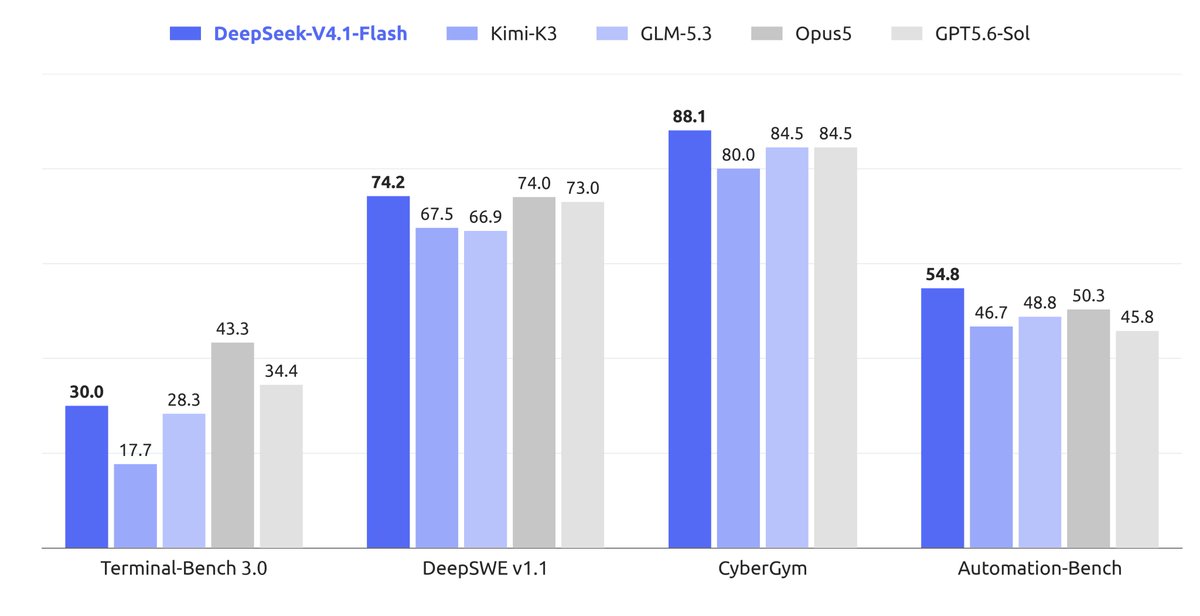
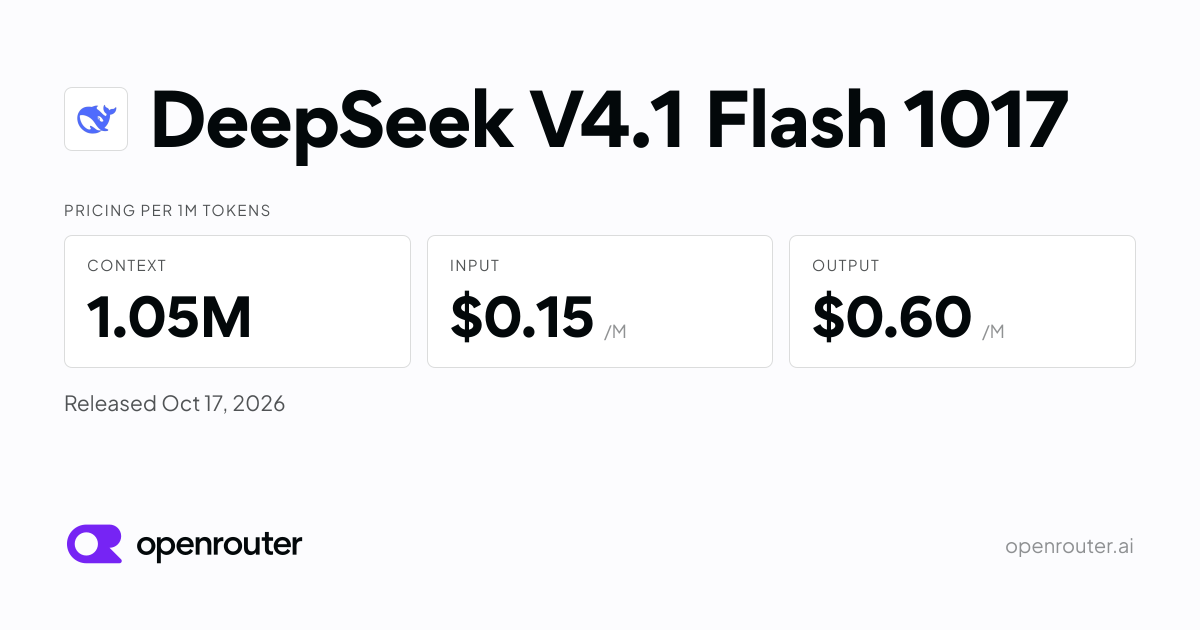
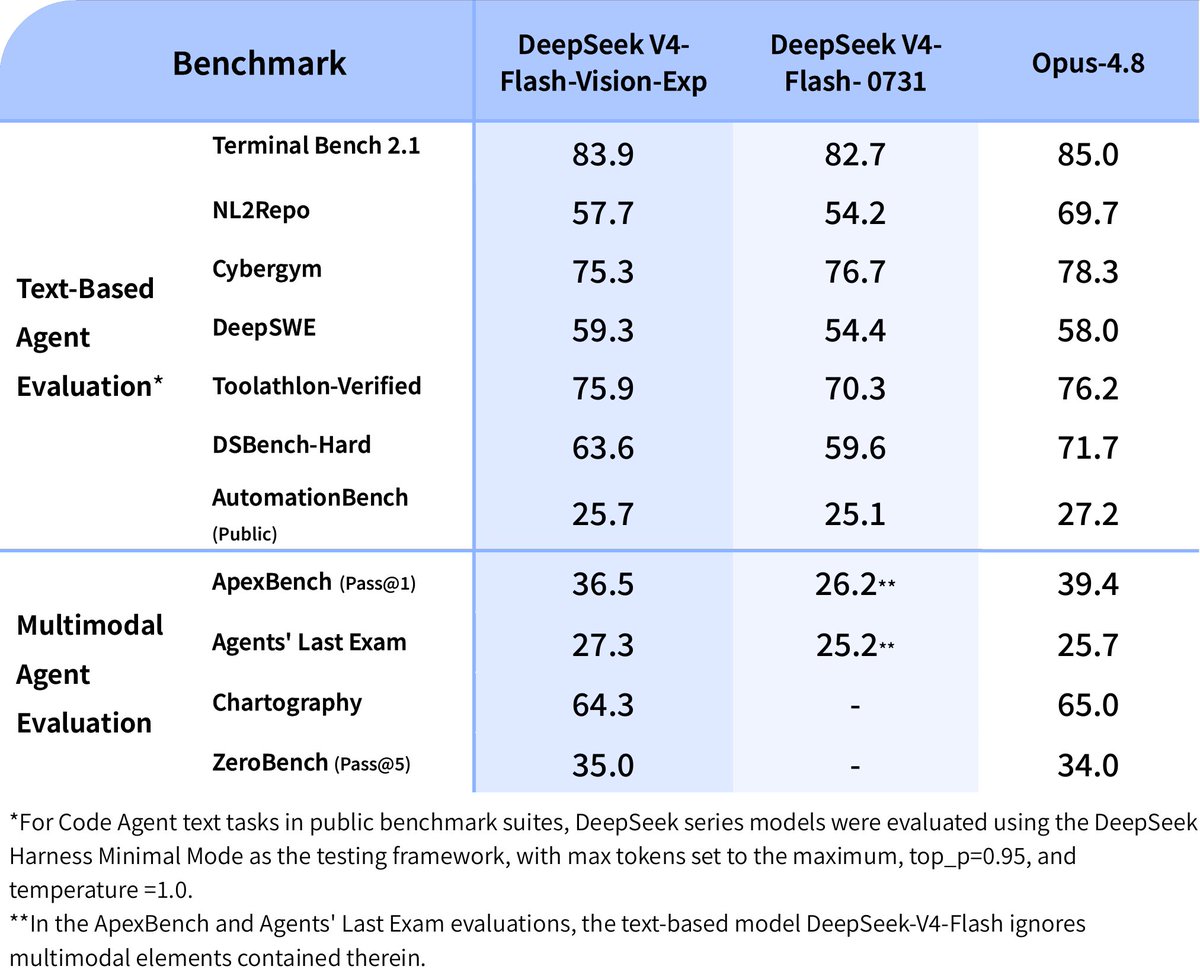
DeepSeek's V4.1 Flash separates processing an incoming prompt from generating the answer. Its model card describes a causal encoder followed by a decoder, activating 8 billion parameters per token during input processing and 16 billion during output generation. The model accepts images and text and supports up to one million tokens of context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →. DeepSeek presents the design as a way to make input-heavy AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → work more efficient, where substantial material must be processed before an answer is produced. The parameter figures describe the computation activated at each stage, rather than the model's total size or a measured application-level speedup.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.